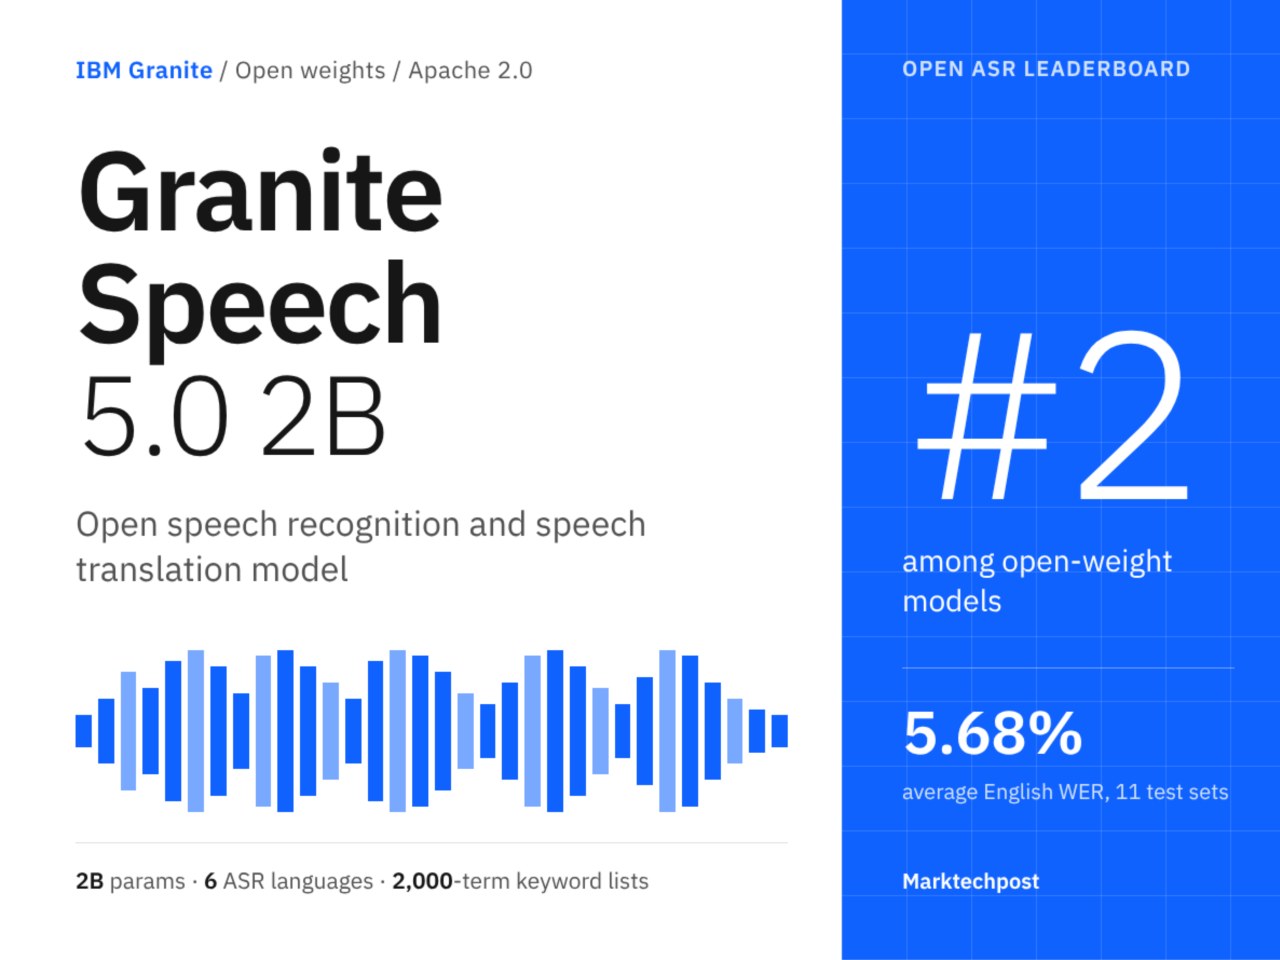
IBM has introduced Granite Speech 5.0 2B, a model designed for multilingual transcription and translation. The architecture consists of a 16-block Conformer speech encoder, a 2-layer window q-former for acoustic embedding downsampling, and a base LLM derived from granite-4.0-1b-base, extended to 16k positions using YaRN and LoRA.
The model was trained on 390,000 hours of public audio and synthetic data over 40 days using 8 H100 GPUs. On the Open ASR Leaderboard, it achieved a 5.68% average English word error rate (WER). Performance varies by dataset, with 0.99% WER on LibriSpeech Clean and 13.79% on private conversational sets.
In multilingual tasks, the model shows a 2.60% WER for Portuguese and 3.50% for Spanish, while Japanese performance is 10.74%. Translation capabilities include CoVoST BLEU scores of 53.6 for Portuguese and 40.1 for German. Keyword biasing significantly improves F1 scores, reaching 90.1 on the Earnings-22 dataset.
The release also includes the Granite Speech 5.0 Turbo CTC, which maintains a 470M footprint and supports 7 languages with native punctuation. Throughput for this version has increased to 19,870 RTFx. Additionally, the Granite Speech 4.1 2B Plus update improves long-form WER from 13.53 to 10.22.
Granite Speech 5.0 2B is compatible with Transformers, vLLM, llama.cpp, and mlx-audio. For GGUF format, IBM suggests using Q8_0 quantization, noting that lower-bit versions may experience accuracy degradation when processing audio clips longer than one minute.