AI
Meta’s Omnilingual ASR Recognized by TIME
Meta’s Omnilingual ASR system, which supports over 1,600 languages, has been recognized as one of TIME’s Best Inventions of 2026.
October 16, 2026, 01:35 AM·Crypto Briefing

Meta’s Omnilingual ASR system, which supports over 1,600 languages, has been recognized as one of TIME’s Best Inventions of 2026.
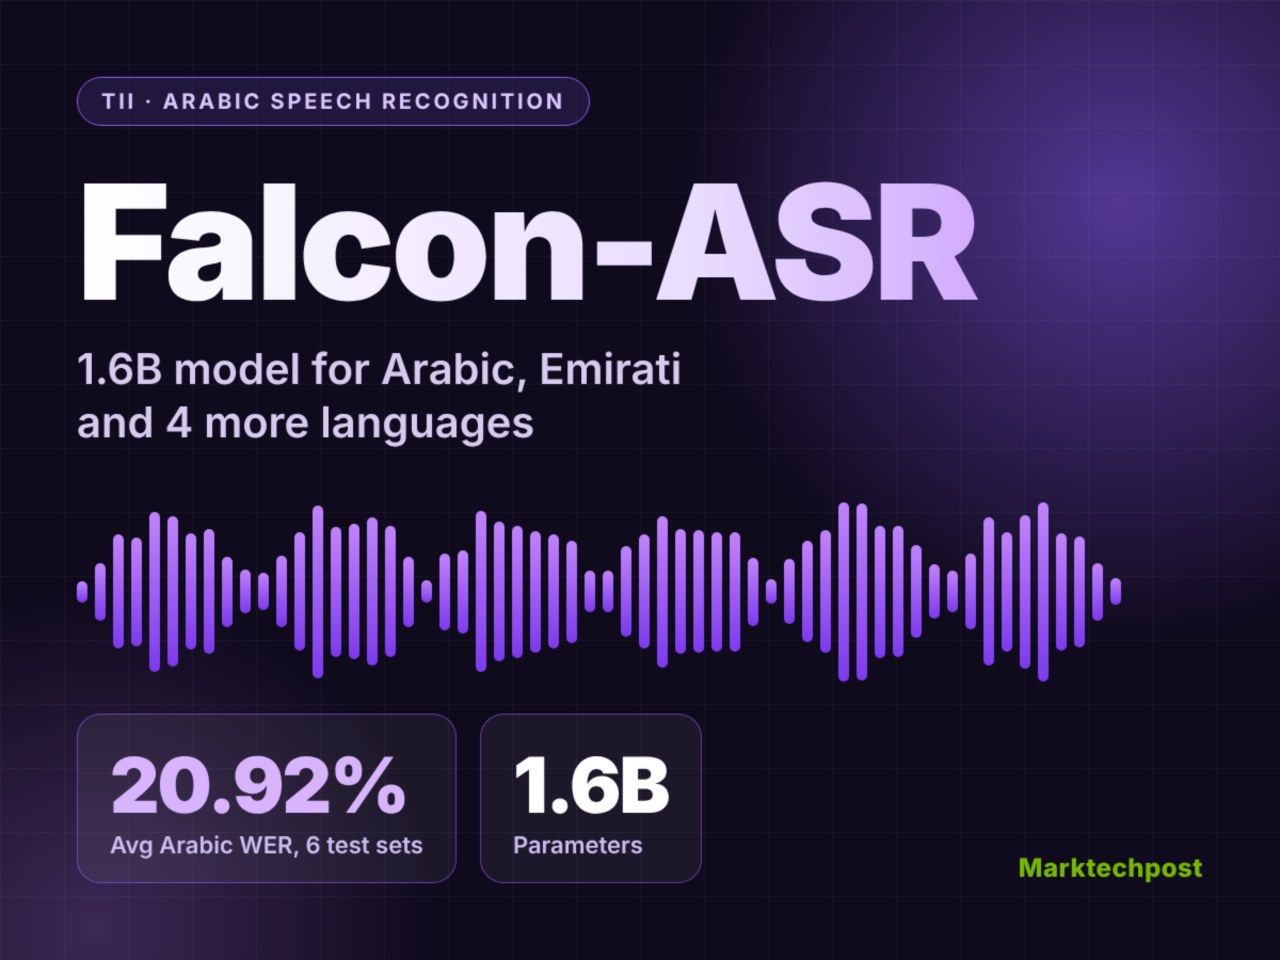
TII has launched Falcon-ASR, a 1.6B parameter speech-to-text model supporting Arabic and four other languages, achieving a 20.92% WER in internal tests.
Willow Care Inc. has partnered with CoreWeave to manage its AI training infrastructure, aiming to replace traditional keyboard input with voice-based interaction within two years.
Anthropic has launched a program allowing users to voluntarily share voice data to improve the speech recognition and response capabilities of its Claude AI models.
Microsoft has launched three new AI models for real-time voice processing, including a top-ranked streaming transcription tool and two text-to-speech engines with voice cloning capabilities.
MTS reported that its service for the hearing impaired processed over 496,000 calls across Russia, including the Sakhalin region, between March and August 2026.
Helsingborg-based AI startup Klang has raised €1,32 million to fuel international expansion and research, while simultaneously releasing an open-source speech-to-text model for Swedish.
MTS reported that its AI-powered service for the hearing impaired has facilitated nearly 500,000 calls across Russia in the last six months.
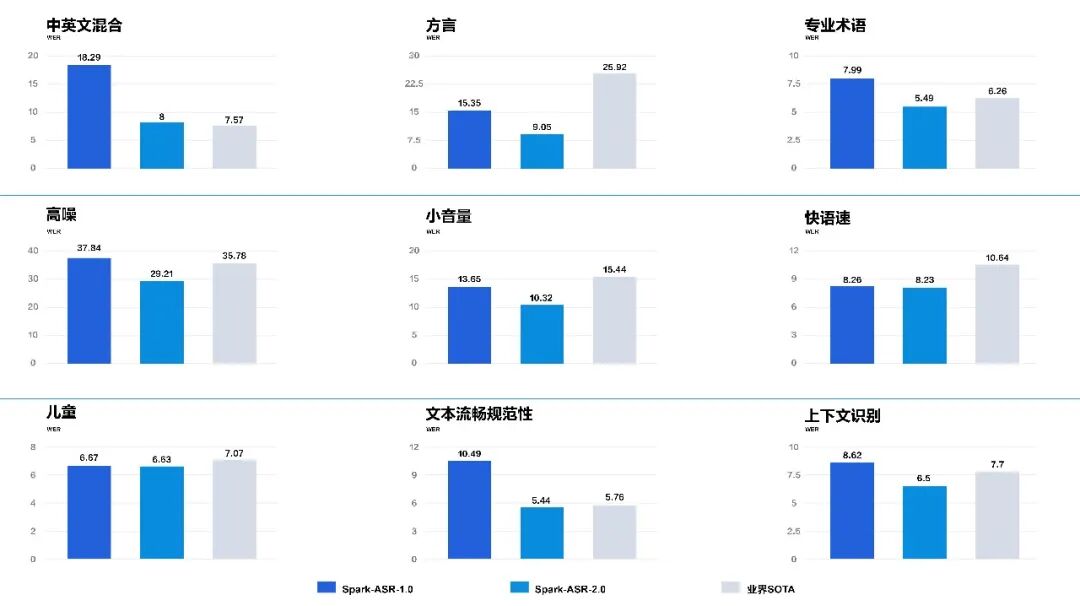
iFlytek has unveiled its Spark-ASR-2.0 speech recognition model, which offers improved accuracy in complex acoustic environments with only a 10 percent increase in inference costs.
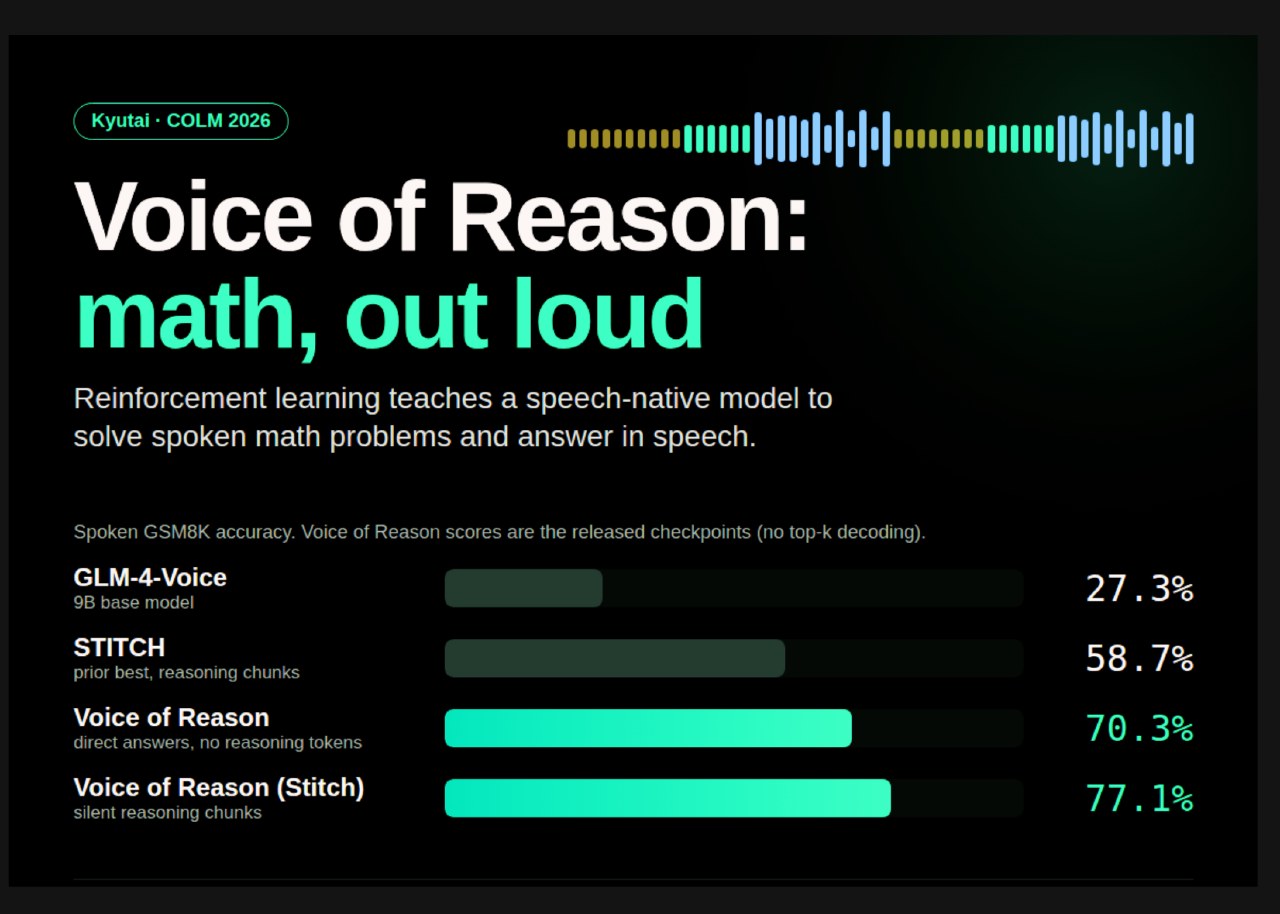
Kyutai has launched Voice of Reason, a speech-native model that applies reinforcement learning to solve spoken math problems, achieving up to 77.1% on the GSM8K benchmark.
StepStar has launched the StepAudio 3 series, featuring five models that lead global benchmarks in real-time interaction, speech recognition, and audio generation.
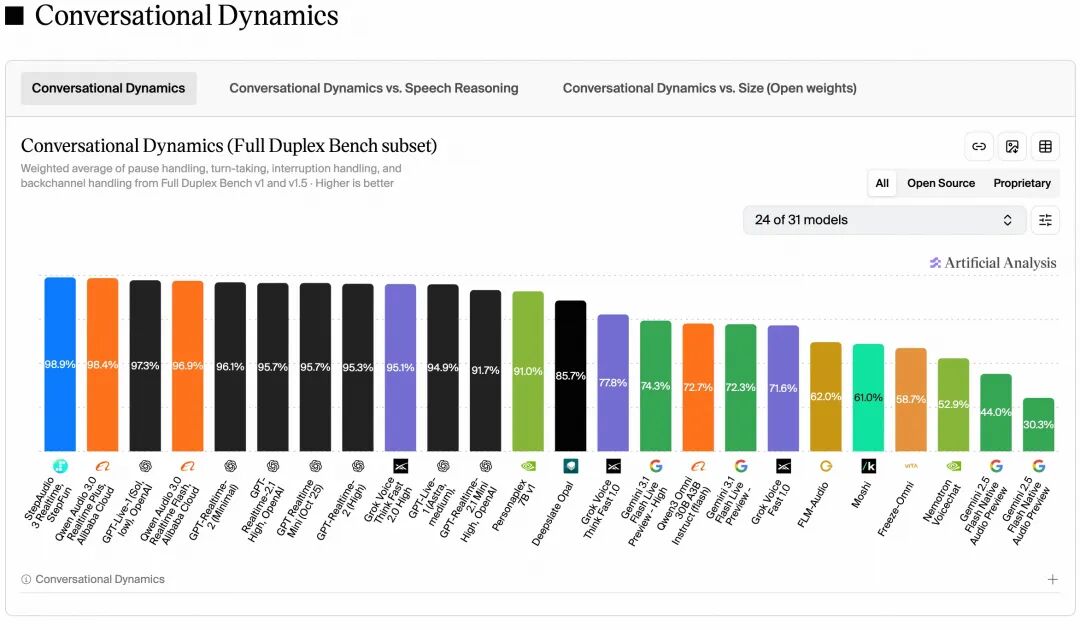
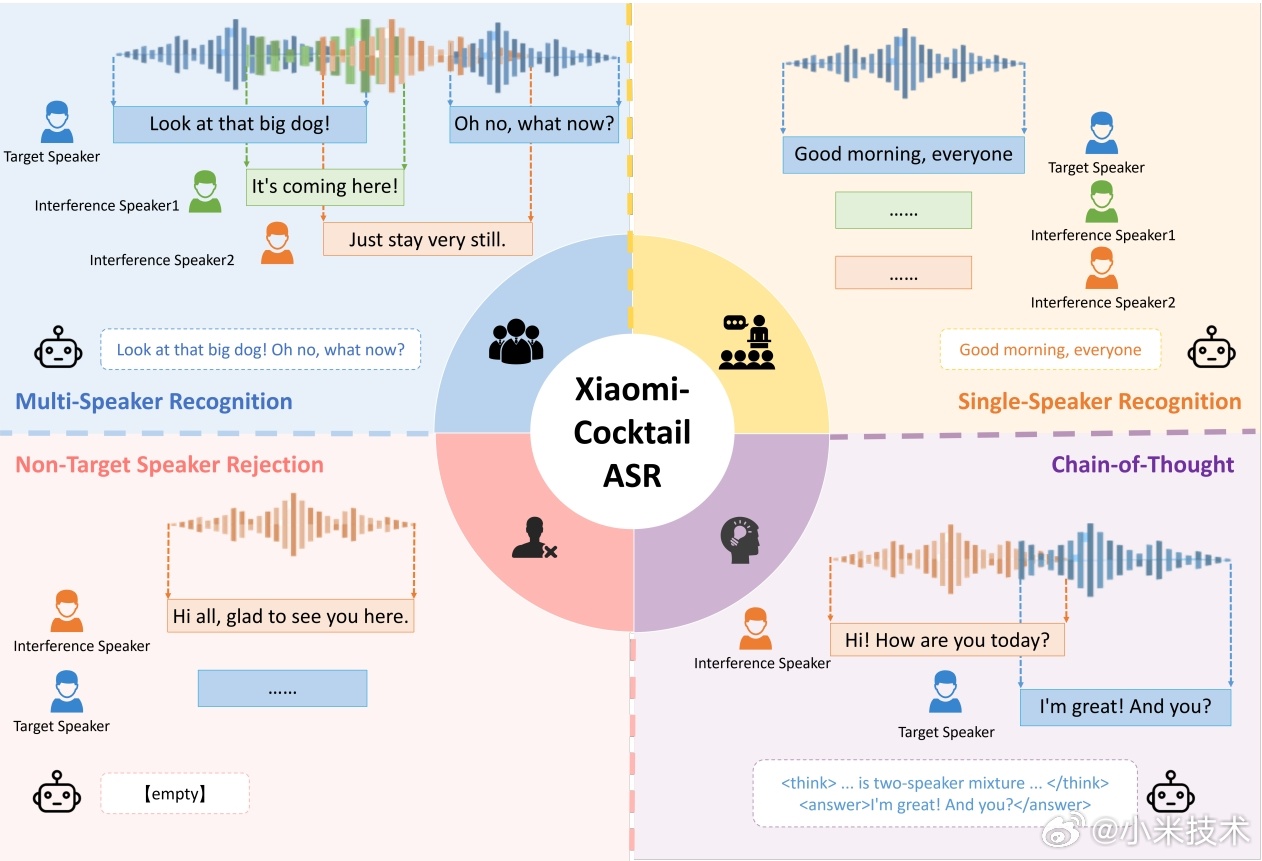
Xiaomi has launched an open-source AI model, CocktailASR-1, capable of isolating and transcribing a specific speaker's voice within multi-speaker audio recordings.
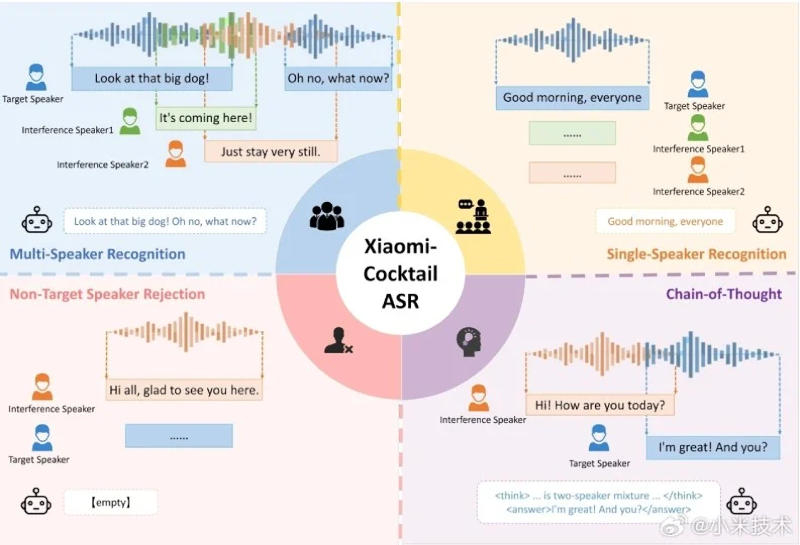
Xiaomi has open-sourced its new CocktailASR-1 model, designed to isolate and transcribe a specific speaker's voice in multi-person environments using end-to-end LLM architecture.
Kryptonite researchers have created a language identification model that is 10 times faster and 5 times lighter than the original 1-billion-parameter baseline.
Kryptonite has developed a compact speech language identification model that is 10 times faster and 5 times smaller than its analog.