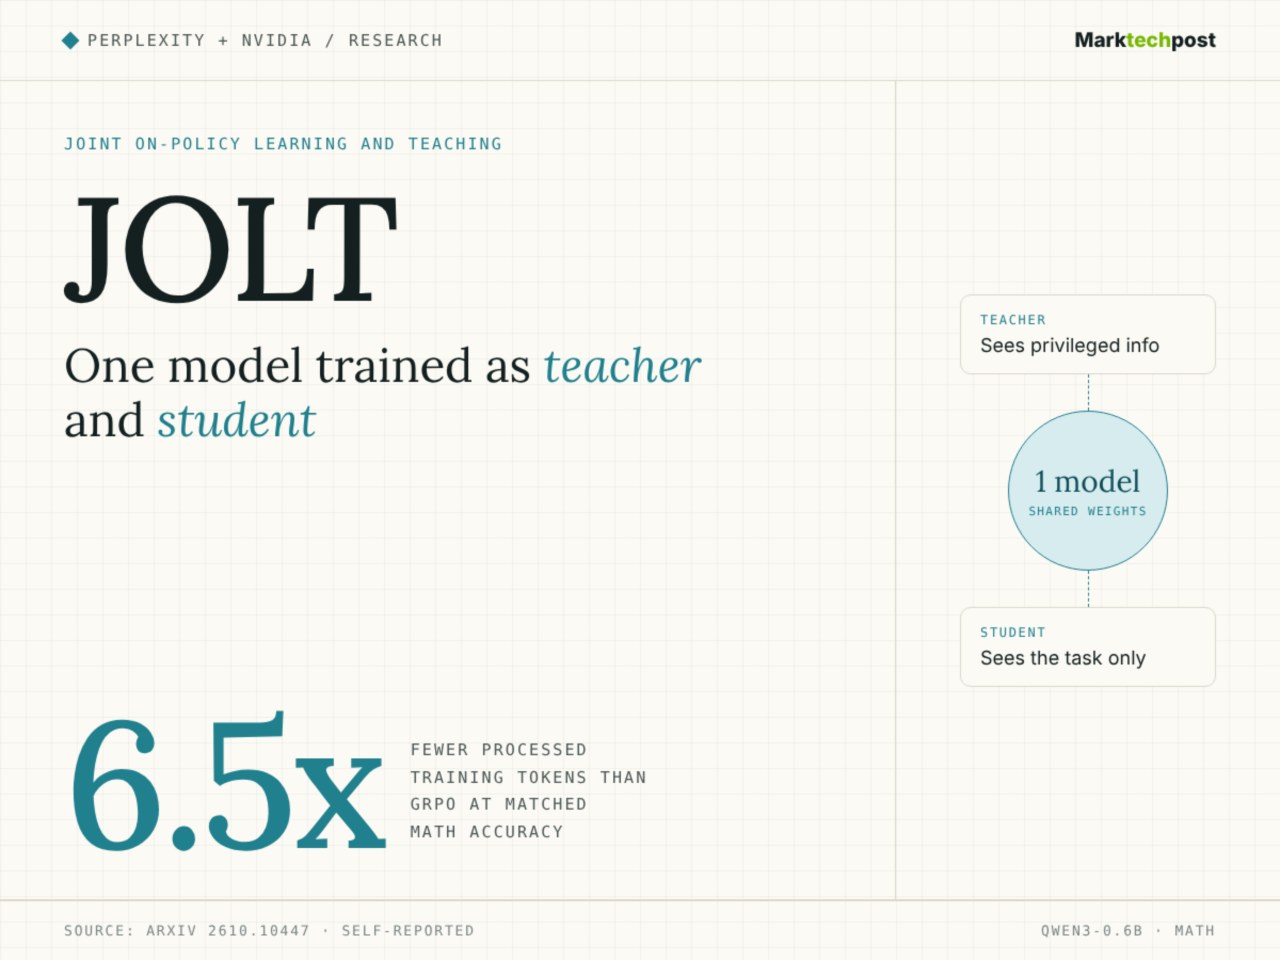
Perplexity and NVIDIA researchers have introduced JOLT, a self-distillation method for reinforcement learning. The approach builds upon On-Policy Self-Distillation (OPSD) by utilizing a reward-consistent teacher model. This teacher favors high-advantage actions while remaining aligned with the student model's policy to prevent the guidance gap observed in traditional distillation.
In testing across five different base models and settings, JOLT+ consistently outperformed the GRPO baseline. On the GSM8K benchmark, it gained 1.5 points, while achieving gains of 4.2 on MATH, 3.0 on LCBv6, and 9.9 on AppWorld. For Terminal-Bench 2.1, JOLT+ reached 10.96% pass@1 and 34.83% pass@32, compared to 8.25% and 30.34% for GRPO.
The research highlights significant improvements in training efficiency. On the MATH benchmark, JOLT achieved 63.44% accuracy using 1.30 million processed training tokens, whereas GRPO required 8.40 million tokens, representing a 6.5x reduction. When counting only completion tokens, the efficiency gap increases to approximately 13x.
JOLT also demonstrates a higher performance ceiling compared to existing methods. The model plateaus near 72% accuracy on the MATH dataset. In contrast, the GRPO baseline levels off at approximately 70%, while OPSD reaches about 62%.