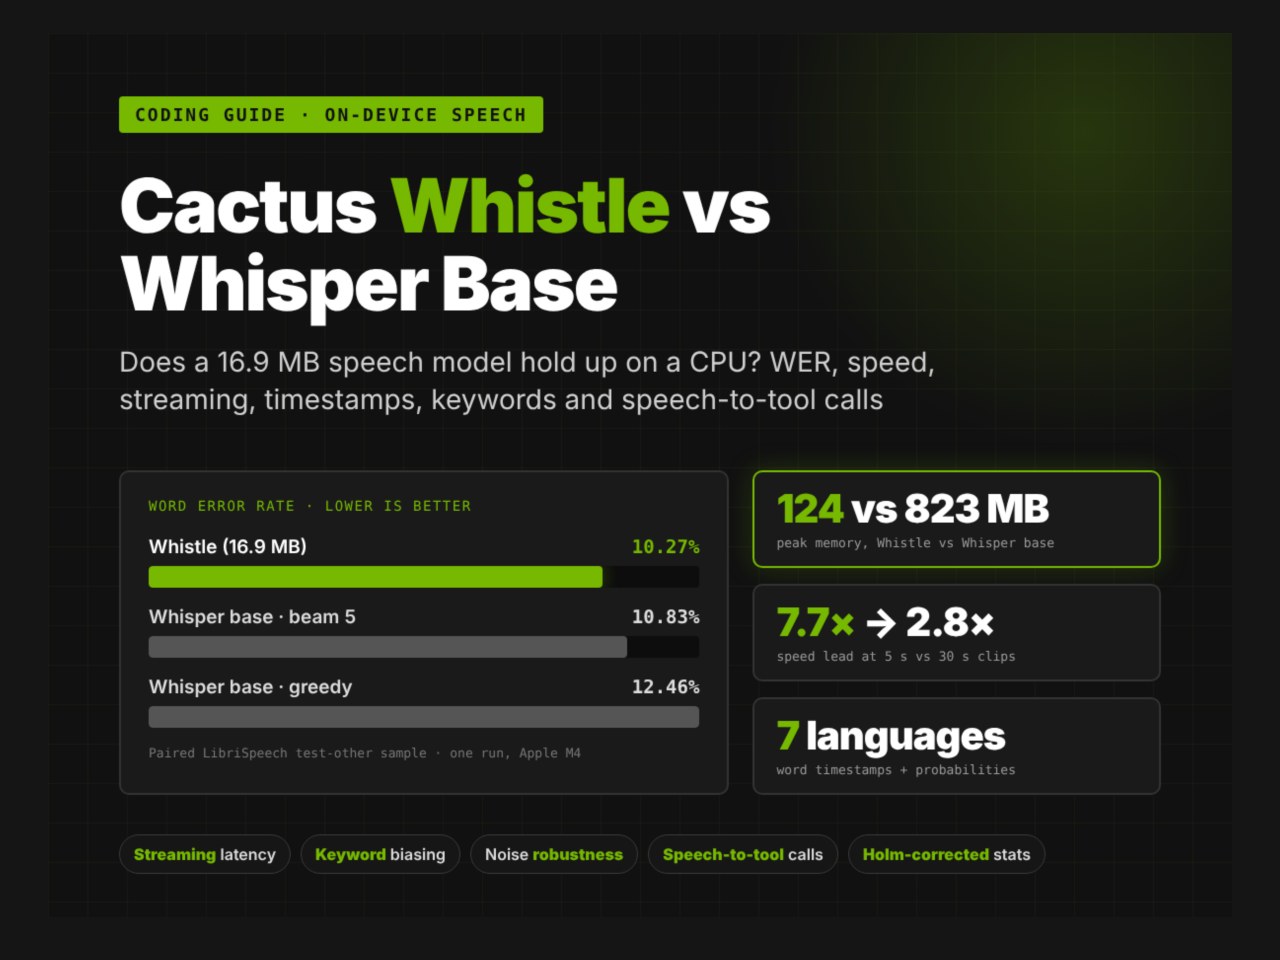
The analysis evaluates the performance of the Whistle speech-to-text model, which features a 16.9 MB weight file. The testing process involves installing cactus-needle version 3.2.0 and pinning specific Hugging Face repository revisions for weights and engine files to ensure reproducibility.
Researchers conducted tests using the LibriSpeech dataset, sampling 300 clips per split. The evaluation excludes audio segments exceeding the 30-second single-pass window of the Whistle model. For comparative analysis, paired subsets of 100 clips from test-other and 60 clips from test-clean were processed through OpenAI Whisper.
The methodology employs a seeded sample and bootstrap intervals for speaker clusters to determine performance differences. A result is considered significant only if the 95% confidence interval excludes zero and the Holm-adjusted p-value remains below 0.05.
Technical benchmarks were performed on a CPU. The system records metrics including word timestamps, probability scores, and engine time to the first token. The testing framework includes automated retries for API requests and audio resampling to 16 kHz.