Researchers from AIRI, MIPT, MTUCI, and HSE have developed a new approach for detecting speech deepfakes, named HIR-SDD. The method addresses the limitations of existing detection systems, which often struggle with adaptability to new audio domains and lack interpretability.
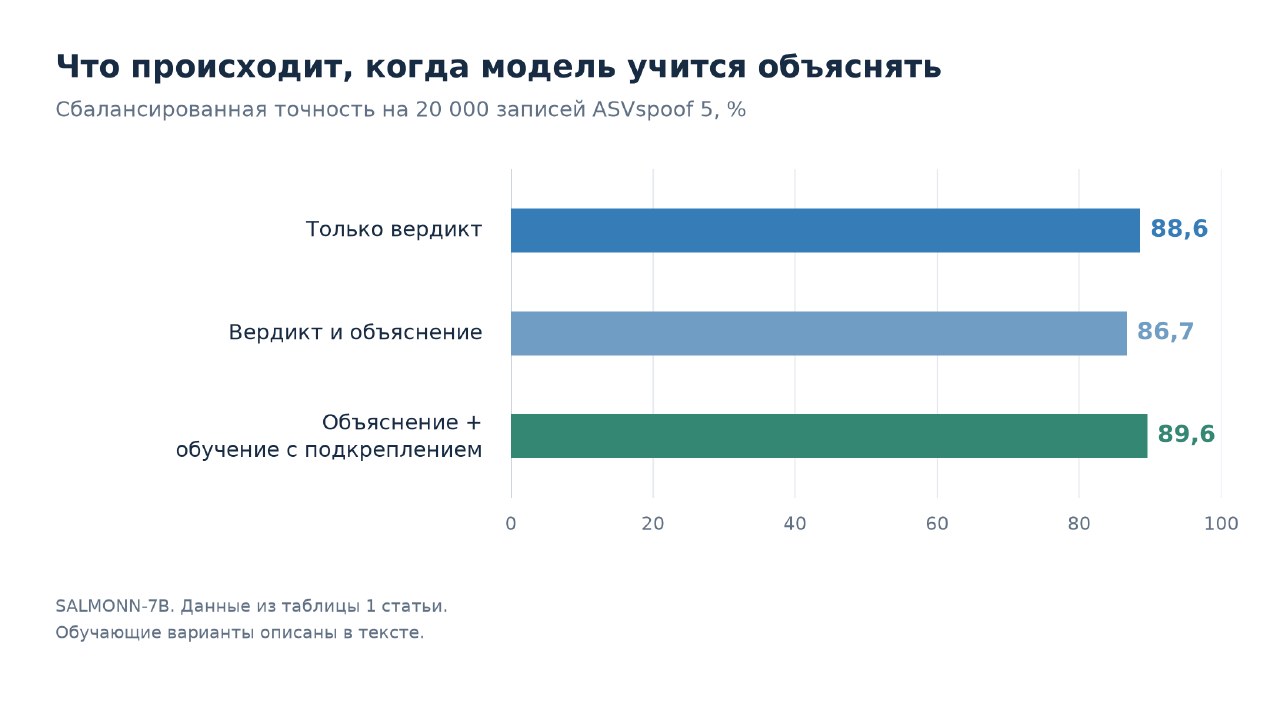
The HIR-SDD method integrates large audio-language models with step-by-step reasoning. This reasoning is derived from a dataset featuring human-annotated labels, allowing the system to provide human-understandable explanations for its classification of audio as genuine or synthetic.
The team presented their findings at the Interspeech conference, which took place in Australia at the end of September. The research focuses on improving the reliability of speech deepfake detection as generative audio models are increasingly used in fraudulent activities.