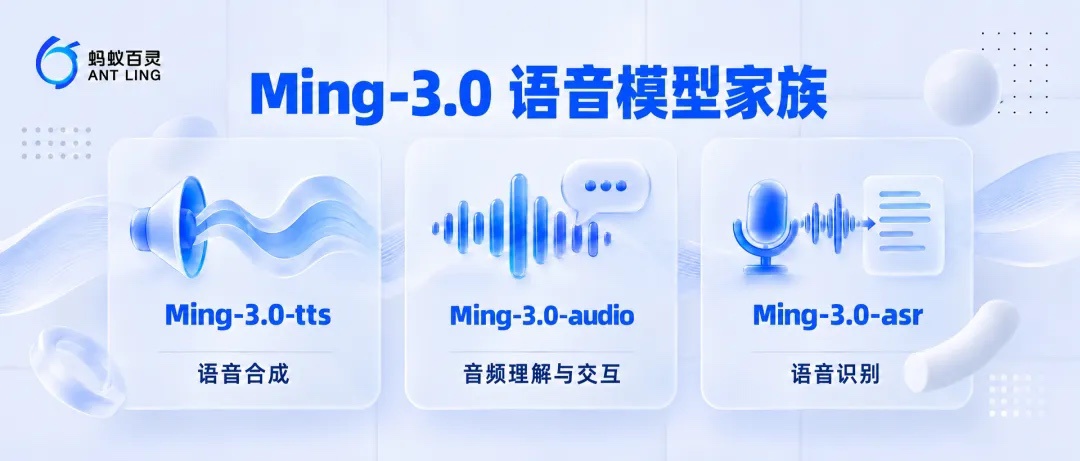
Ant Group has released its Ming-3.0 speech model series as open source. The collection includes five distinct models categorized into three main functions: speech synthesis, audio understanding and dialogue, and speech recognition.
The Ming-3.0-tts series features Voice Design, allowing users to define voice characteristics via text descriptions or reference audio. A director mode enables creators to specify emotional nuances, emphasis on specific words, and pacing for generated speech.
The Ming-3.0-audio-flash and tiny models are designed for processing long-form audio. They perform transcription, summarization, and analysis, providing structured output while retaining speaker identity and environmental context.
The Ming-3.0-asr-tiny model utilizes a dataset covering Mandarin, English, and various dialects. It integrates with language model foundations to improve recognition accuracy in real-world business applications.
The company has integrated these models into internal services, including the Afu app, medical voice cloning, and smart office tools. Developers can access APIs for specific models via the Ling Studio platform.