

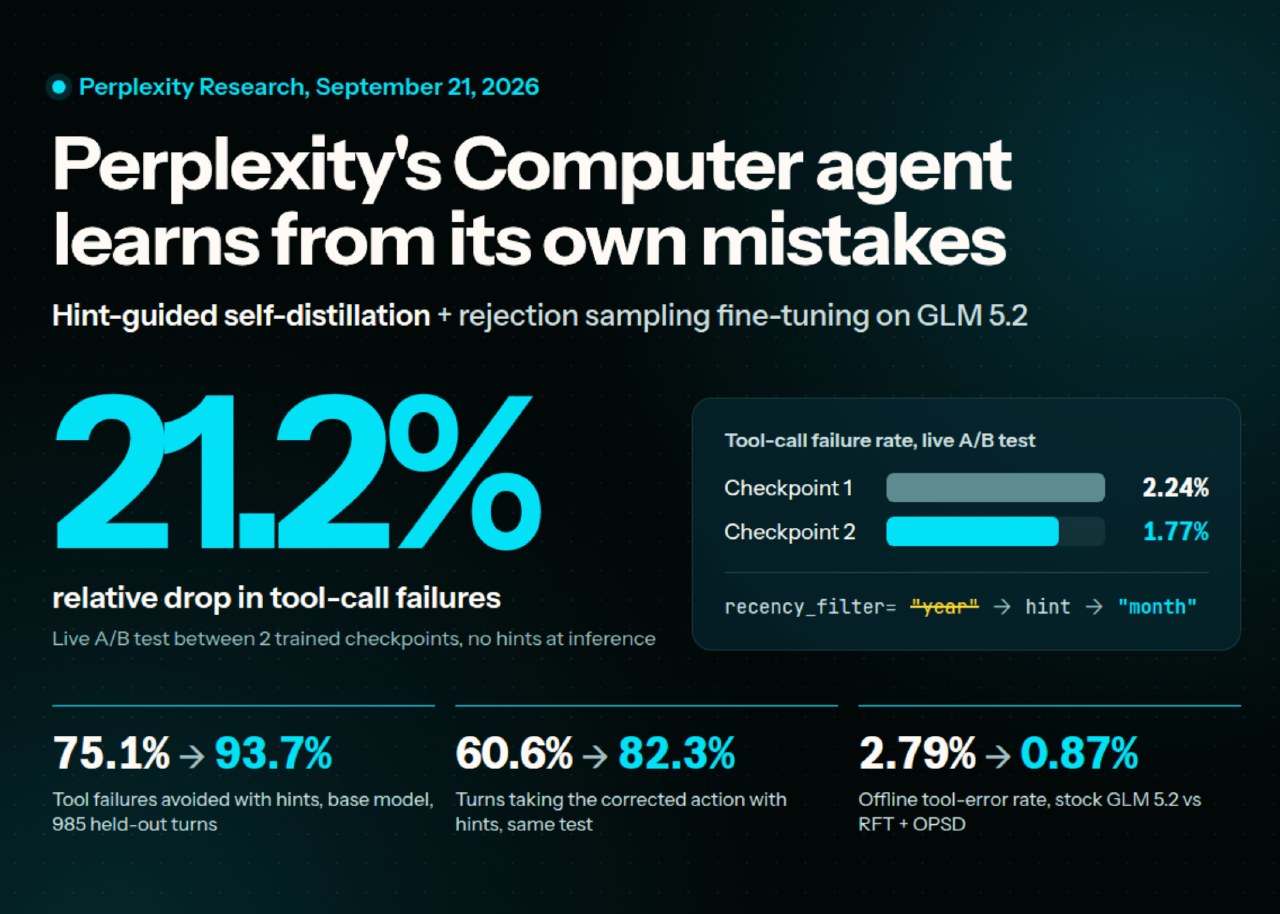
Perplexity has introduced a new training method for its computer agent, utilizing hint-guided self-distillation to address errors. The company does not plan to release the training code or post-trained weights, making the model available exclusively as an option within Perplexity Computer. The underlying base model, GLM 5.2, remains accessible on Hugging Face.
The training process improves upon standard rejection sampling by analyzing both successful and failed sessions. While successful outcomes are used for imitation, the team specifically isolates mistakes within these sessions to provide correction targets. Unsuccessful sessions are also utilized to identify and correct errors, rather than being discarded entirely.
The corrective mechanism, known as On-Policy Self-Distillation, runs the GLM 5.2 checkpoint twice. A teacher pass incorporates a hint—a corrective instruction based on existing information—while the student pass does not. The teacher’s token probabilities serve as a soft target to guide the student model, with the combined loss function balancing cross-entropy and KL divergence.
Data for the pipeline is sourced from Perplexity Computer sessions, excluding those containing personally identifiable information or opted-out user data. To ensure quality, sessions must be rated 4 or 5 on a 5-point difficulty scale by an LLM judge, and final outputs require approval from two independent LLM judges. Feedback analysis also involves three LLM judges to identify the specific turn responsible for errors.



