

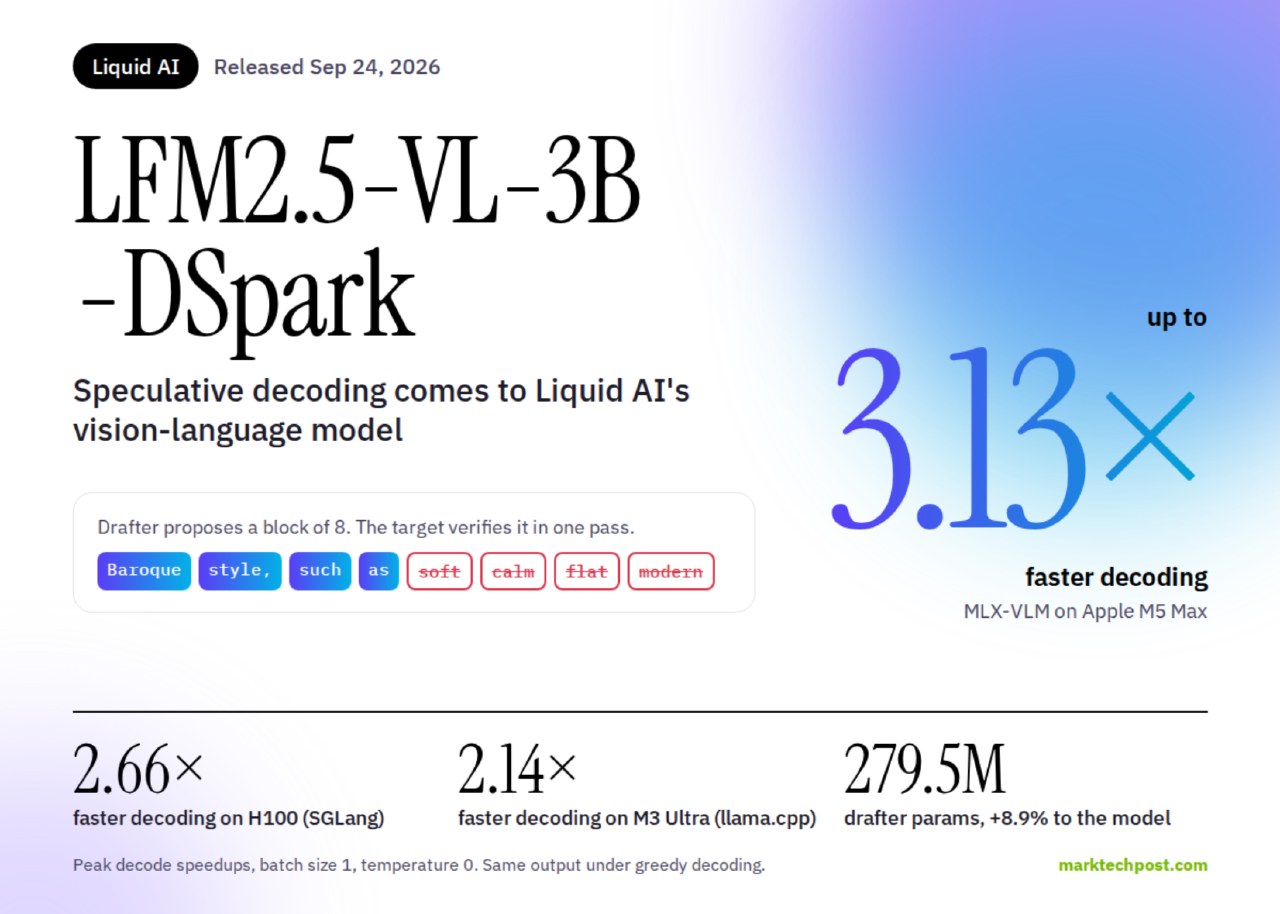
Liquid AI has introduced LFM2.5-VL-3B-DSpark, an experimental vision-language model featuring speculative decoding. The release is available on Hugging Face in Safetensors and GGUF formats, with support for SGLang, MLX-VLM, and llama.cpp. It is distributed under the LFM Open License v1.0, permitting free commercial use for companies with annual revenue under $10 million.
The DSpark architecture utilizes a simplified attention-only drafter that predicts multiple tokens ahead. The system uses a block size of 8 or 9, with the drafter increasing the parameter count by 8.9%. Training was conducted on AMD hardware over 10 epochs using supervised fine-tuning data. The model was evaluated across six task types, including general VQA and image captioning, using the MMSpec benchmark.
Performance metrics show speedups of up to 3.13x in decoding and 2.62x in end-to-end processing on M5 Max hardware. Throughput advantages were also observed on H100 GPUs. The company notes that speculative decoding effectiveness depends on the workload and temperature settings, as higher temperatures can decrease acceptance rates.
The release requires specific software versions, including SGLang v0.5.19 or newer and MLX-VLM v0.7.2 or newer. While MLX-VLM currently supports only greedy sampling for DSpark, llama.cpp allows pairing GGUF drafters with the target model. The company clarified that acceleration for quantized models is not included in this release.



