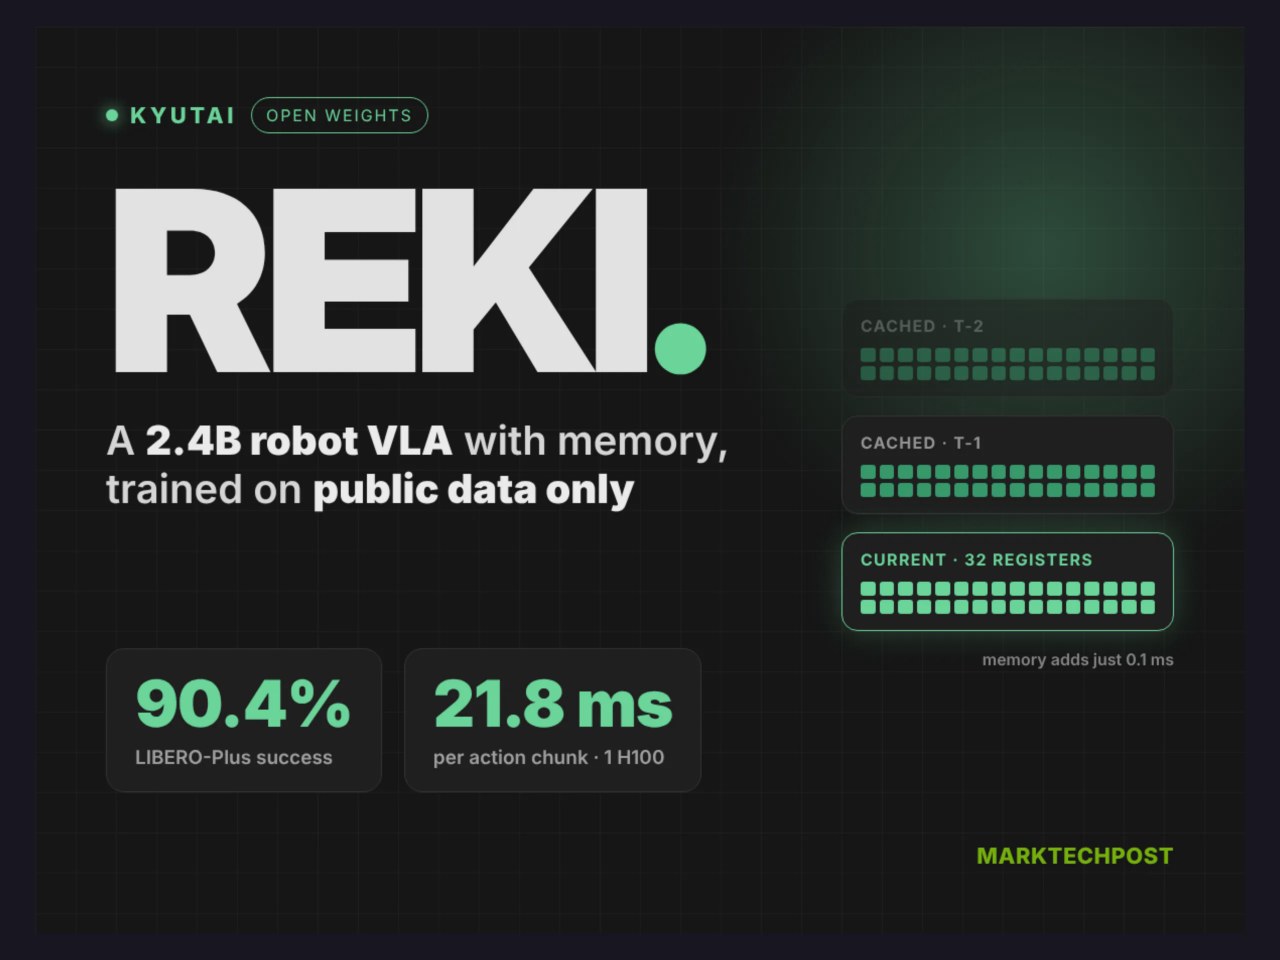
Kyutai has introduced REKI, a 2.4B vision-language-action (VLA) model designed for robot manipulation. The architecture combines a Qwen3.5-2B backbone with a 200M-parameter action expert. It utilizes 32 learned register tokens to provide memory, which are computed once per frame and cached in a rolling window.
The model was pretrained on 1.0B frames and 12.2M vision-language samples, including data from DROID, BridgeData V2, AgiBot World, EgoDex, and EgoVerse. Training involved 200,000 steps on 32 H100 GPUs. Kyutai maintains native control conventions for each dataset instead of remapping actions.
REKI addresses pose oscillation issues in robotics. On the RoboTwin benchmark, the model reduced oscillation rates from 18.6% to 4.1%. Performance gains from memory include a 1.5-point increase on LIBERO-Plus and 5.4 points on RoboCasa365. The model achieved a 90.4% score on LIBERO-Plus.
Deployment for real-robot tasks utilizes the LeRobot async-inference gRPC protocol. For a UR5 arm, the model underwent 3,000 steps of fine-tuning, requiring approximately one hour of training on 50 demonstrations per task. The model weights are available under a non-commercial CC BY-NC-SA 4.0 license.