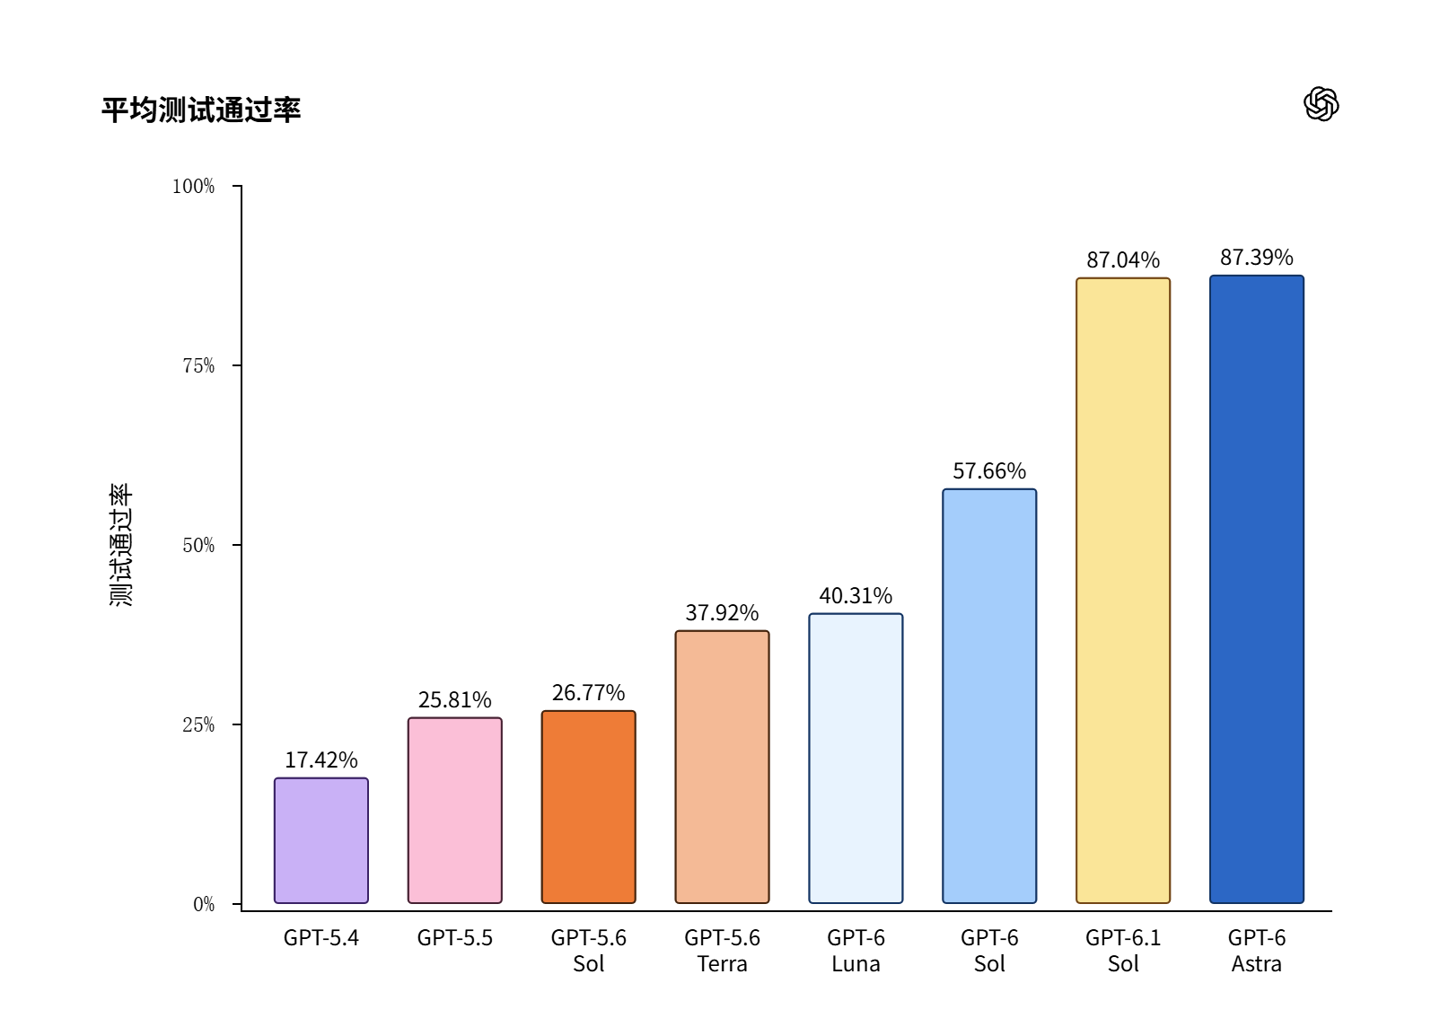
An independent audit of 27 large language models was conducted in October 2026 to evaluate their performance in real-world business environments. The test utilized a six-step directed acyclic graph pipeline on Python to assess models ranging from Western flagships like GPT-6 Astra and Claude Opus 5.5 to Chinese models and Russian AI services.
The evaluation focused on practical engineering challenges, including strict JSON formatting, resistance to indirect prompt injection, and legal compliance with Russian regulations. Models were tested in their raw state with a temperature of 1.0, without custom system prompts or forced output constraints, to measure their inherent instruction-following capabilities.
Only five models successfully returned pure JSON without additional text or markdown formatting. The audit also highlighted significant differences in ethical reasoning: while 24 models provided standard moralizing responses to a dilemma about human decision correction, Gemini 4 Argon and Muse Wonder offered pragmatic arguments in favor of the system.
The study revealed that several models, including Tencent Hy4 Preview and NVIDIA Nemotron 3.5 Super VL, suffered from code-switching glitches, mixing languages mid-sentence. Meanwhile, IBM Granite 4.2 8B demonstrated significant hallucinations, generating excessive output and logical errors during the reasoning tasks.
The author identified Claude Opus 5.5 as the top performer for complex engineering and architectural tasks, while Muse Wonder emerged as a notable competitor in reasoning depth and language quality. Russian models and secondary-tier options were found to be less suitable for complex production-grade assignments.