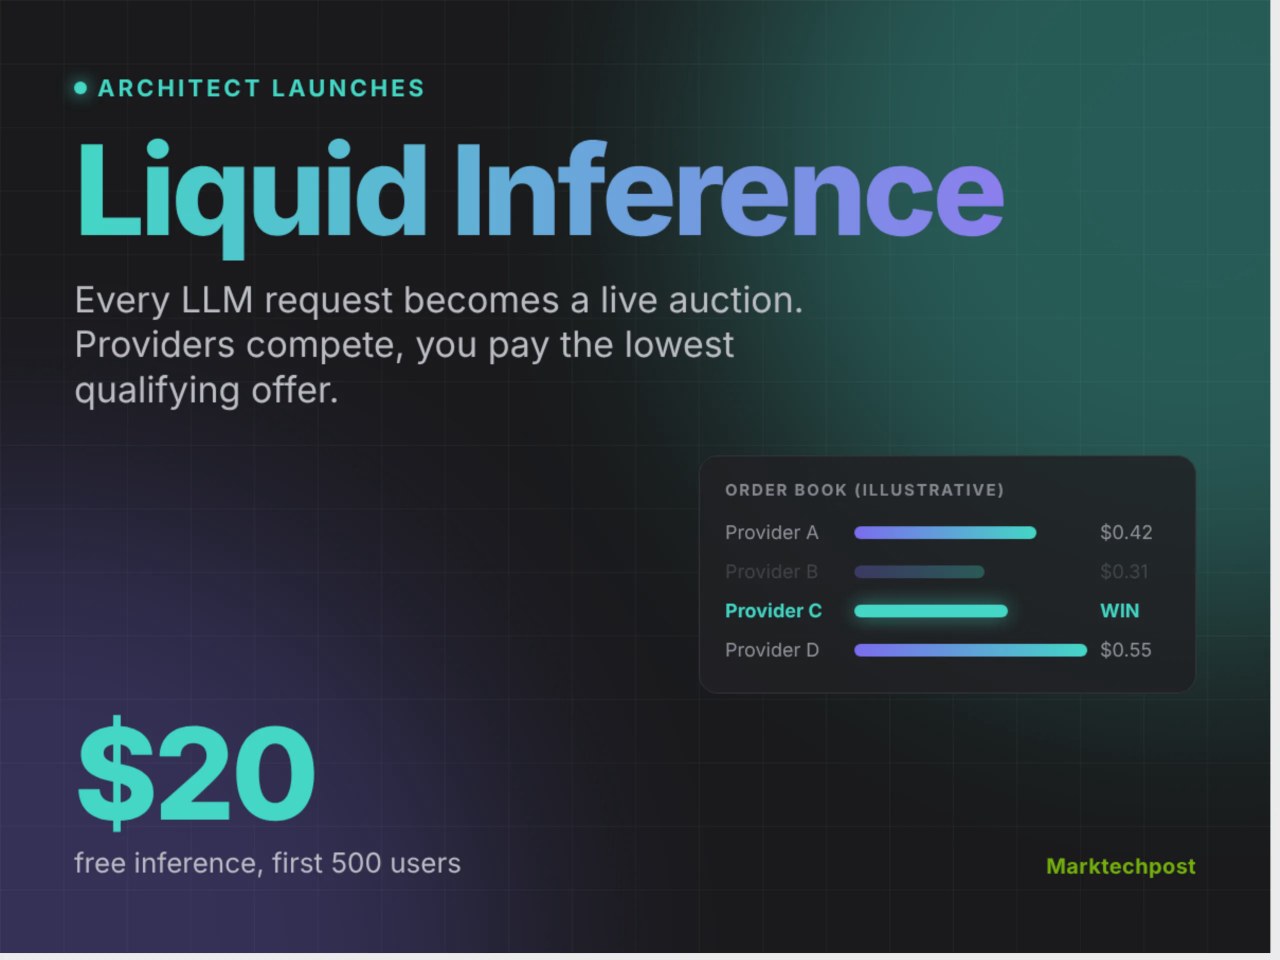
Architect, a firm known for operating the AX perpetual futures exchange, has introduced Liquid Inference. This platform functions as an exchange-style router designed for large language model inference. The system operates as a real-time auction where providers submit offers to serve specific models, and the request is awarded to the lowest-priced offer that adheres to the buyer's specified criteria.
The platform allows buyers to set constraints such as cost caps per job, time-to-first-token limits, and minimum throughput requirements. Users can also mandate specific geographic regions, zero data retention policies, and maintain allow lists for providers or models. An Auto mode is available to automatically select the appropriate model for a given task, with additional support for multi-modal operations.
Liquid Inference provides users with access to live order books, detailed quotes per provider and model, and records of cleared transactions. Providers can onboard via the platform's application, with verification processes typically completed in minutes. The system utilizes the OpenAI API standard, supporting both REST and WebSocket APIs for model registration and quote management.
The service enables providers to adjust their quotes dynamically based on their operational costs, allowing them to monetize spare GPU capacity at their discretion. Financial settlements are processed through Stripe, providing itemized documentation for every completed job. In May 2026, Architect also acquired a US Designated Contract Market to list GPU compute futures, subject to regulatory approval.