

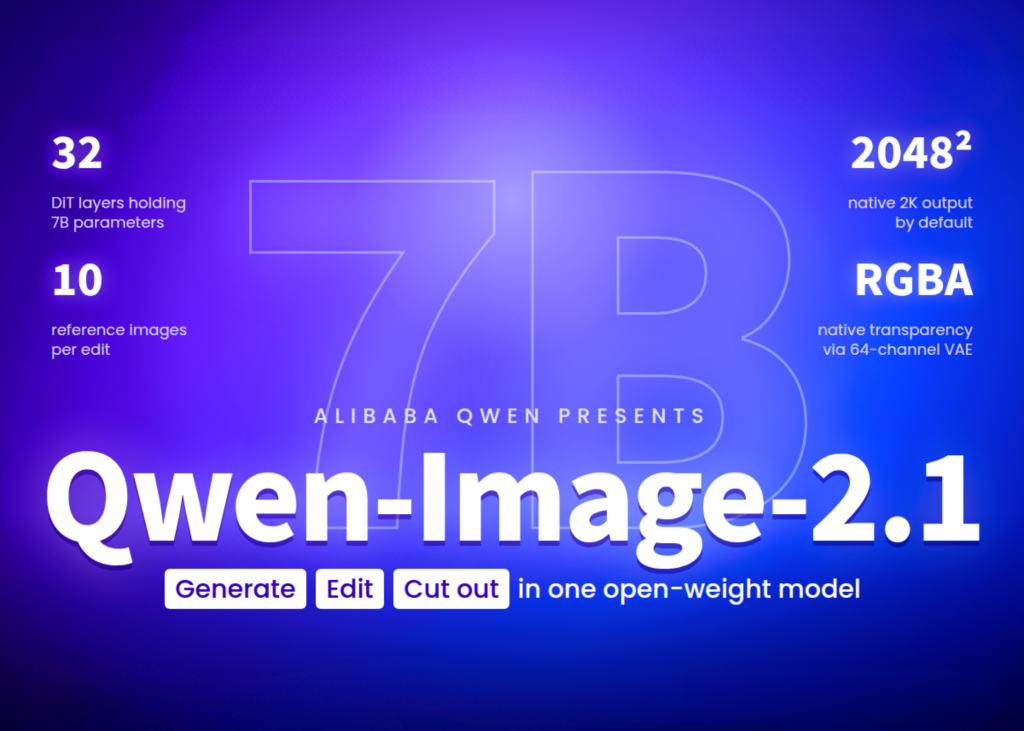
Alibaba has released Qwen-Image-2.1, an open-weight model designed for image generation and editing. The model features 7 billion parameters for the diffusion transformer, complemented by an 8 billion parameter Qwen3-VL encoder. It is currently available for research and evaluation purposes, while commercial deployment requires a separate license.
The architecture utilizes mixed-granularity attention, employing a token-level causal mask for text and a chunk-level bidirectional mask for images. This approach allows the model to compute text and input images once, reusing the prefix KV cache across denoising steps. This optimization is intended to improve performance when processing multiple reference images.
In internal testing on the Qwen-Image-Bench, the model achieved a score of 60.28. This result surpasses the FLUX 2 Max 32B model, which scored 55.33, and the Nano Banana 2.0 model, which scored 59.82. The benchmark currently lists six closed-source models with higher performance metrics.
The software supports various frameworks, including Diffusers, ComfyUI, vLLM-Omni, SGLang, and LightX2V. It is compatible with NVIDIA GPUs, AMD Radeon hardware via ROCm, and 8-chip platforms using FlagOS. Additionally, the team released two prompt-rewriting models based on Qwen3.5-VL 9B to assist with text-to-image tasks.



