Humanity's Sixth Sense Benchmark Exposes AI Vision Limitations
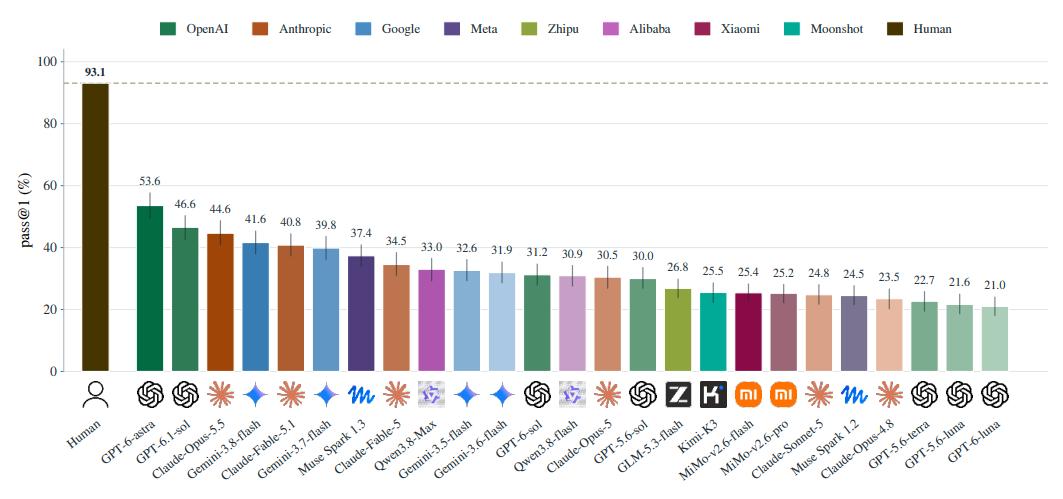
A new benchmark, Humanity's Sixth Sense, reveals that top AI models struggle to interpret visual context, achieving significantly lower accuracy than humans in intuitive reasoning tasks.

A new benchmark, Humanity's Sixth Sense, reveals that top AI models struggle to interpret visual context, achieving significantly lower accuracy than humans in intuitive reasoning tasks.

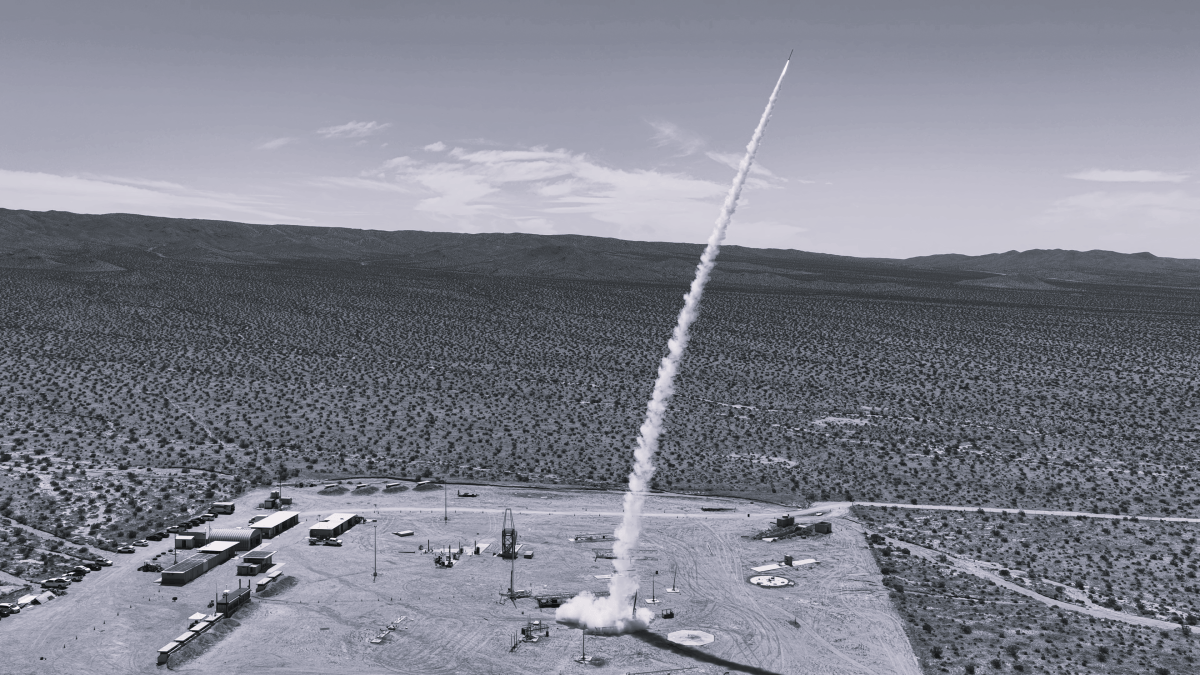
Defense startup Furientis has raised $25 million in a seed round led by Benchmark, bringing its valuation to $125 million as it scales production of low-cost missile interceptors.

An author-created benchmark tests whether LLMs claim to have subjective experience, revealing that while most models deny it, some exhibit uncertainty or generate human-like artifacts.

OpenAI has released MentalHealthBench, a new benchmark featuring 1,215 synthetic dialogues to assess how AI models handle mental health interactions across various risk levels.

Benchmark has raised $2 billion across two new funds as its partners prepare to discuss the evolving venture landscape at TechCrunch Disrupt 2026.

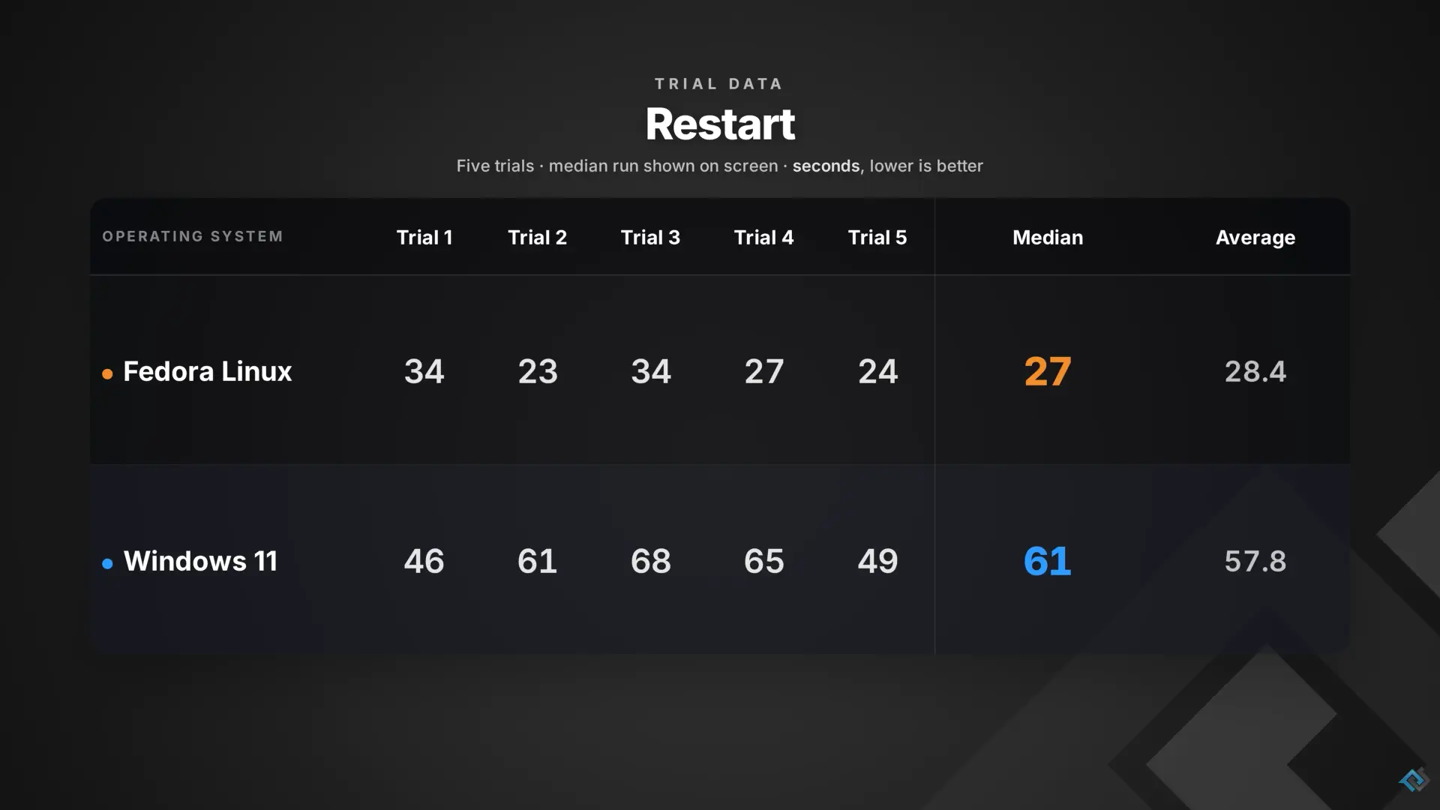
Fedora Linux outperforms Windows 11 in most common tasks on Dell XPS 13 laptops with 8GB of RAM, according to a PhoneBuff test.

A Microsoft Research study using the DELEGATE-52 benchmark reveals that frontier AI models lose up to 50% of document fidelity in extended workflows.