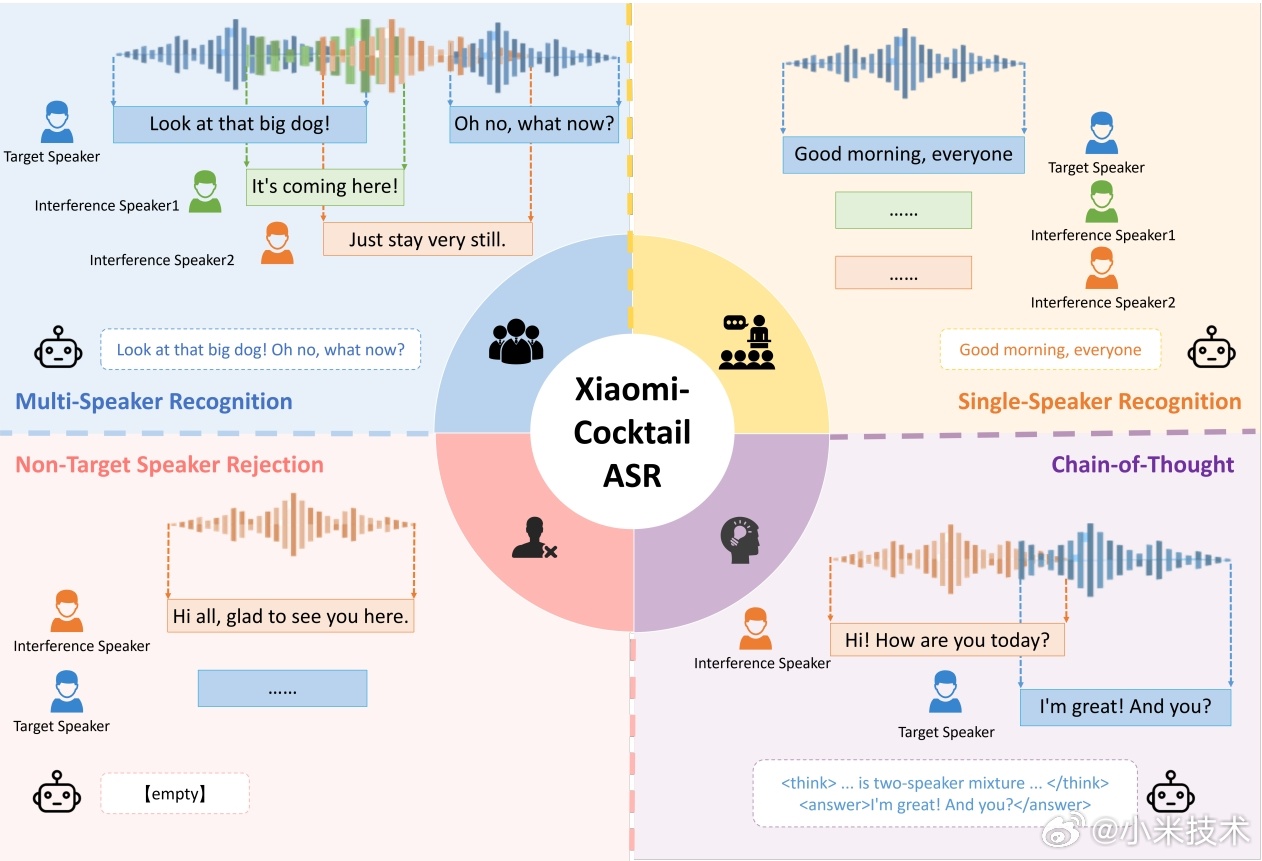
Xiaomi has officially released and open-sourced its industrial-grade target speaker speech recognition model, Xiaomi-CocktailASR-1. The technology is designed to address the cocktail party problem, which involves accurately identifying a specific speaker when multiple people are talking simultaneously.
The model utilizes an end-to-end LLM architecture. It uses a reference audio clip of the target speaker as a voiceprint prompt to extract and transcribe only the target user's speech in complex environments. According to the company, the model achieves state-of-the-art performance on multiple mainstream multi-speaker test sets.
Xiaomi-CocktailASR-1 performs on par with standard ASR models in single-speaker scenarios. It also features the ability to reject interference from non-target speakers, outputting empty text when the target is absent. Additionally, the model supports a chain-of-thought reasoning mode to provide explanations for its recognition results.