

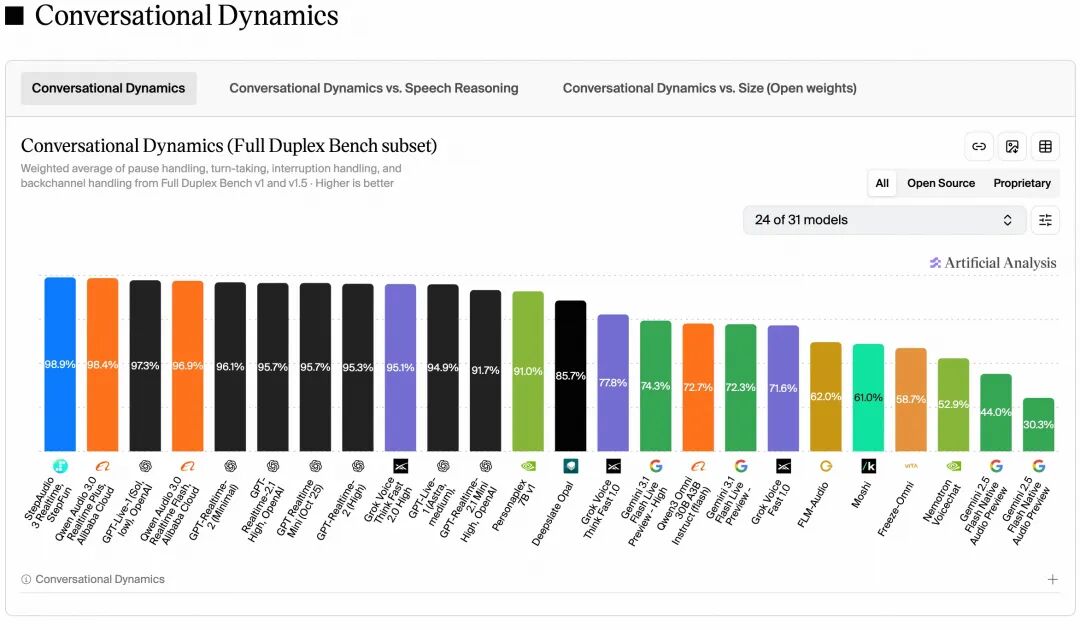
StepStar has officially released the StepAudio 3 series, which includes five models: StepAudio 3 Realtime, StepAudio 3 ASR, StepAudio 3 TTS, StepAudio 3 Gen, and StepAudio 3 Music. All models are now available on the company's open platform.
The StepAudio 3 Realtime model achieved a 98.9% score on the Artificial Analysis Conversational Dynamics leaderboard, ranking first globally. It also topped the Speech Reasoning benchmark with a 99.7% accuracy rate, supporting native full-duplex interaction and parallel processing of reasoning and speech generation.
The StepAudio 3 ASR model is designed for high-precision speech recognition, achieving a word error rate of 1.7% on the Artificial Analysis non-streaming leaderboard. It supports multiple languages, dialects, and professional terminology, making it suitable for fields like finance, law, and healthcare.
The StepAudio 3 TTS model focuses on human-like speech generation, incorporating emotional nuances, pauses, and natural speech patterns. It utilizes a streaming architecture to enable real-time interaction, allowing for dynamic adjustments in tone and rhythm based on semantic content.
The StepAudio 3 Gen model enables the generation of complex audio content, including voice, sound effects, and background music, based on text descriptions. It allows for fine-grained control over character voices and timing, streamlining production workflows for creative industries.
StepAudio 3 Music supports both zero-shot generation and interactive composition. Users can provide lyrics, melodies, or ABC notation to guide the model in creating structured musical pieces, including arrangements and accompaniment for vocal tracks.



