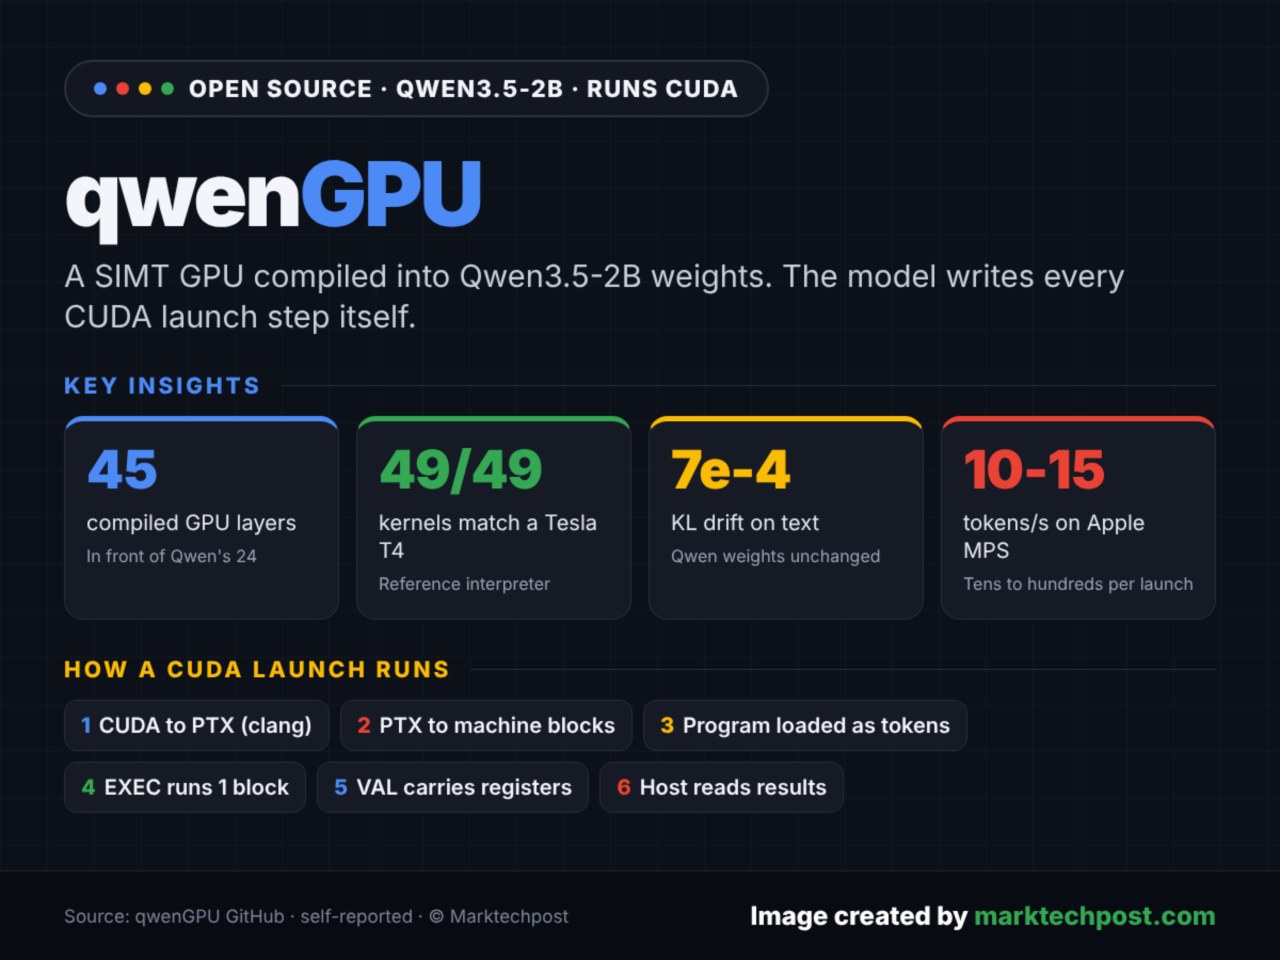
The qwenGPU project introduces a modified version of the Qwen3.5-2B model by integrating 45 compiled transformer layers ahead of the original 24 layers. These additional layers function as a 4-lane SIMT machine, utilizing the model's existing Gated DeltaNet and SwiGLU structures to serve as registers, memory, and a 32-block ROM.
The system executes CUDA code by using a host to compile kernels into PTX using clang, which are then processed by the model. The model generates execution tokens to manage register results and memory operations. In a demonstration, the model performed a dot product calculation, writing the launch in 47 tokens.
The integration does not alter the original Qwen weights, maintaining a KL divergence of approximately 7e-4. The project utilizes the transformer compiler developed by Divyansh Agrawal. Users can build the model using Python 3.11+, uv, and clang, requiring 16 GB of free memory.
While the model supports integer arithmetic, atomic operations, and warp shuffles, the developer notes that CUDA execution within the 2B model remains unreliable. The resulting checkpoint is distributed under the Apache-2.0 license, consistent with the base Qwen model.