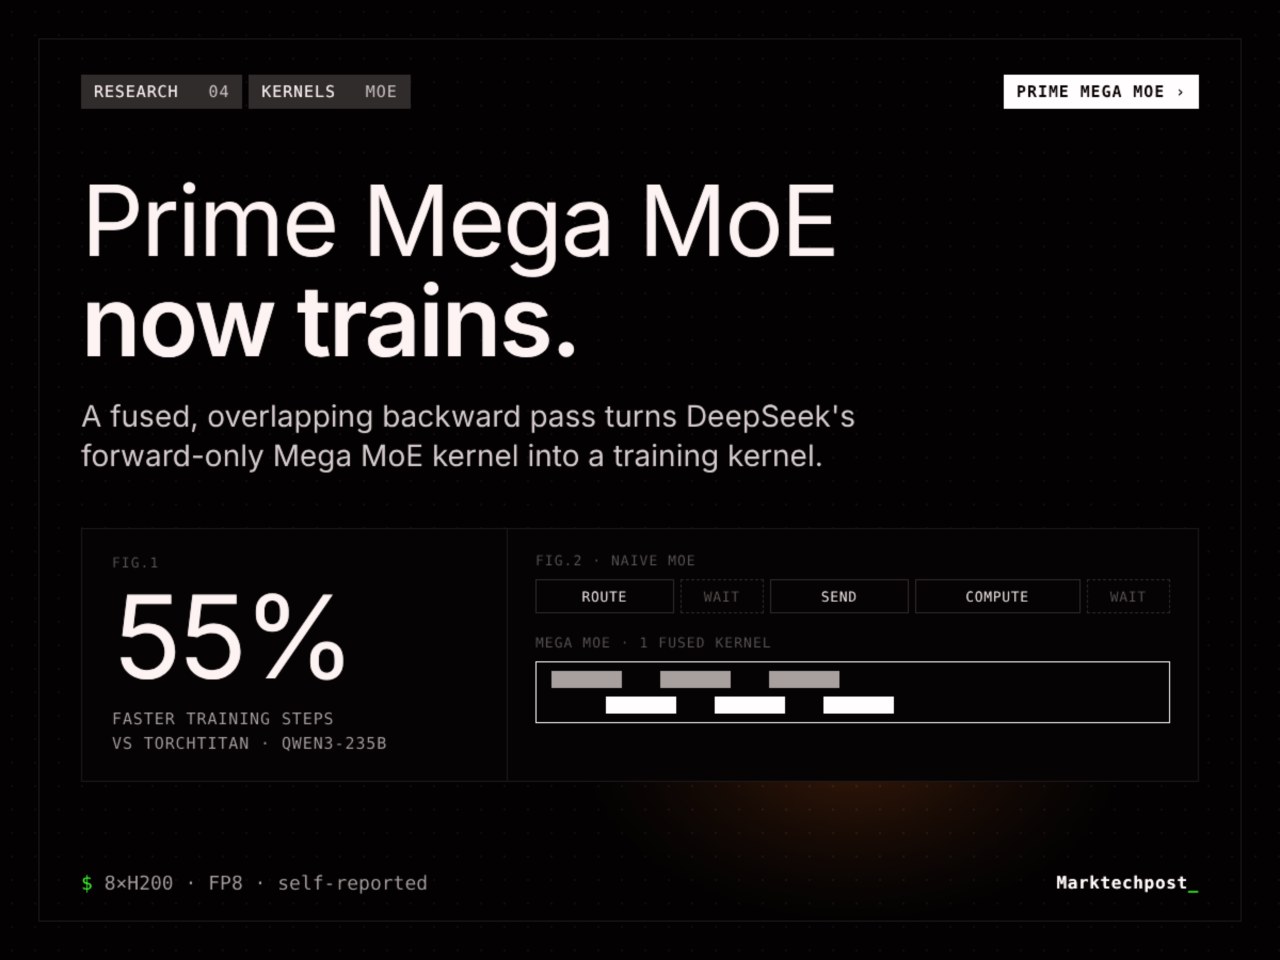
Prime Intellect has introduced Prime Mega MoE, a fused kernel designed to optimize the training of Mixture-of-Experts (MoE) models. This development builds upon the existing Mega MoE kernel found in DeepSeek’s open-source DeepGEMM library, which was originally released in April 2026.
The new kernel integrates expert-parallel dispatch, linear layers, SwiGLU, and combine operations into a single call. By utilizing GPU-only scratch buffers and overlapping data transport with computation, the system minimizes idle GPU time. Prime Intellect has added the necessary backward kernel to complement the existing forward implementation.
The software supports BF16, MXFP8 for Blackwell, and blockwise FP8 for Hopper architectures. It also includes an fp8_bwd mode, allowing for BF16 forward passes and FP8 backward passes. Users can access these kernels through a prebuilt DeepGEMM wheel available in the prime-kernels repository.
Performance testing on 8xH200 nodes with 16,384-token sequences showed significant throughput improvements. For a 30B model, throughput increased from 5,337 to 7,886 tokens per second per GPU compared to TorchTitan. For a 235B model, the rate rose from 1,094 to 1,697 tokens per second per GPU.
The company reports that the forward pass speed can be up to 3.11 times faster than standard configurations. To implement the backend, users must configure the prime-rl library by setting the dispatch type to mega_moe and selecting the desired precision within the model configuration files.