Meta Unveils Muse Spark Open With 816B Parameters
Meta has launched Muse Spark Open, an 816B parameter multimodal model with a 1M context window, available for research and commercial use under the Muse Model License.

Meta has launched Muse Spark Open, an 816B parameter multimodal model with a 1M context window, available for research and commercial use under the Muse Model License.

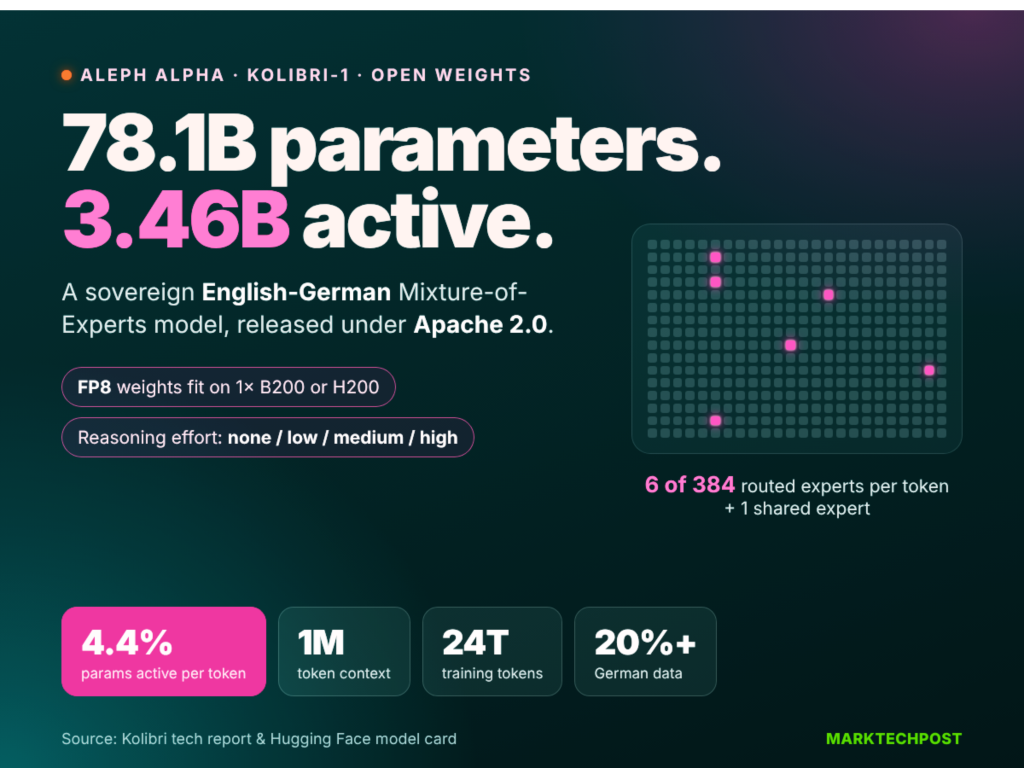
Aleph Alpha has launched Kolibri-1, a 78.1B parameter bilingual MoE model designed for English and German, featuring 3.46B active parameters and support for up to 1 million tokens of context.

A test of a 35B MoE model on a mixed setup of RTX 5080 and RTX 3060 GPUs demonstrates how layer-wise splitting mitigates PCIe bandwidth limitations.

A series of experiments on a GTX 1080 Ti reveals that the 35B MoE model outperforms larger 120B and 125B counterparts in speed and coding accuracy.

The Mixture-of-Experts architecture enables models to achieve high performance by activating only a fraction of their total parameters during inference.

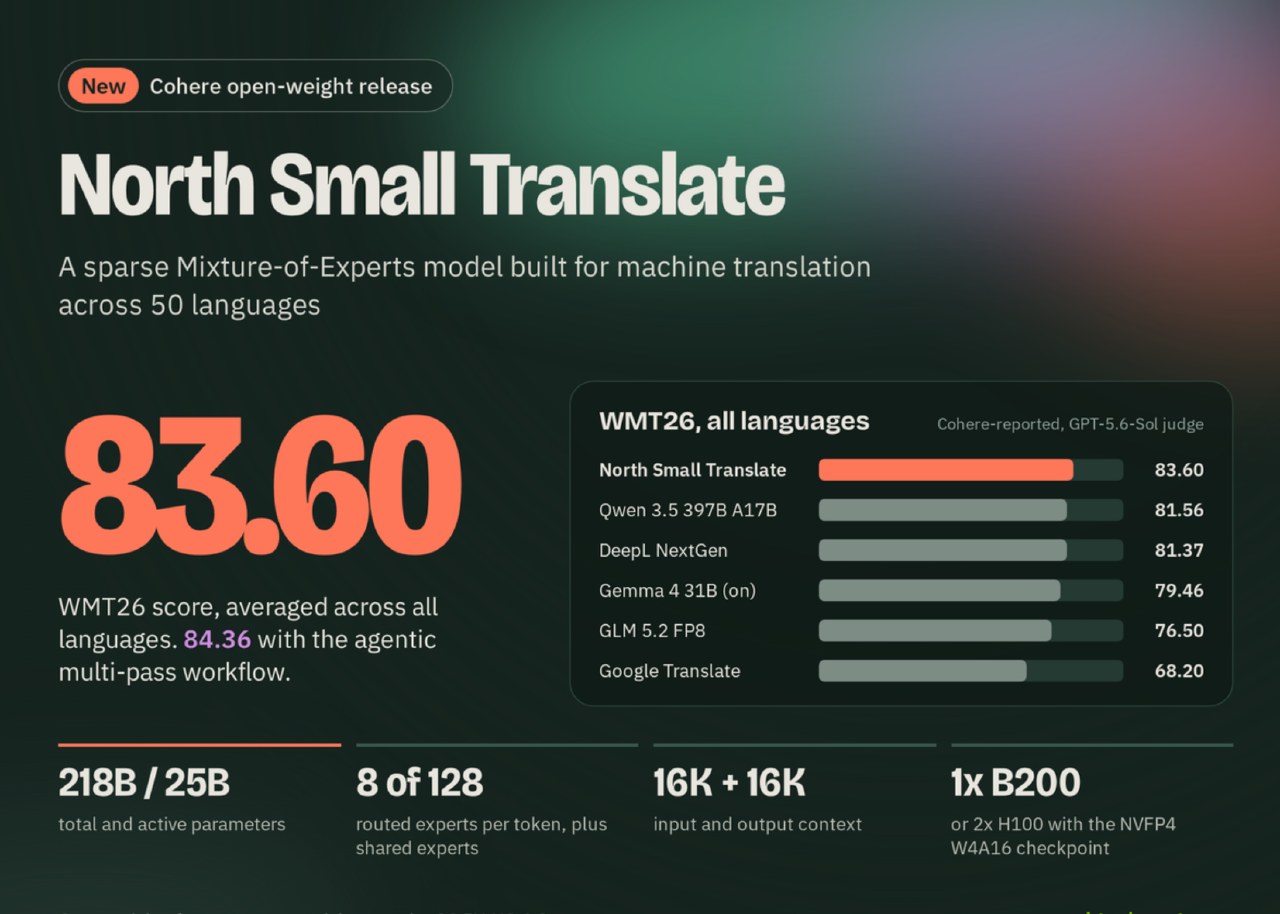
Cohere introduced North Small Translate, a 218B parameter MoE model for multilingual translation that outperforms existing benchmarks and offers lower operational costs.

The Institute of Foundation Models has unveiled the K2 Horizon series, featuring a 36B model that employs a novel Mixture-of-Value Attention architecture to optimize inference efficiency.