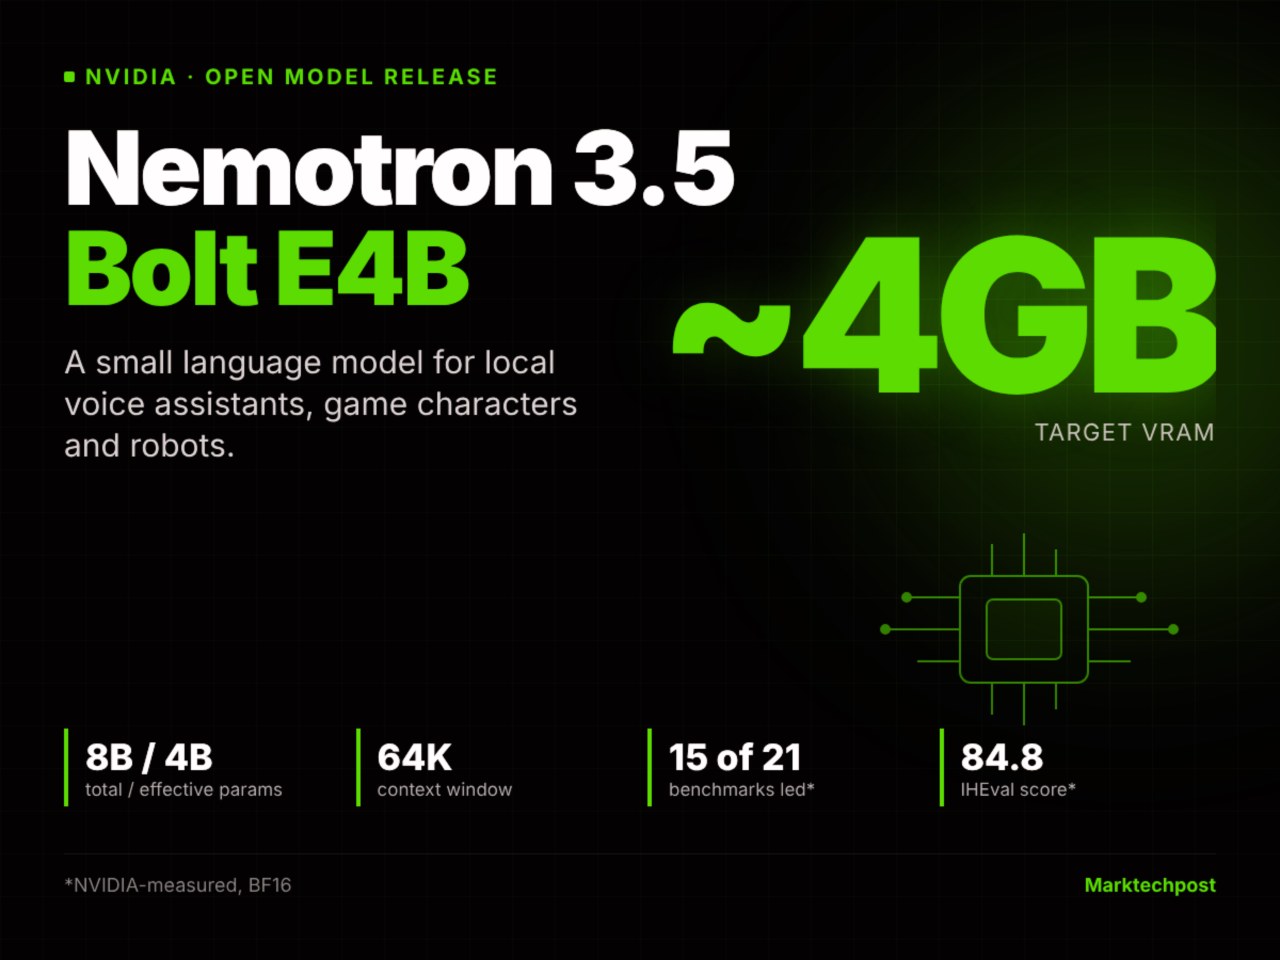
NVIDIA has introduced Nemotron 3.5 Bolt E4B, a small language model designed for local conversational agents, voice assistants, and interactive characters. The model supports multi-turn tool calling and is intended for use in embedded or industrial robotics applications.
The training process for Bolt utilized RLVR and RLHF techniques via NeMo-RL and NeMo-Gym, intentionally omitting supervised fine-tuning. NVIDIA implemented a 2:1 ratio of non-reasoning to reasoning samples during training to optimize performance.
For deployment, the model is quantized to Q4_K_M using importance-matrix calibration. When tested on an RTX 5070 with DFlash speculative decoding, the model achieved a speed of 272.6 tokens per second, surpassing the Gemma 4 E4B model.
In internal benchmarks, Bolt outperformed the Nemotron 3 Nano 4B with 40% higher average scores. While it leads in 15 out of 21 capability areas, it trails competitors like Qwen3.5-4B in specific benchmarks such as Tau2-Bench and LongBench v2.
The model is currently available through platforms including Hugging Face, Ollama, LM Studio, and Unsloth. It is also integrated into the NVIDIA NIM and the In-Game Inferencing SDK for developers.