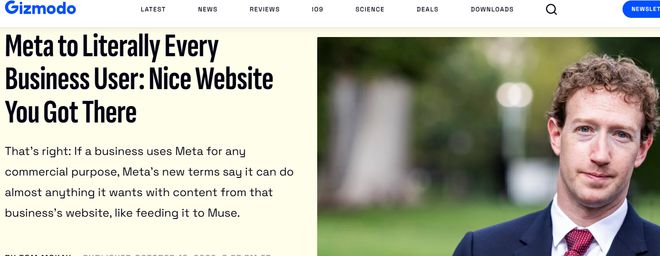
Meta has updated the terms of service for its Meta Business Suite, with the new rules scheduled to take effect on October 30. Under the revised agreement, companies that use Meta business accounts for advertising or store operations automatically grant the platform permission to scrape their public website content.
The collected data will be utilized by Meta to train its AI large language models. Notably, the new policy does not provide an opt-out mechanism. Even if a business uses robots.txt files to block web crawlers, the authorization granted through the business account agreement overrides these restrictions.
Previously, Meta was required to sign separate copyright licensing agreements to use content from publishers or corporate websites for AI training. The current change links content authorization directly to the use of business tools, effectively forcing companies to choose between using Meta marketing services or protecting their web content from AI training.