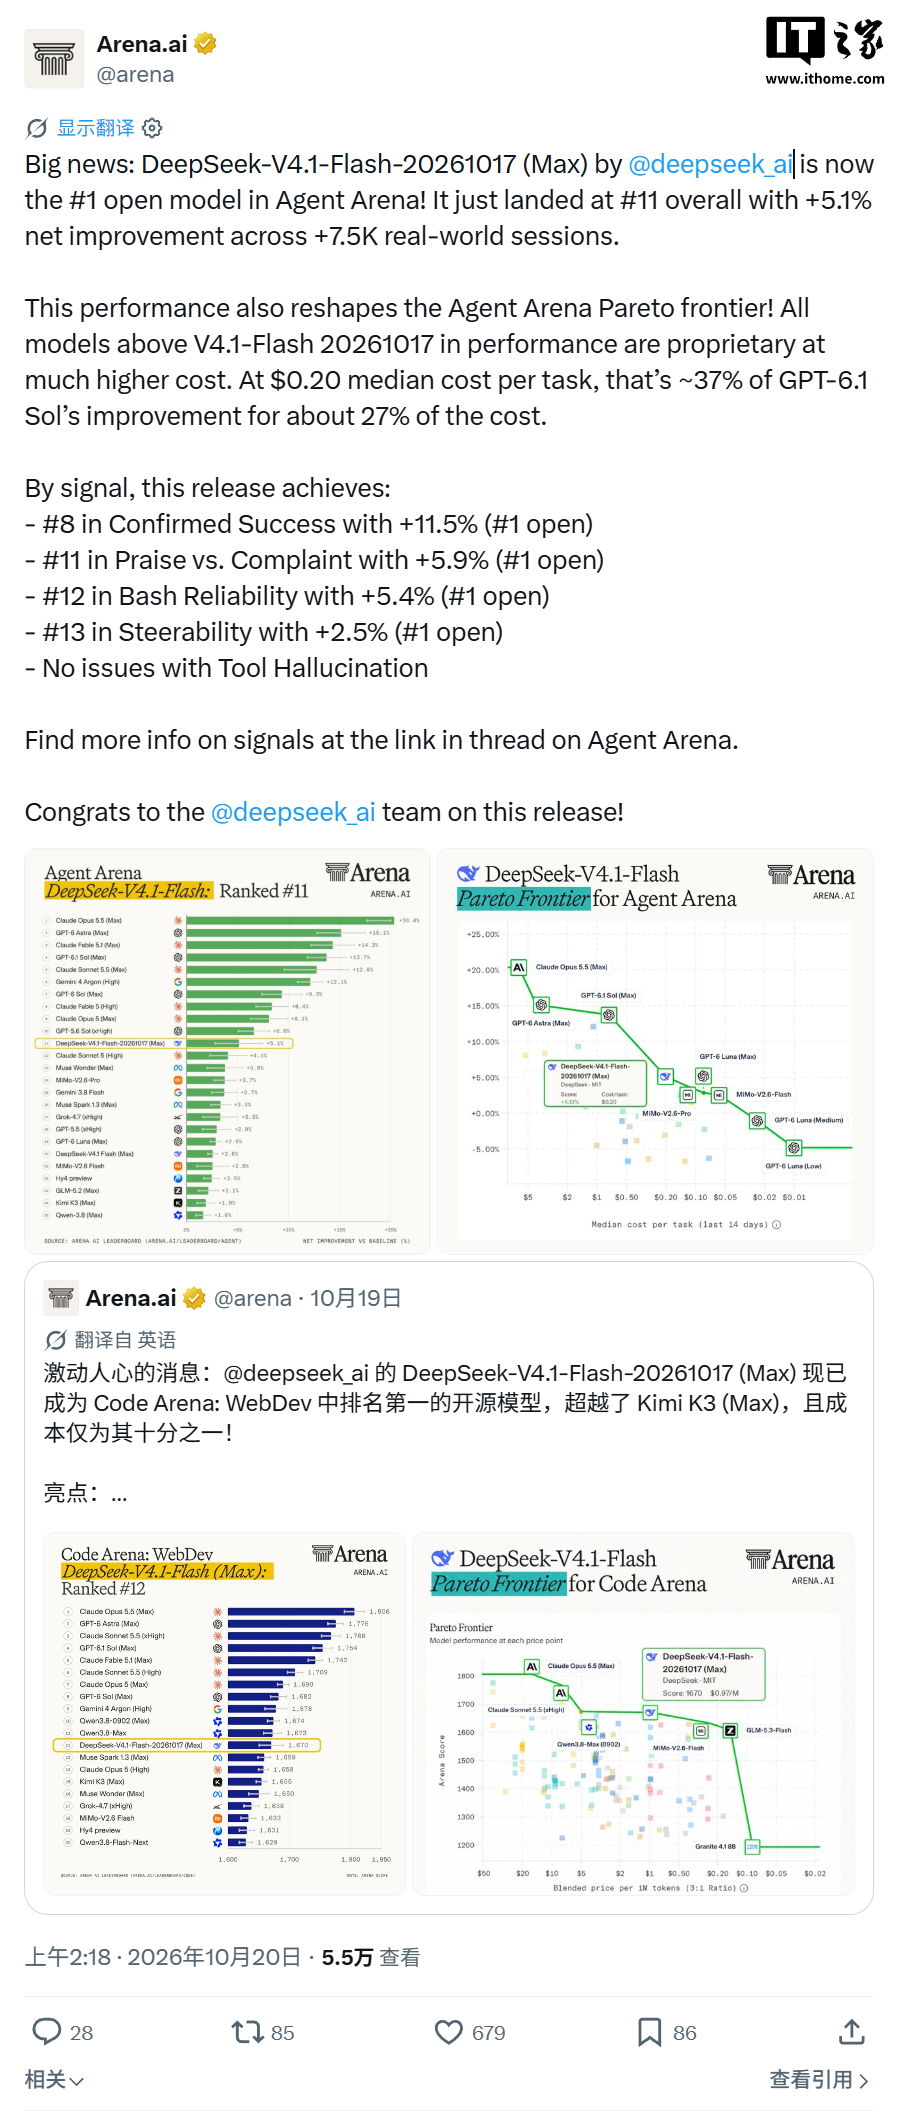
DeepSeek has released its high-performance inference framework, DeepInfer, under the Apache-2.0 license. The toolkit is specifically designed to support the lab’s own models, including the DeepSeek-V4.1-Flash version, in production environments.
The framework incorporates several optimization techniques, such as custom kernels, distributed parallelism, speculative decoding, and structured output support. It also features MoE expert parallelism to improve efficiency for mixture-of-experts models.
Performance metrics for DeepSeek-V4.1-Flash show an input cache hit rate of 96%. Generation speeds reach 230 tokens per second, with coding tasks achieving up to 300 tokens per second.
DeepInfer is optimized for NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, focusing primarily on offline inference with high throughput. Alongside the framework, the lab released a token encoding tool, deepseek-recipe, to ensure consistency with official API logic.