DeepSeek has officially open-sourced its internal inference framework, DeepInfer, to support developers and organizations in optimizing large-scale model deployment. This initiative aims to reduce computational costs and energy consumption associated with AI services by improving throughput and latency.
The framework includes high-performance operators and an optimized inference engine. It supports distributed inference, speculative decoding, SWA Bounded Replay, and structured output. DeepInfer is compatible with both Nvidia and Huawei Ascend platforms.
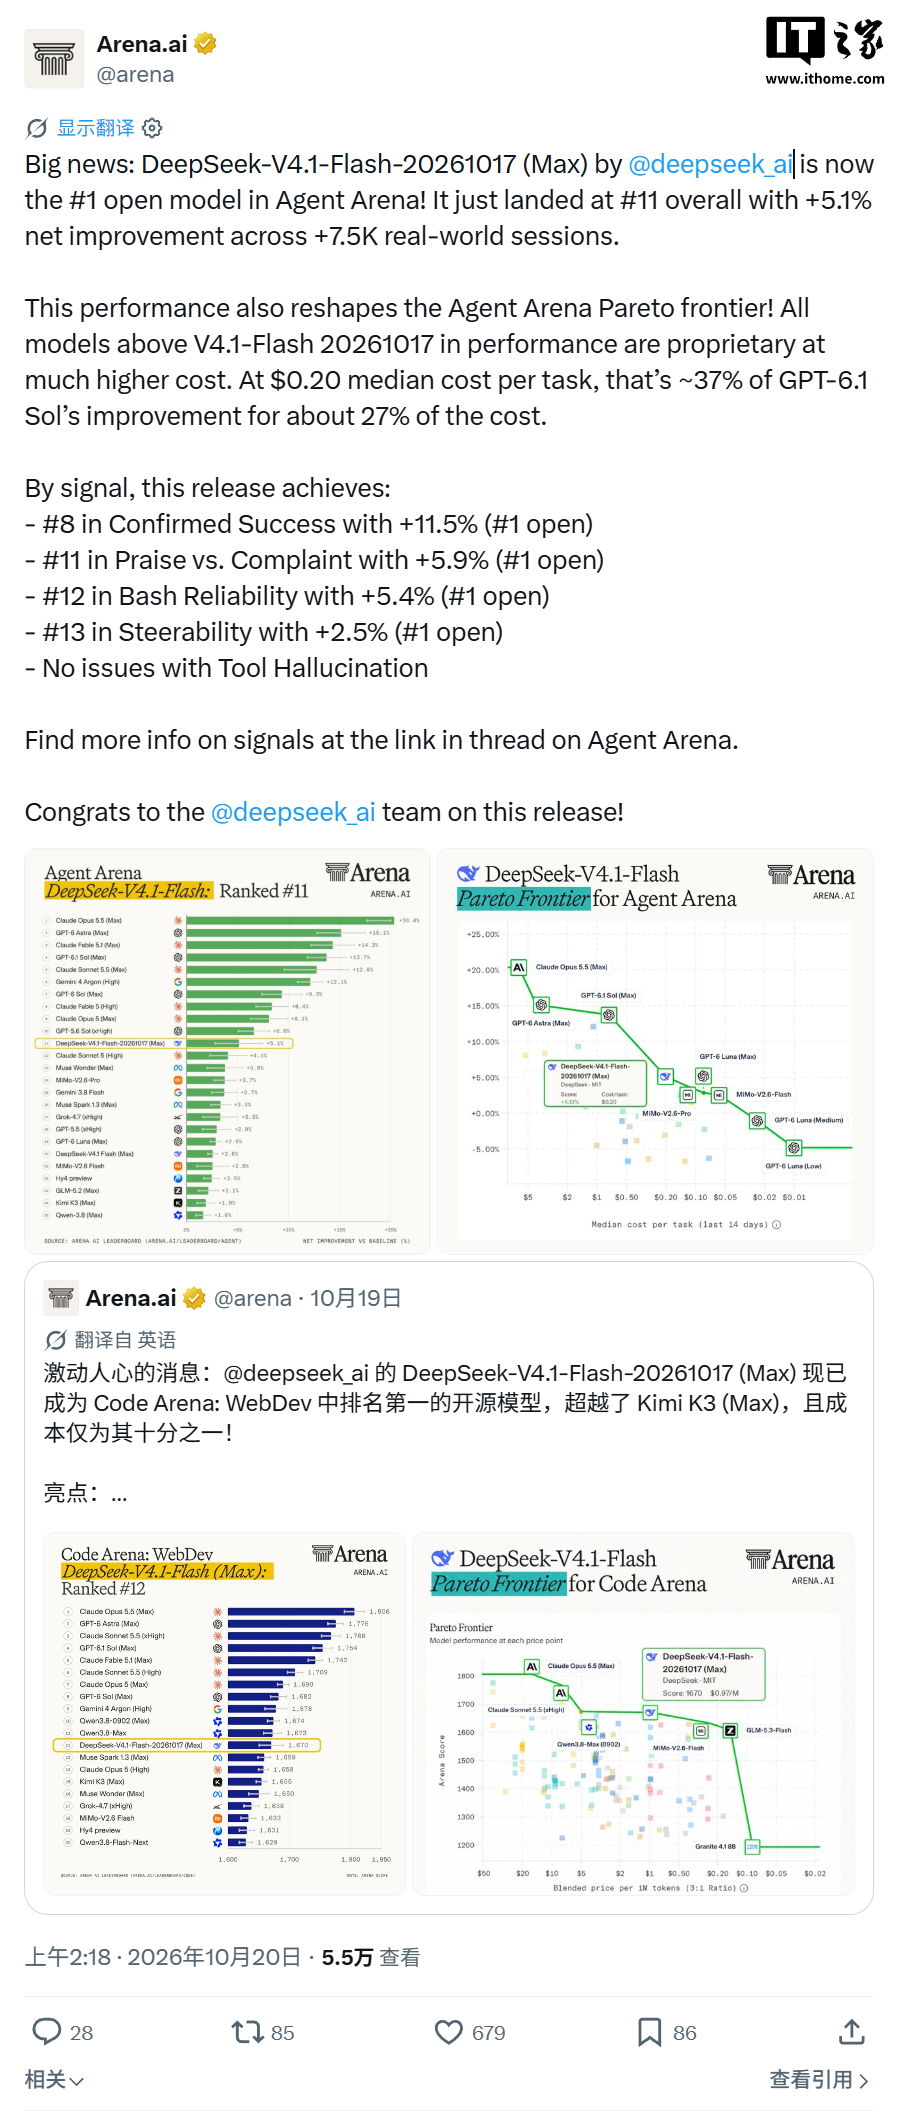
Alongside the framework, the company released the deepseek-recipe codec component. This production-grade tool aligns with DeepSeek official API processing logic, ensuring consistent performance for community deployments. The company already utilizes DeepInfer for its DeepSeek V4.1 Flash service.
Future updates for new model inference code and optimizations will be integrated into the open-source repository. DeepSeek intends to continue sharing its deployment expertise to facilitate broader access to large language models.