

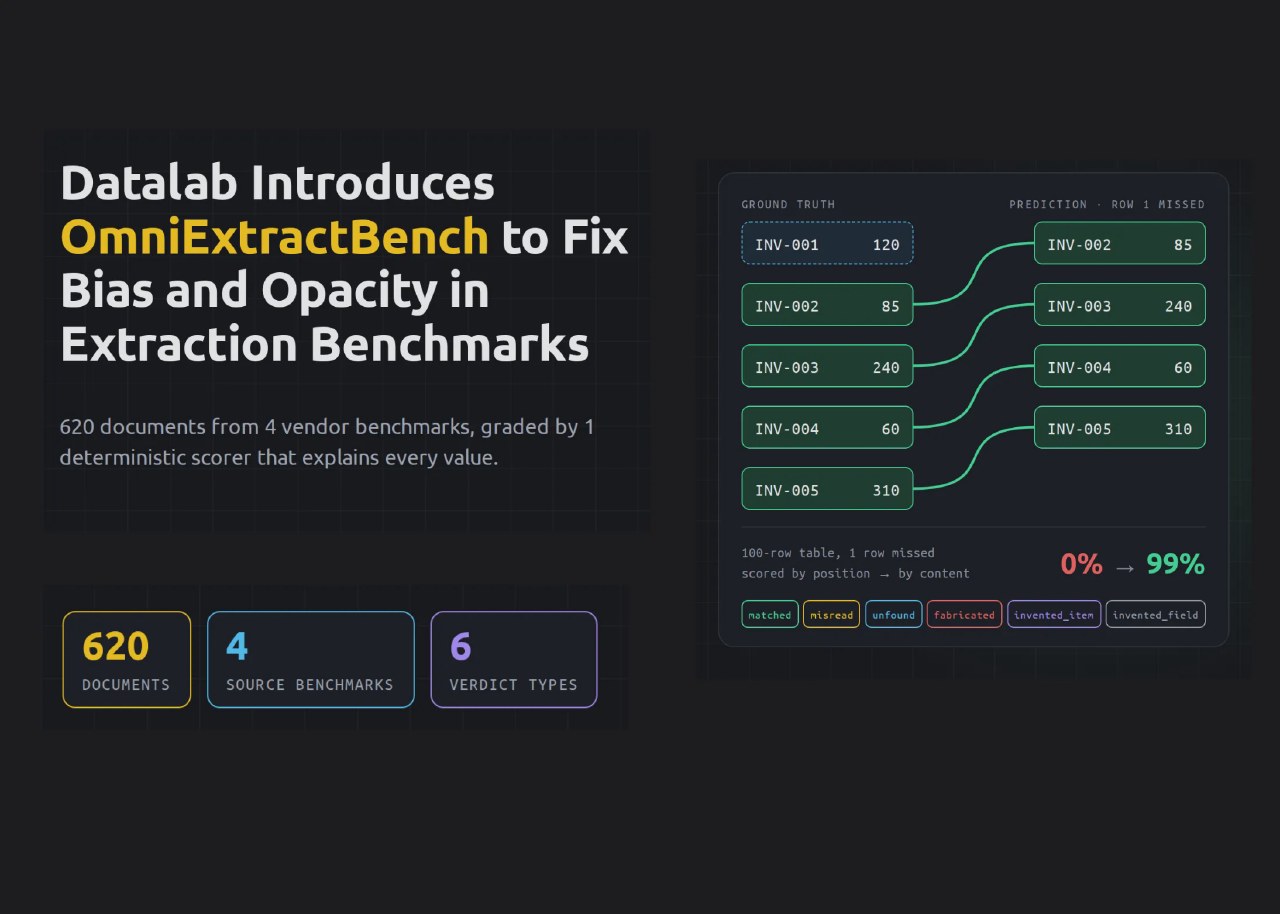
Datalab has released OmniExtractBench, a new benchmark designed to address issues of bias and lack of transparency in existing extraction leaderboards. The tool provides a standardized method for evaluating structured data extraction from documents, allowing for more consistent comparisons between different vendor systems.
The benchmark operates by comparing system-generated JSON outputs against gold standard files. It utilizes content-based pairing via the Hungarian algorithm to handle complex table structures, which often cause errors in positional comparison methods. The scorer normalizes values to ensure accurate matching across different formats.
The OmniExtractBench package is available via PyPI as version 0.1.7, requiring Python 3.11 or higher and SciPy. The project is licensed under Apache 2.0, with data hosted on Hugging Face under CC BY 4.0. Users can run evaluations using their own API keys and credits for various vendors.
In initial testing of 10 system configurations, Datalab’s accurate mode achieved 93.85% accuracy. Other models, including Datalab balanced and Reducto deep_extract v2, showed comparable results. The benchmark calculates precision and recall to provide detailed insights into how different systems perform.



