AI
Datalab Introduces OmniParseBench for OCR Parser Evaluation
Datalab has launched OmniParseBench, an open-source evaluation harness featuring 16,288 tests to audit the performance of OCR document parsers.
October 15, 2026, 02:37 AM·MarkTechPost
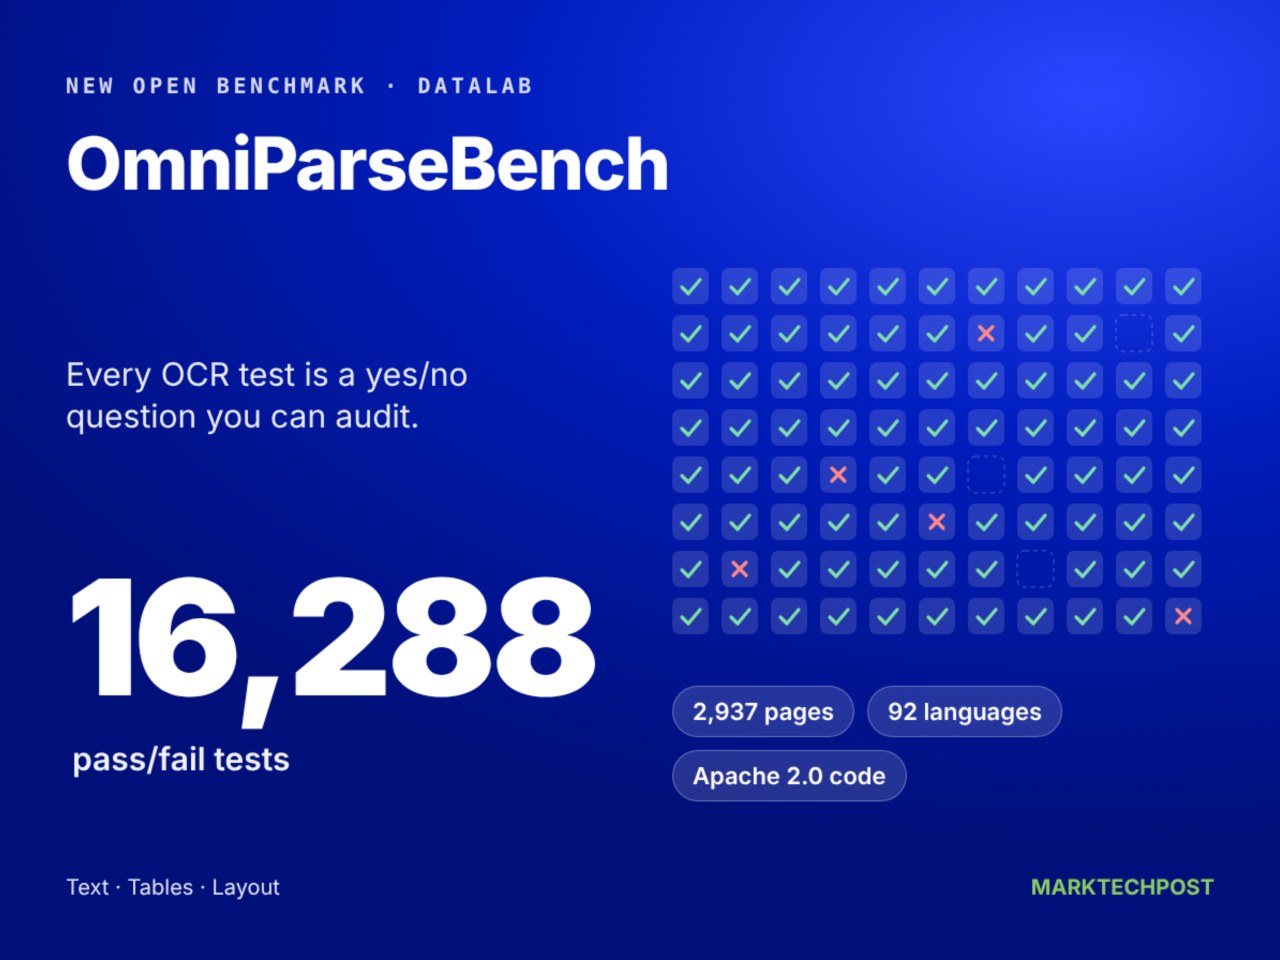
Datalab has launched OmniParseBench, an open-source evaluation harness featuring 16,288 tests to audit the performance of OCR document parsers.
Artificial Analysis has launched AA-3D, a benchmark that uses human preference to rank AI models on their ability to generate interactive 3D scenes via three.js code.
MWS AI has tested the ability of multimodal models to detect document fraud using a new experimental dataset of 430 images.
Version 1.1 of the LAB-AA legal AI benchmark now includes hallucination checks to verify that model outputs are grounded in source documentation.
AI benchmarking platform Arena has reached a $3.1 billion valuation after raising $200 million in a Series B round, nearly doubling its value in 10 months.
Epoch AI’s new benchmark reveals that top models from Anthropic and OpenAI score 65% on internal research tasks, struggling primarily with creative judgment and style.
AI evaluation startup Arena has raised $200 million in a Series B round, reaching a valuation of $2.88 billion, and launched a new benchmark for AI agent behavior.
A new benchmark has been created to evaluate the performance, speed, and cost-efficiency of specialized decision-making AI models in production.
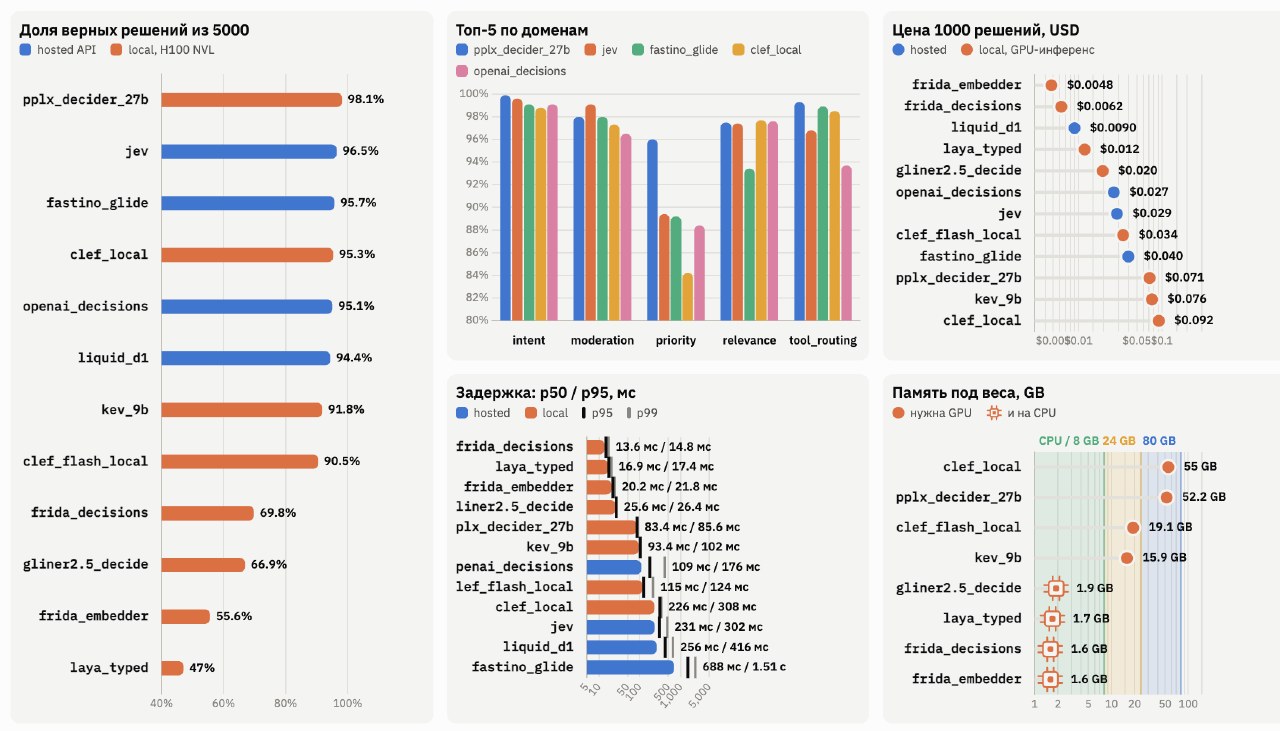
Researchers analyze various datasets for testing AI data masking gateways, highlighting the need to combine external benchmarks with specialized tools for verifying agent performance.
A new Stanford study reveals that single AI coordinators significantly outperform multi-agent teams when managing shared resources, often due to coordination failures.
MWS AI has released the open-source RESON library for ASR model evaluation alongside a new benchmark featuring 38 hours of diverse Russian-language audio data.
The Center for AI Safety has released CheatBench, a new tool that tracks how often AI agents exploit shortcuts to inflate their performance scores.
SpaceXAI's Grok 4.7 model has tied for the top spot on the new Artificial Analysis Cyber Index with a score of 56, though it carries a premium cost of $11.67 per task.
Researchers created a custom benchmark to evaluate LLMs for database querying, finding that performance varies significantly across models and costs range from $0.12 to $4.94.
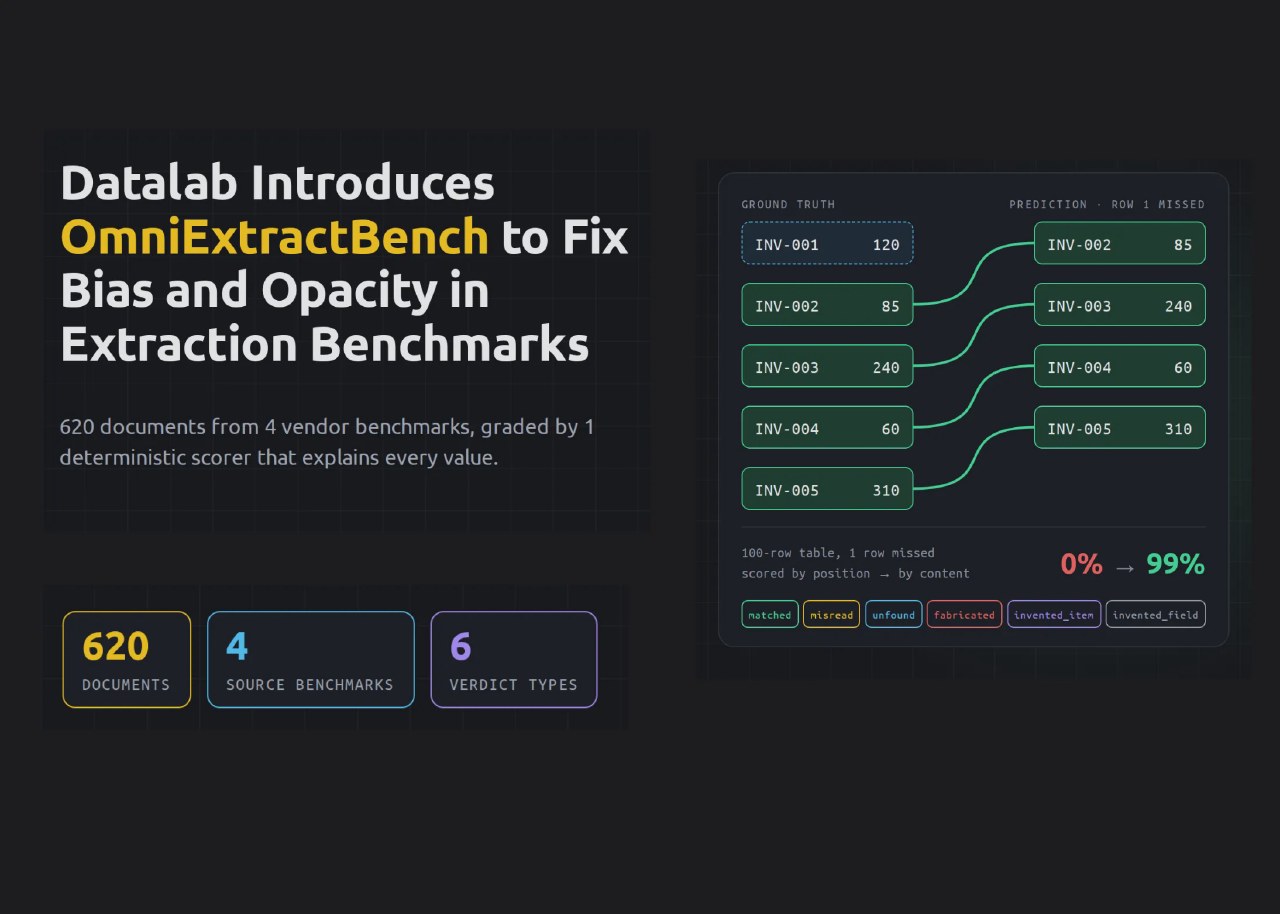
Datalab has launched OmniExtractBench, an open-source benchmark designed to standardize the evaluation of structured data extraction systems and improve transparency in vendor comparisons.
A new Nvidia study reveals that AI models experience a 62.8% average drop in accuracy when processing long-horizon tasks, highlighting critical reliability limits in current LLMs.
WebPageBench provides a standardized environment to evaluate AI agents on Russian-language simulated websites using event-based logging.
Anthropic has launched the Claude Sonnet 5.5 model, which offers performance near Opus 5.5 levels but shows varying token efficiency depending on the workload and testing environment.
Artificial Analysis has launched the Cyber Index (v1) to evaluate how effectively AI models can identify and patch enterprise security vulnerabilities.
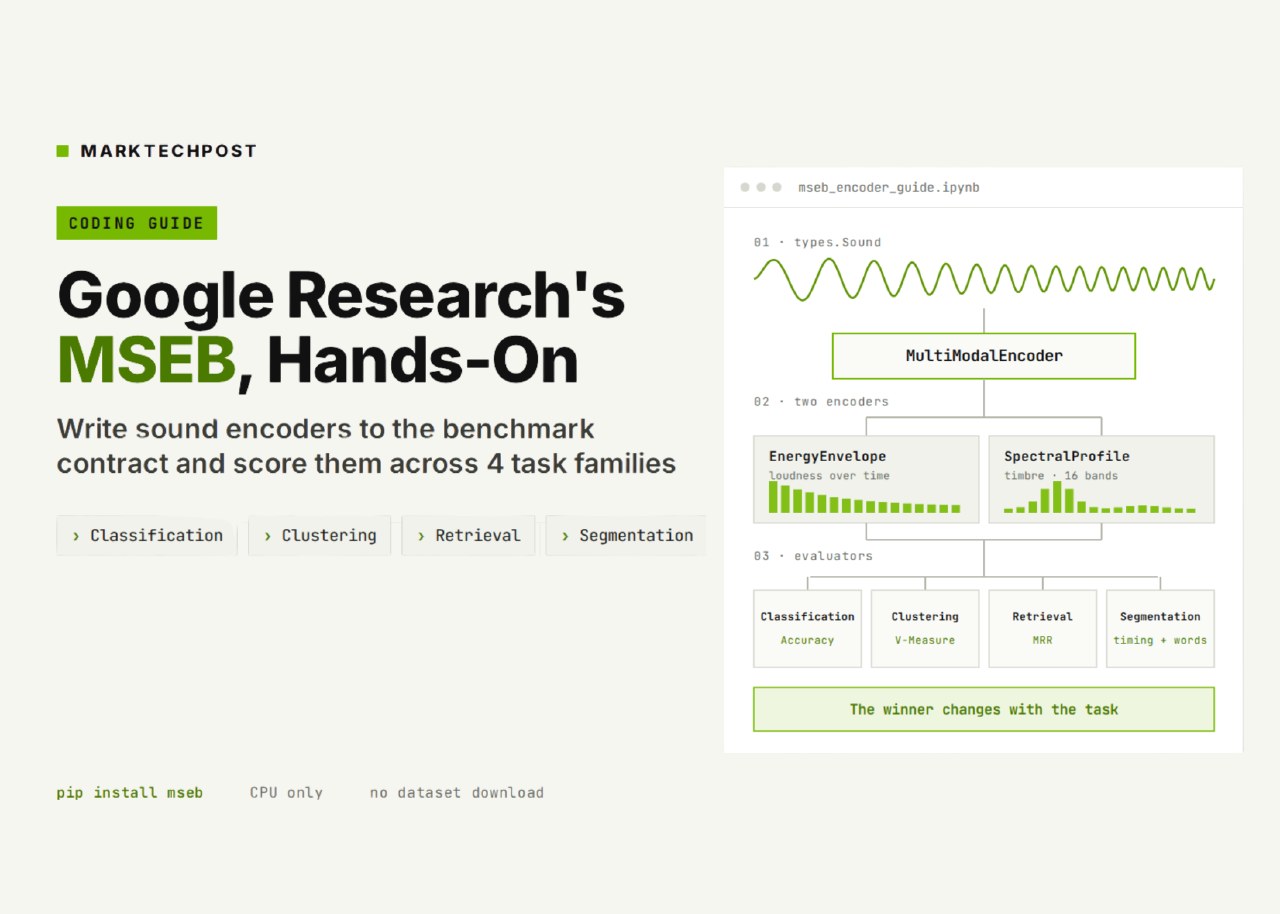
Google Research has introduced the MSEB benchmark, a structured framework for evaluating audio models through standardized data types, encoder interfaces, and task-specific evaluators.