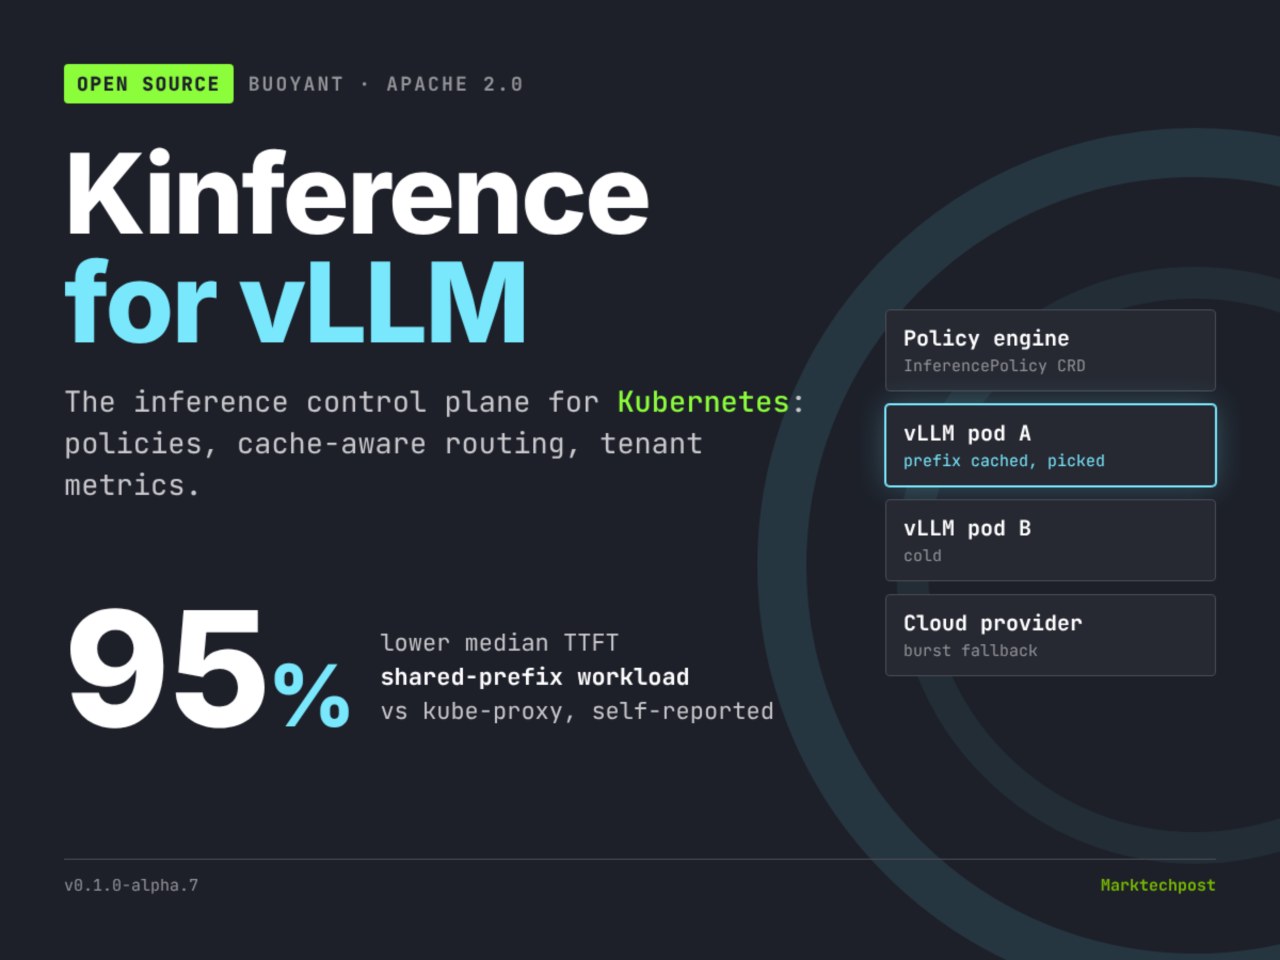
Buoyant has introduced Kinference, an open-source control plane designed to transform Kubernetes and vLLM environments into multi-tenant inference platforms. The system functions by separating the data plane, handled by vLLM, from the control plane, managed by Kinference. It consists of a traffic gateway and an inference handler that utilizes a gRPC interface to process requests.
The tool monitors vLLM KV-cache events and engine metrics, utilizing NVIDIA’s dynamo-kv-router crate. Configuration is managed through five custom resource definitions, including InferencePolicy and InferencePool. Policies are declarative, allowing routing decisions based on tenant, model, GPU state, or semantic tags, with validation possible via the kinfctl CLI.
Benchmarks comparing Kinference against standard Kubernetes ClusterIP load balancing showed significant performance gains. Using three vLLM 0.31.0 pods on L40S GPUs with the Qwen3.8-27B-FP8 model, median end-to-end latency dropped by 45% for shared-prefix tasks. Peak goodput reached 103 requests per minute, compared to 14 for the baseline.
Kinference provides governance features such as tenant accounting, provider fallback, and policy management. The installation process involves deploying Gateway API v1.5.1 CRDs alongside Helm charts for the Buoyant gateway and Kinference. The system includes integrated Prometheus metrics and Grafana dashboards for tracking latency and token usage.