

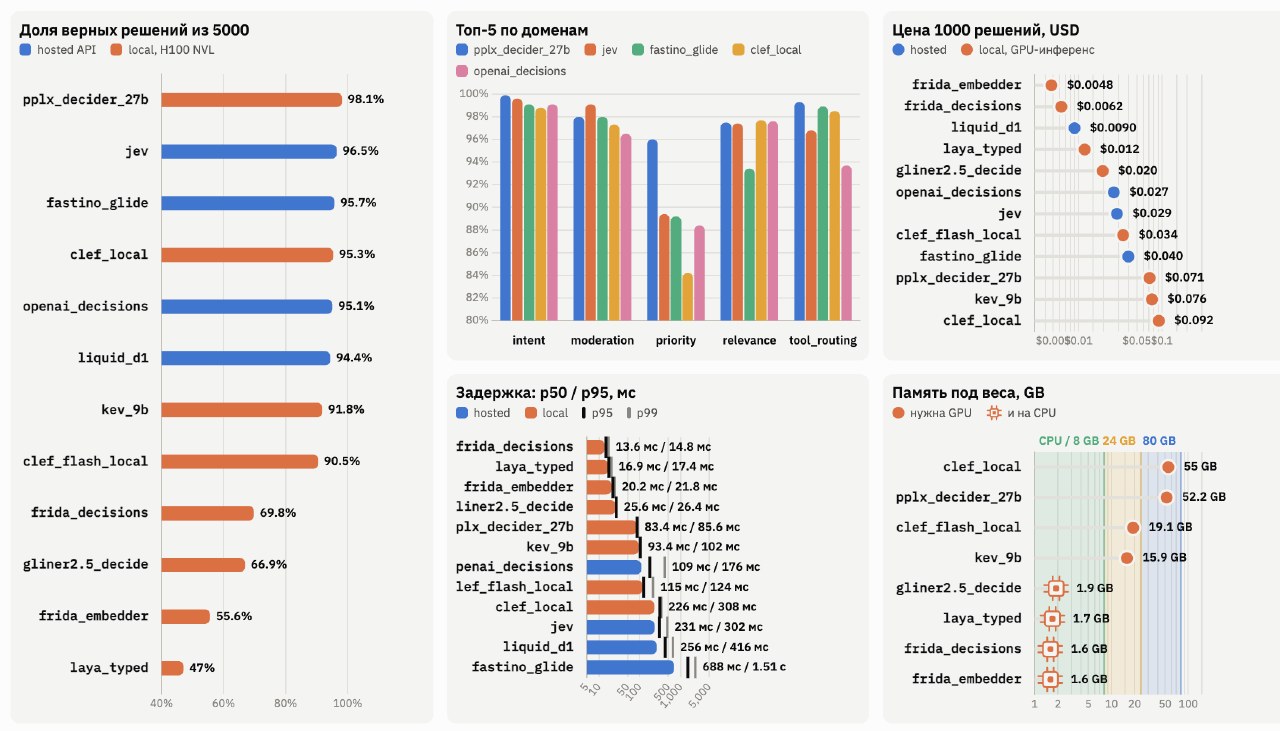
The rise of specialized decision-making models, known as Decision Models, has gained momentum since September 2026. This class of AI emerged as an alternative to using general-purpose large language models for simple tasks like routing, moderation, and evaluation, which often leads to inefficient resource consumption.
The new benchmark aims to evaluate the performance of these models in production environments. It focuses on three key metrics: quality, inference speed, and total cost. The assessment covers both cloud-based solutions and self-hosted deployments to provide a comprehensive comparison for developers.
The testing suite includes a diverse range of models, such as Perplexity Decider 27B, TypeSafe Jev, Fastino GLiDE, and GLiNER2.5-Decide. The list also features Cloudflare Clef 27B, OpenAI GPT-6 Luna Decisions, Liquid d1, Kev-9B, Cloudflare Clef-flash 9B, FRIDA-Decisions, and Laya Typed Decisions.



