

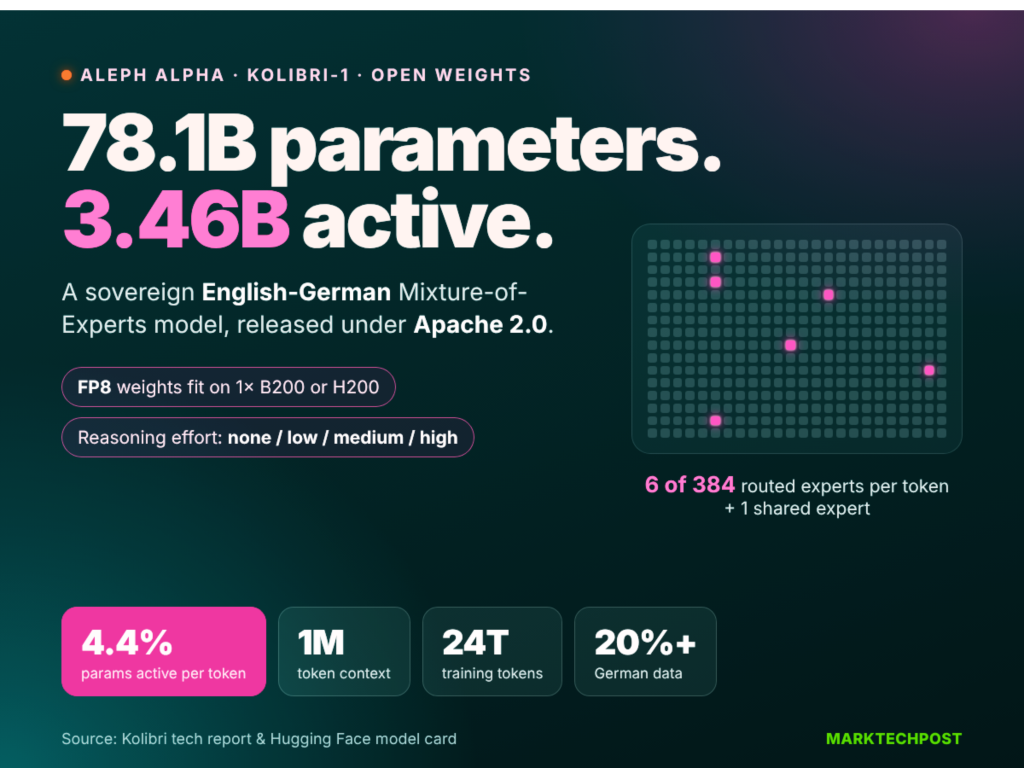
Aleph Alpha has released Kolibri-1, a bilingual English-German MoE model featuring 78.1 billion parameters with 3.46 billion active parameters. The model utilizes 50 transformer blocks and a 128,000-token vocabulary trained via UniBPE, which improves token efficiency for German text by 11.2% compared to the GPT-5 tokenizer.
The architecture employs grouped-query attention and a hybrid attention mechanism. While 40 blocks use sliding-window attention over 512 tokens, every fifth block utilizes full attention without positional encoding. This design allows the model to support sequences four times longer than standard full-attention models at equivalent compute levels.
Training involved 20 trillion tokens on 768 NVIDIA B200 GPUs, followed by a mid-training stage of 3.44 trillion tokens and a long-context phase of 201 billion tokens. The post-training process included supervised fine-tuning and reinforcement learning on over 1.2 million internal tasks using the Merlin-Arthur protocol.
The FP8 checkpoint requires approximately 78 GB of memory and is compatible with NVIDIA B200, B300, H200, or dual H100 SXM5 GPU configurations. It is served via vLLM with dedicated parsers. The default context window is 262,144 tokens, with support for up to 1 million tokens via configuration overrides.



