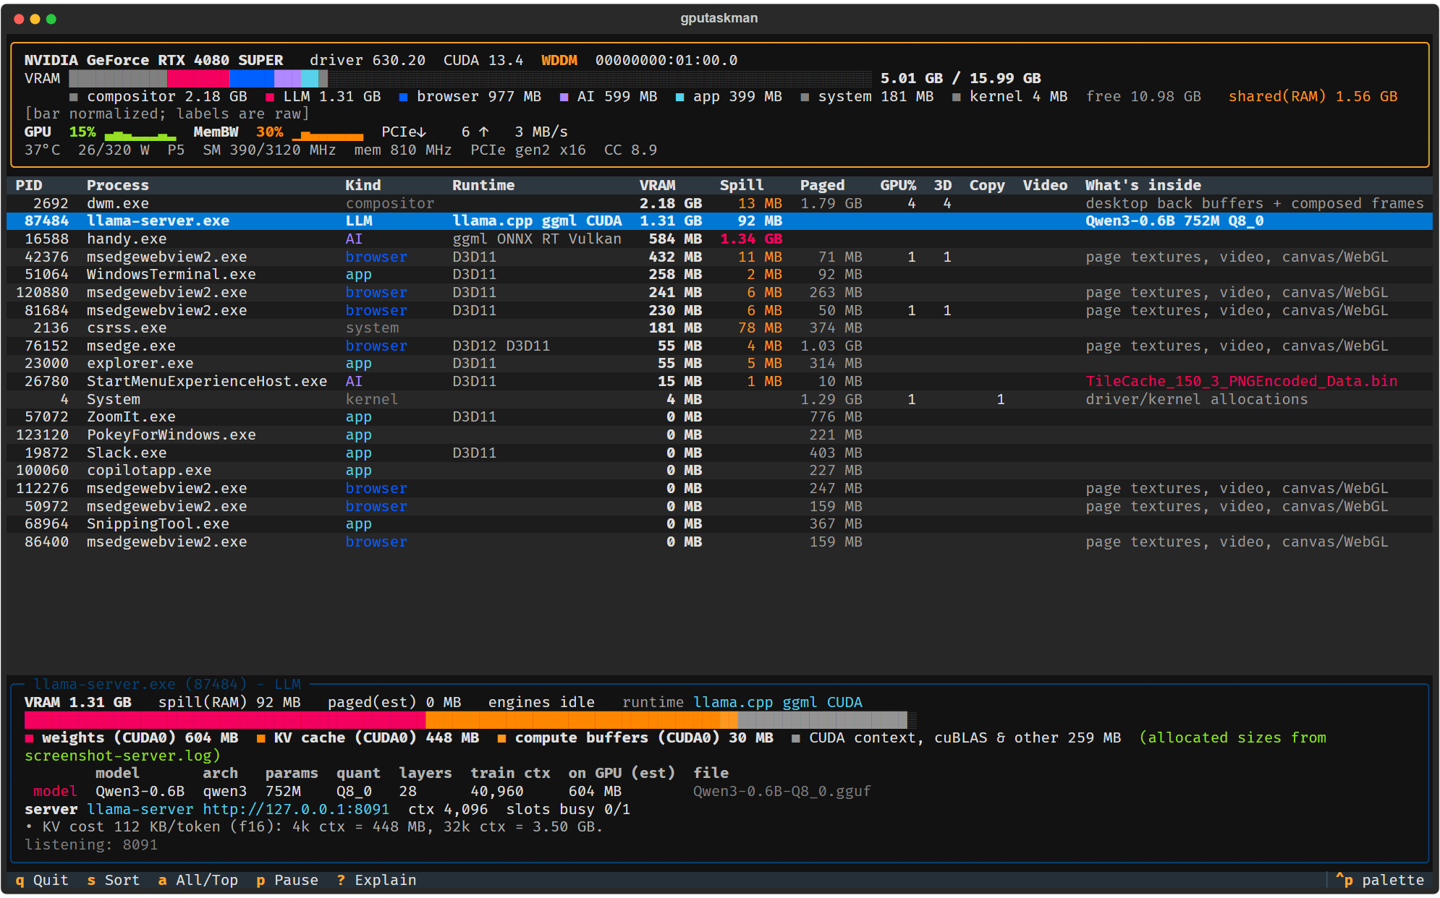
The Zero-Host-Copy inference pipeline is designed to eliminate CPU involvement in the hot execution loop, achieving speeds of approximately 165 FPS on an RTX 3060 Ti and 38 FPS on a Jetson Orin Nano. The architecture ensures that video frames remain in GPU memory from initial disk reading to final storage, minimizing PCIe bus data transfers.
To maintain stable performance, the system avoids dynamic memory allocation during runtime. It utilizes a three-phase lifecycle: initialization, warm-up, and hot execution. By pre-allocating memory pools and using reuse queues, the pipeline prevents the implicit synchronization caused by cudaMalloc, which would otherwise disrupt asynchronous processing.
The InferencePipeline class manages data flow through three asynchronous stages: Source, Detector, and Sink. A custom SafeQueue with a backpressure mechanism prevents memory overflow by pausing the Source thread if the Detector falls behind, ensuring system stability without busy-waiting.
The implementation accounts for hardware differences between discrete GPUs and Jetson's Unified Memory Architecture (UMA). It uses a specialized allocator to define memory types—Device, Pinned, or ZeroCopy—optimizing data locality based on the platform. For x64 systems, it leverages FFmpeg with AV_HWDEVICE_TYPE_CUDA to keep frames in VRAM throughout decoding and processing.