

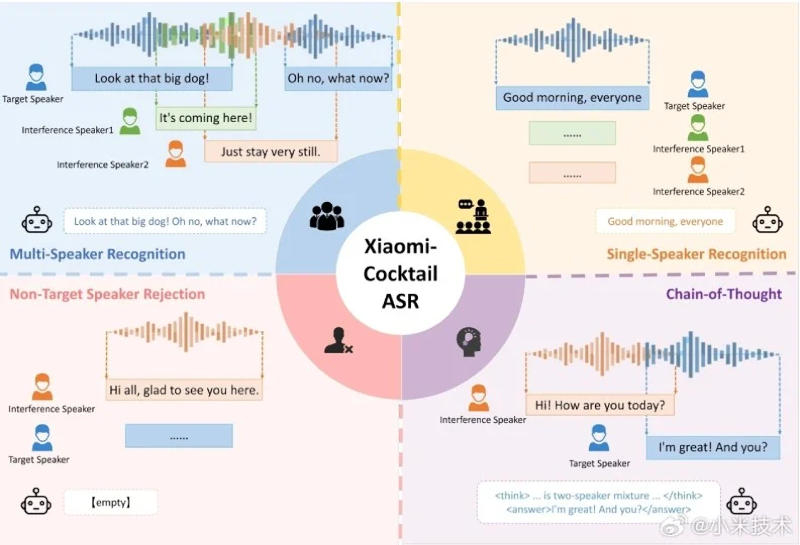
Xiaomi has released an open-source AI model named CocktailASR-1, designed to isolate and transcribe a specific person's voice in environments where multiple people are speaking simultaneously. This capability addresses the challenge known as the cocktail party effect, where overlapping speech often leads to transcription errors.
To function, the model requires a short audio sample of the target speaker, which serves as a reference point. By analyzing multi-speaker recordings against this sample, CocktailASR-1 filters out background voices to transcribe only the intended individual. The model also performs effectively in single-speaker scenarios.
The system includes a safeguard that prevents it from hallucinating text; if the target voice is absent from a recording, the model returns an empty output rather than transcribing other speakers. Additionally, it features a chain-of-thought mode that allows users to review the logic behind the transcription process.
According to Xiaomi, the model has outperformed existing alternatives in tests involving multi-speaker audio samples. The CocktailASR-1 model is currently available for public access via the GitHub and Hugging Face platforms.



