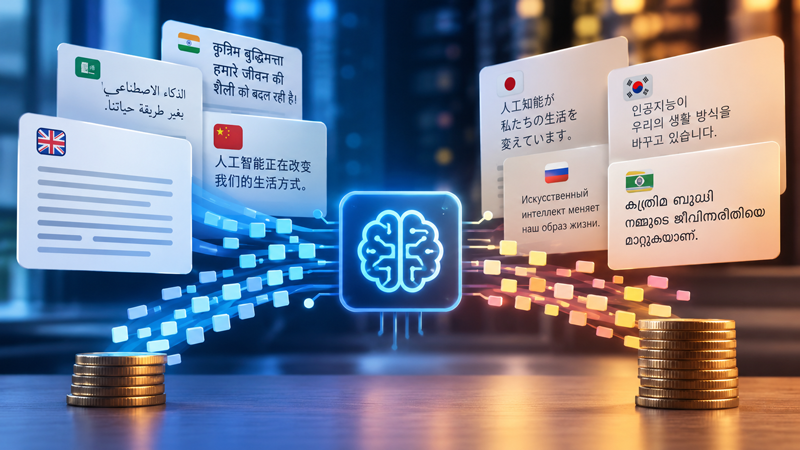
Researchers from the Coalition for Language Equality in AI Research (CLEAR) have identified a phenomenon termed the tokenizer tax. This issue arises because AI models break down text into tokens before processing, and the number of tokens required varies significantly depending on the language used.
Because commercial AI services typically charge based on token count, users working in languages other than English often face higher costs. Analysis using the FLORES-200 dataset revealed that for the 20 most common languages, the difference in token requirements ranges from 1.5 to 5 times.
When expanding the analysis to 200 languages, the disparity in tokenization for certain models reaches up to 17 times. For example, a phrase in Malayalam may require significantly more tokens than the same content in English, directly impacting the cost of processing.
Beyond financial costs, the tokenizer tax limits the available context window for non-English languages. Since AI models have fixed token limits, languages that require more tokens leave less space for documents, conversation history, and other essential data.
Increased token counts can also lead to higher computational loads and longer response latency. Languages with scripts poorly represented in training data, such as Burmese, Tibetan, Khmer, and Lao, are particularly affected by these inefficiencies.
To address these disparities, experts suggest improving multilingual training datasets and developing specialized tokenizers for diverse writing systems. They emphasize that developers must actively work to reduce this form of digital inequality in AI.