

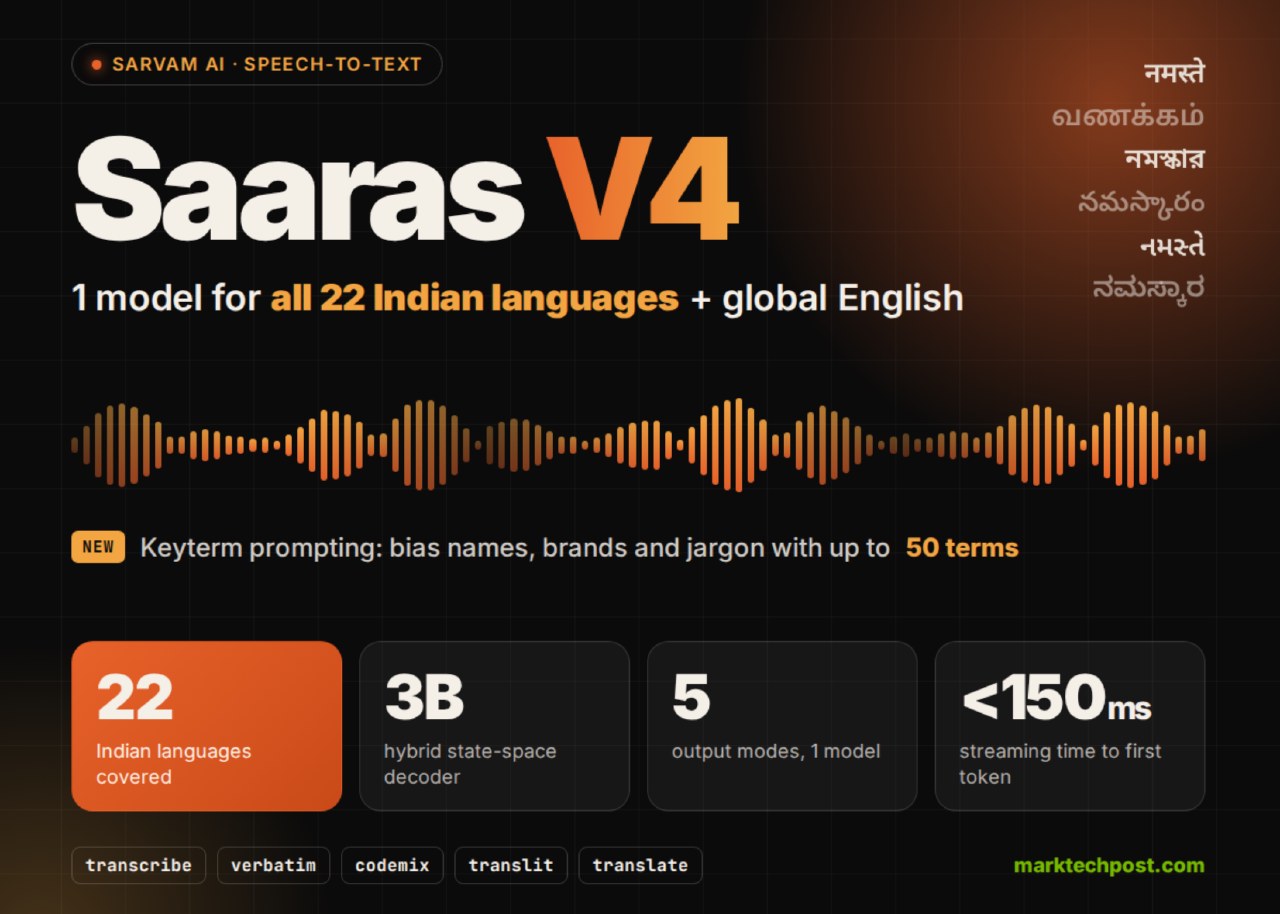
Sarvam AI has launched Saaras V4, a speech-to-text model supporting all 22 official Indian languages and global English. The system is currently available for deployment via the company's API using the model identifier saaras:v4. The model weights remain private, and self-hosting documentation for this version is not yet available.
The architecture utilizes an encoder-decoder framework. An audio encoder processes waveforms into embeddings, while a temporal-downsampling adapter projects these into the language model's space. The decoder, Sarvam-3B, is a hybrid state-space model with 3 billion parameters developed in-house. It processes audio features alongside text prompts to generate transcripts.
A new feature in V4 is keyterm prompting, which allows users to bias recognition by providing a JSON list of up to 50 terms, each limited to 64 characters. The model also includes a codemix mode for maintaining specific scripts, such as Latin, for brand names. Users can select from 5 different output representations using the mode parameter.
On the IndicContextEval benchmark, Saaras V4 achieved a word error rate (WER) of 16.03% in the L5 keyword-prompting configuration. Sarvam AI claims this is the lowest score recorded on the benchmark to date. The company notes that these figures are vendor-reported and have not yet undergone independent verification.
Saaras V4 maintains the same request structure as the previous version, Saaras v3, which remains the default model. Developers can switch to the new version by updating a single line of code. Sarvam AI emphasizes that integrating these functions directly into the model eliminates the need for error-prone post-processing steps.



