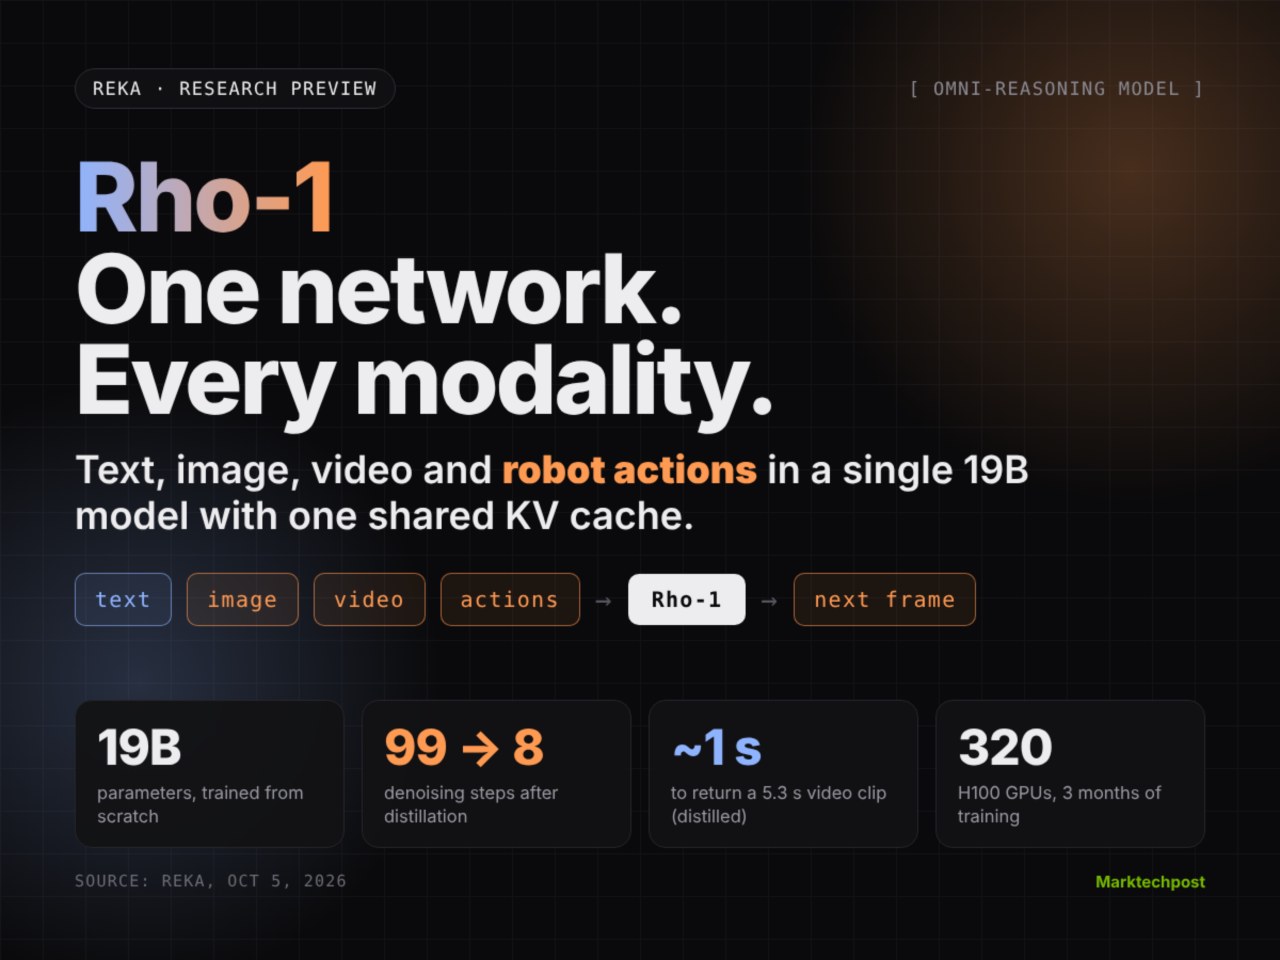
Reka has introduced Rho-1, a 19B parameter omni-reasoning model designed to process text, vision, and robotic actions within a single context window. Unlike traditional pipelines that rely on multiple specialized models, Rho-1 integrates these capabilities into one architecture, eliminating the latency associated with model handoffs.
The model architecture features transformer blocks with two expert weight streams: one for understanding language and visual data, and another for generating images and video. Both streams share attention mechanisms and a common KV cache, allowing the model to render outputs directly from the accumulated state.
Performance metrics provided by Reka indicate that the base model generates video at 0.79x real-time, with a first clip appearing in approximately 7 seconds. A distilled version of the model reduces denoising steps from 99 to 8, enabling the generation of a 5.3-second clip in about 1 second.
For robotics applications, Rho-1 decodes control actions and future frames from the same latent state. The model demonstrated its capabilities in a LIBERO simulation by emitting 7 action channels. To address data scarcity, Reka utilizes an Inverse Dynamics Model to infer control signals from raw video.