

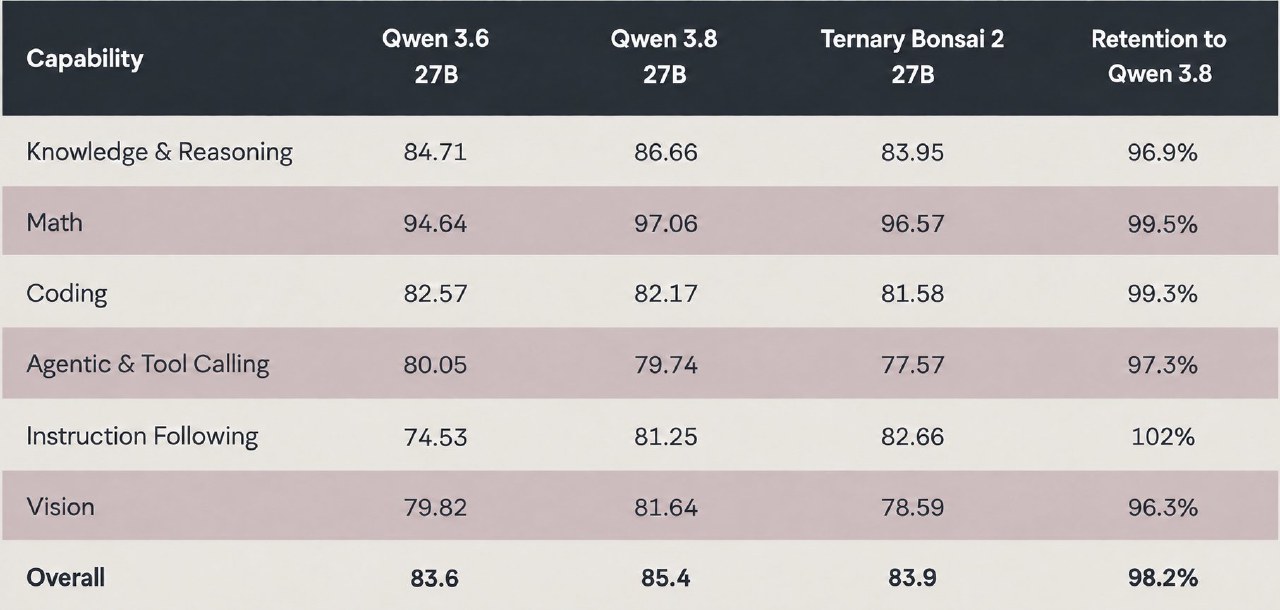
PrismML has introduced the Bonsai 2 27B model, a ternary quantized version based on Qwen3.8 27B. The model achieves 98.2% of the base model's performance while utilizing less than one-ninth of the memory. It is designed for local execution of tasks such as coding agent loops, document parsing, and multi-modal debugging, reducing reliance on cloud APIs.
The model features a total size of 5.9GB, with an effective bit rate of 1.76 bits per weight using FP16 group scaling. It supports a context window of 262K tokens. PrismML released the model weights under the Apache 2.0 license, allowing for broad accessibility and integration into various development workflows.
Performance metrics show a token throughput of 143TPS on NVIDIA GeForce RTX 5090 hardware and 46.8TPS on Apple Silicon M5 Max chips. On an NVIDIA GeForce RTX 4090, the model demonstrates an energy efficiency of 0.714mWh per token, which is 40% lower than that of a full-precision 8B model. The software supports both CUDA and MLX frameworks.



