

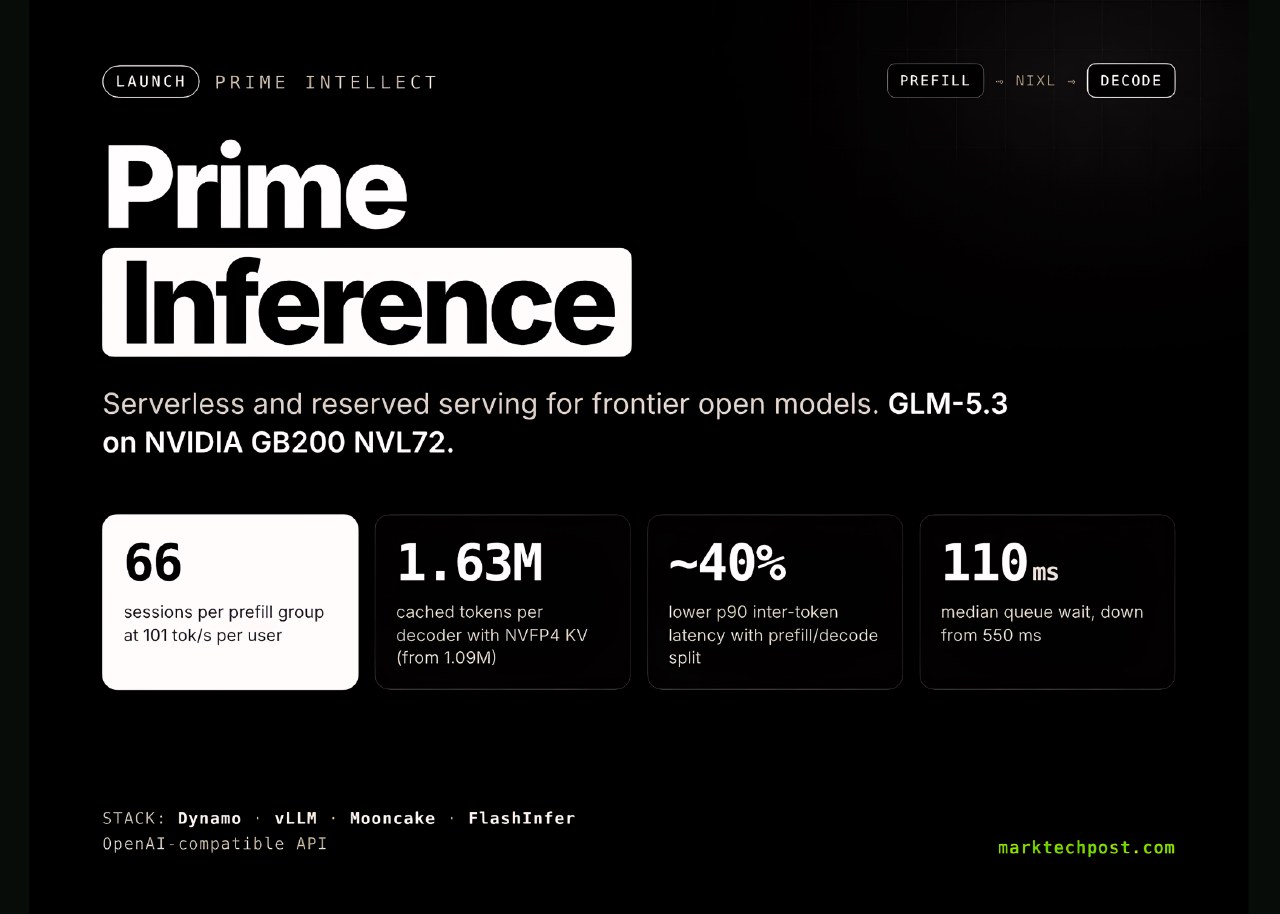
Prime Intellect has introduced Prime Inference, a new serving layer integrated into its open training stack. The platform supports both serverless and reserved serving models, designed to facilitate production traces that can be fed back into the training process. Prime reports that its GLM-5.3 endpoint currently maintains 100% uptime and a near-zero error rate for tool calls.
The infrastructure utilizes a combination of NVIDIA Dynamo, vLLM, Mooncake, and FlashInfer. Prime Inference employs prefill and decode disaggregation, where these processes run on separate GPU groups. According to internal benchmarks, this architecture achieves a 40% reduction in p90 inter-token latency. The system also features cache-aware routing to optimize session performance.
The platform is specifically optimized for agentic workloads, targeting a performance of 100 end-to-end tokens per second per user. In testing, the system supported 66 sessions per prefill group while maintaining 101 tokens per second per user and 100 output tokens per second per GPU. The stack includes a structural-tag builder and xgrammar integration to prevent tool-call errors.
Prime Intellect developed this stack in collaboration with Inferact and NVIDIA, contributing fixes back to the upstream projects. The company notes that its performance metrics were verified against third-party data from ComputePrices as of October 2, 2026. The solution aims to close the loop between model deployment and continuous training.



