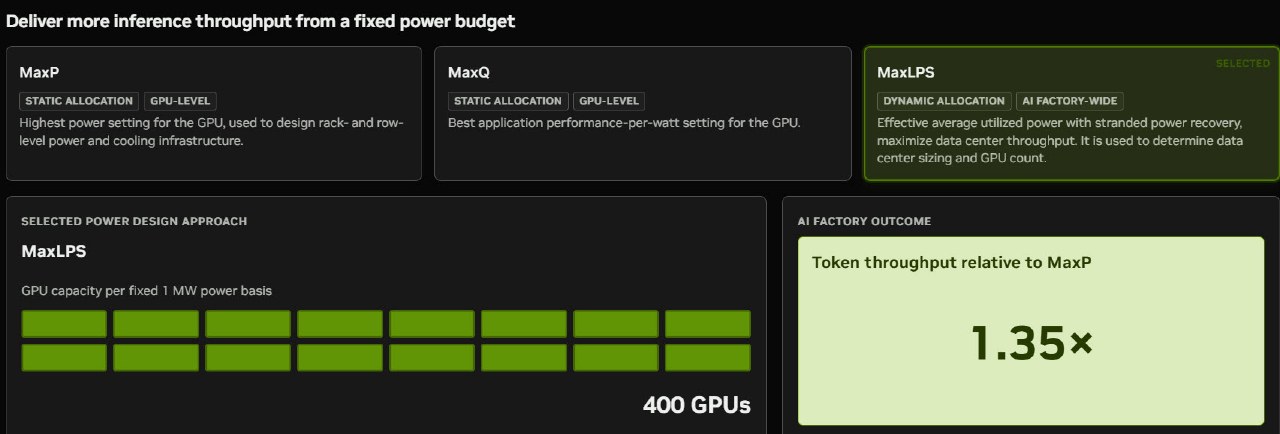
Nvidia introduced the DSX MaxLPS power scheduling system at the AI Infrastructure Summit. The technology is designed to optimize AI factory efficiency, increasing token throughput per megawatt by up to 40%. The system has already been integrated by Emerald AI into its Conductor platform to manage data center workloads based on grid conditions.
The Conductor AI platform features the DSX Flex component, which automatically adjusts power demand without user intervention. Lambda, a cloud service provider with over 10,000 customers, tested the system on a cluster of 5 racks and 19 nodes. Under a fixed power budget, the company achieved a 24% increase in token throughput and a 23% improvement in performance per watt.
Nvidia also revealed that Vera Rubin and Groq 3 LPX racks allow for a 40% increase in GPU density within existing power limits. This enables a 35% boost in token throughput without requiring new power infrastructure. In specific tests using Qwen 3.8 27B workloads with 100K context, the Groq 3 LPX system reached 2,529 output tokens per user per second.
Early testing of the Vera CPU by various AI companies demonstrated significant performance gains. Perplexity reported a 1.9x faster startup for its SPACE sandbox, while DeepInfra saw a 2.2x reduction in orchestration latency. Redpanda noted a 5.5x lower latency and 73% higher throughput, while Starburst and Kinetica reported 3x and 2.7x improvements in query performance, respectively.