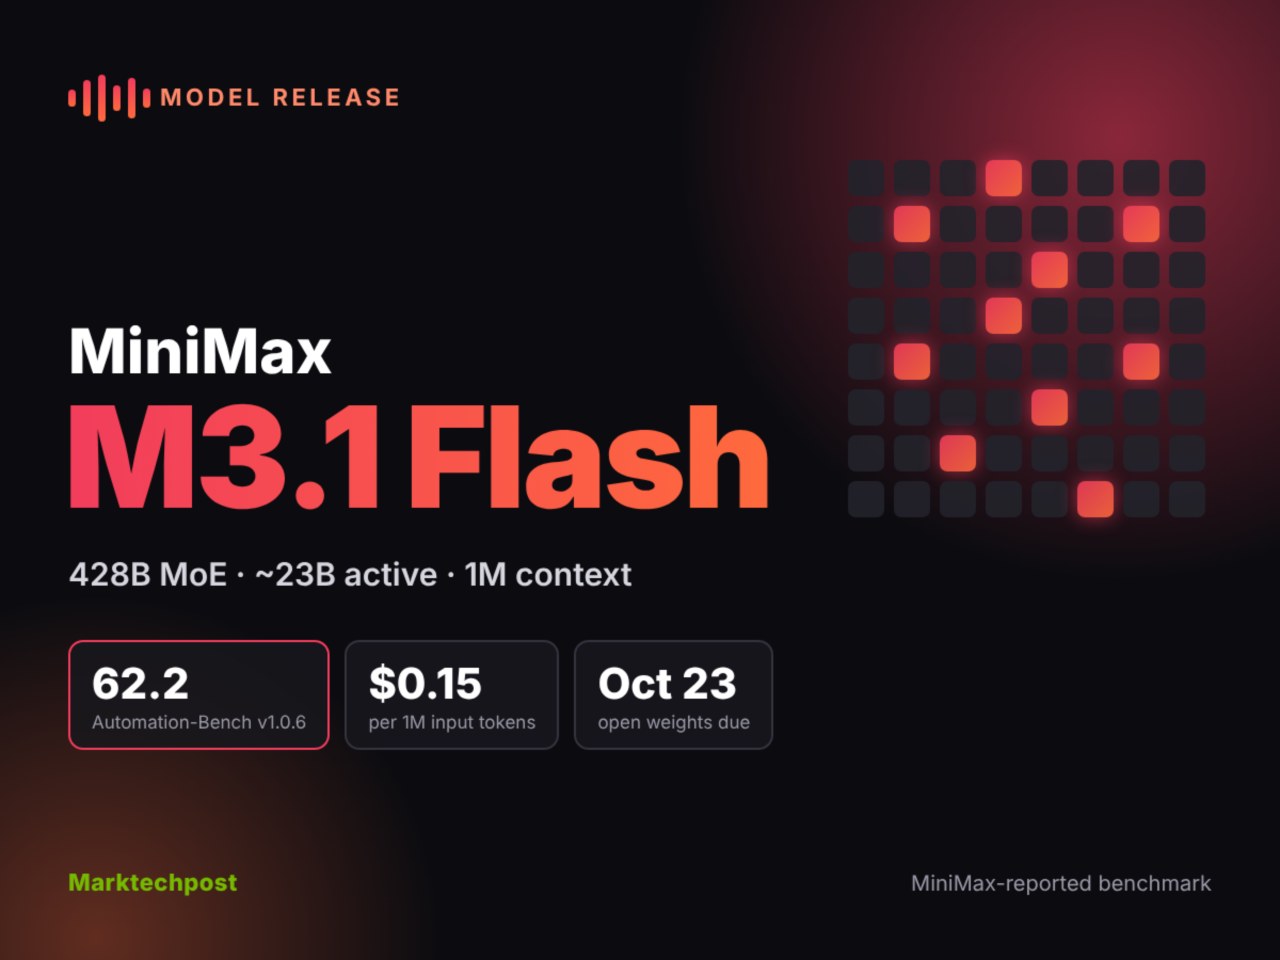
MiniMax has released M3.1 Flash, a multimodal mixture-of-experts model featuring 428 billion total parameters and approximately 23 billion active parameters. The model supports a context window of 1,000,000 tokens and is designed for coding, visual reasoning, and agentic office tasks.
The model utilizes an always-on reasoning architecture with five configurable effort levels. Developers must update integrations to handle the new reasoning_content field, as previous inline tag parsing is no longer supported. The platform provides access via OpenAI and Anthropic-compatible APIs.
Pricing for the model is set at $0.15 per million tokens for input and $0.60 per million tokens for output, with cache reads priced at $0.015 per million tokens. MiniMax reports a processing speed of approximately 150 tokens per second, which the company claims is three times faster than the standard M3 model.
Performance benchmarks show the model scoring 62.2 on Automation-Bench v1.0.6 and 73.7 on DeepSWE v1.1. In visual tasks, it achieved 91.0 on BabyVision with tools. The company notes that costs per task remain below $0.05 across all effort levels.
The model is currently available on the MiniMax platform and through the MiniMax Code desktop application. Model weights are scheduled for release on October 23, though licensing details have not yet been disclosed.