

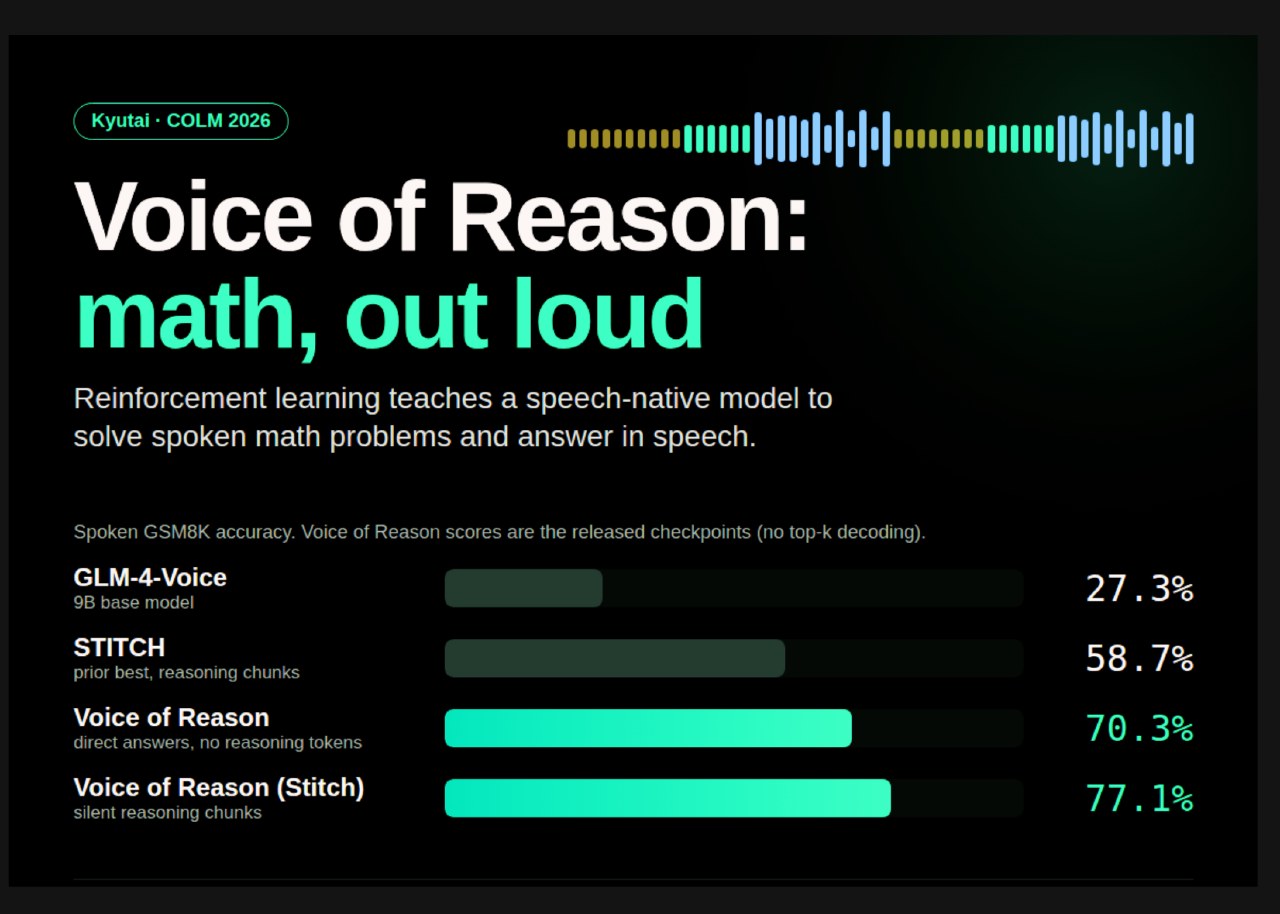
Kyutai has introduced Voice of Reason, a speech-native model designed to solve spoken mathematical problems using reinforcement learning. The model utilizes the GLM-4-Voice architecture, inheriting its license and requirements for a speech tokenizer and decoder. Currently, the model is available for self-hosting, with Kyutai demonstrating deployment on a single H100 GPU.
The training process involved 16 H100 GPUs and 1,500 reinforcement learning updates. The model employs a group-relative REINFORCE objective, omitting PPO clipping and KL regularization. Its output structure interleaves 13 text tokens with 26 audio tokens. The research team describes this as the first application of reinforcement learning to math reasoning within speech-native models.
Performance metrics show the base GLM-4-Voice model scoring 27.3% on the GSM8K benchmark, while the STITCH method previously reached 58.7%. The new Voice of Reason checkpoints achieved scores of 70.3% and 77.1% without top-k decoding. Evaluation was conducted using GPT-4o as a judge, with audio inputs generated by GPT-4o-mini-TTS.



