The DeepSeek V4.1-Flash model features 552 billion parameters and utilizes a Mixture-of-Experts architecture. It incorporates a redesigned Causal Encoder-Decoder system with 8 billion input and 16 billion output parameters, optimized for high-throughput token generation and visual perception tasks.
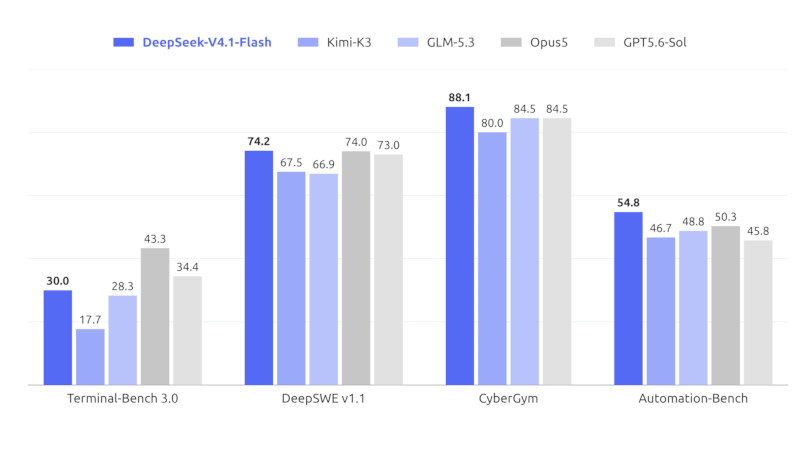
In performance benchmarks, the model achieved 74.2 points in DeepSWE v1.1 and 88.1 points in CyberGym, outperforming several competing models. In Terminal-Bench 3.0, it scored 30 points, trailing behind GPT-5.6-Sol and Claude Opus 5 but surpassing GLM-5.3 and Kimi K3.
The developer reduced KV-cache usage, resulting in four times lower HBM memory consumption and eight times less SSD storage requirements. This optimization aims to lower operational costs for AI agents by reducing the expenses associated with cache-hit request processing.
DeepSeek is phasing out the V4-Flash, V4-Flash-Vision-Exp, and V4-Pro models. Starting September 14, all requests to V4-Pro will be redirected to V4.1-Flash. The new model is currently supported by partners including WorkBuddy, CodeBuddy, and OpenCode.
Access is available via the DeepSeek API using the deepseek-flash identifier. Pricing is dynamic, with off-peak rates 50% lower than peak hours. Off-peak costs are $0.003 per million tokens for cache-hit inputs, $0.15 for non-cache, and $0.60 for output tokens.