

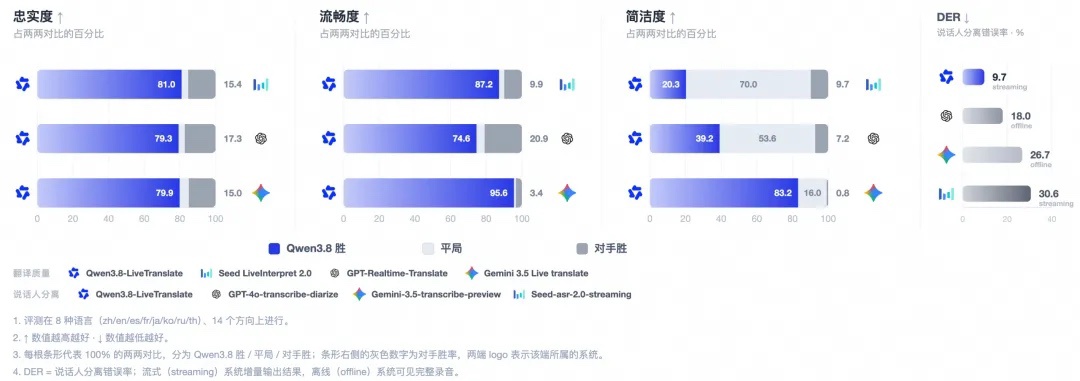
Alibaba has introduced Qwen3.8-LiveTranslate, a new large language model designed for real-time simultaneous interpretation. The model utilizes an Interleave architecture to integrate streaming comprehension, text output, and voice generation, reducing the average latency per character from 2.8 seconds to 2.3 seconds.
The system features a Hybrid MoE-based Thinker–Talker dual-module design. The Thinker module processes video, audio, and text within a single causal sequence, while the Talker module synthesizes the translated speech while preserving the original speaker's voice characteristics.
Qwen3.8-LiveTranslate supports 60 languages and has been evaluated on the Omnilingua-MSpeaker dataset, which covers 14 language directions. The model demonstrated superior performance in translation fidelity, fluency, conciseness, and speaker diarization error rates compared to current industry standards.
In tests conducted on the FLEURS audio dataset across 70 language directions, the model outperformed previous generations and mainstream systems in translation quality, latency, speech recognition accuracy, and speech synthesis quality.



