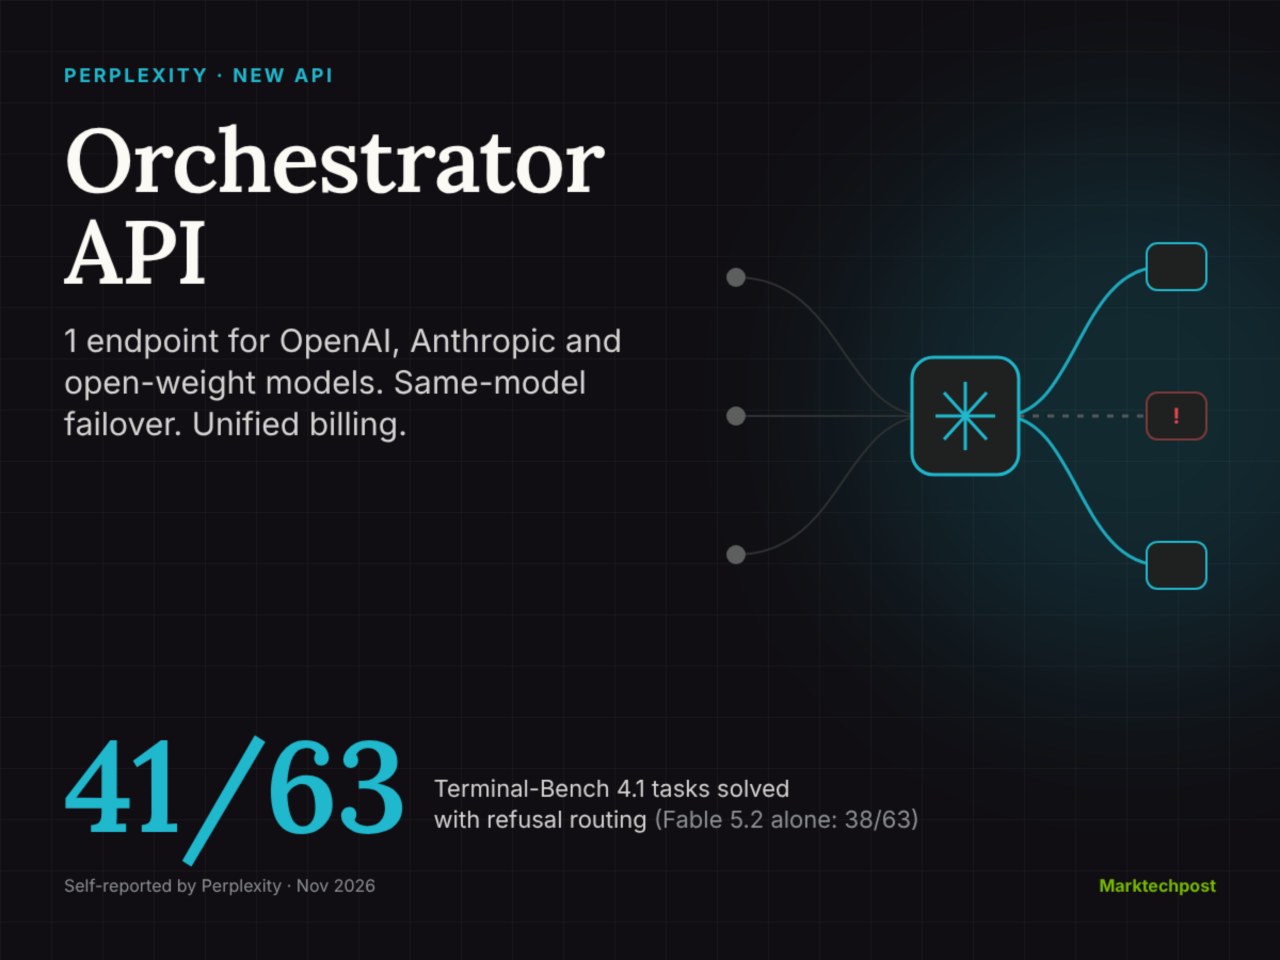
Perplexity has introduced the Orchestrator API, a hosted inference gateway that aggregates multiple models under a single base URL. The service supports frontier models from OpenAI, Anthropic, Google, and xAI, as well as open-weight models like GLM, Kimi, and DeepSeek. It is compatible with OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages formats.
The platform features a failover mechanism that automatically switches between providers if a request fails. For instance, a Claude request can be rerouted from Anthropic to AWS Bedrock. According to internal measurements taken from October 4 to November 2, 2026, this approach resulted in higher success rates and more stable performance compared to relying on a single provider.
The API includes a routing feature currently in preview, which allows users to define a default model and up to five custom routes. A decision model analyzes the conversation to select the appropriate route. Perplexity also offers built-in profiles such as Lower cost, Balanced, and Higher quality, with traffic defaults set to GPT-6.1 Sol and GPT-6 Luna.
Billing is based on the per-token rate of the model that provides the final response, with no additional platform fees applied. Costs are deducted from prepaid Perplexity API credits, which are also available for purchase via AWS Marketplace. For example, the perplexity/glm-5.3 model is priced at $1.40 for input and $4.40 for output per million tokens.