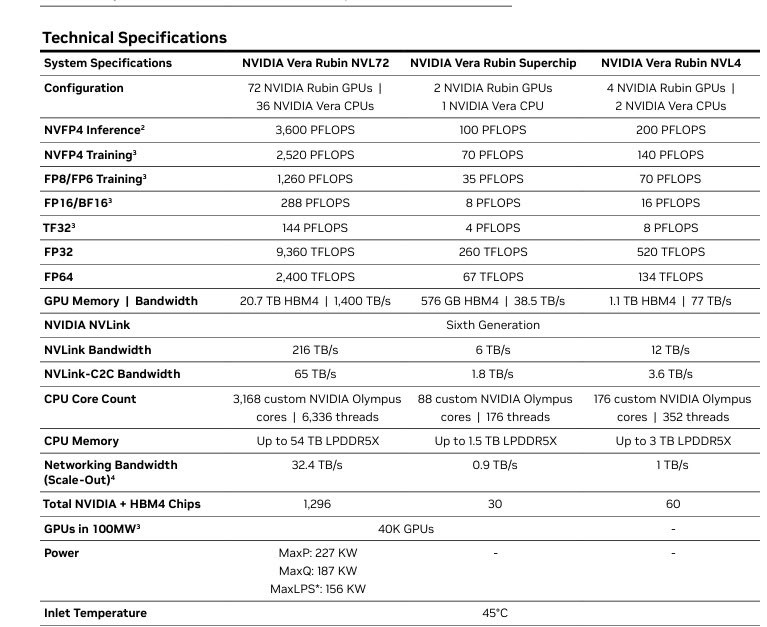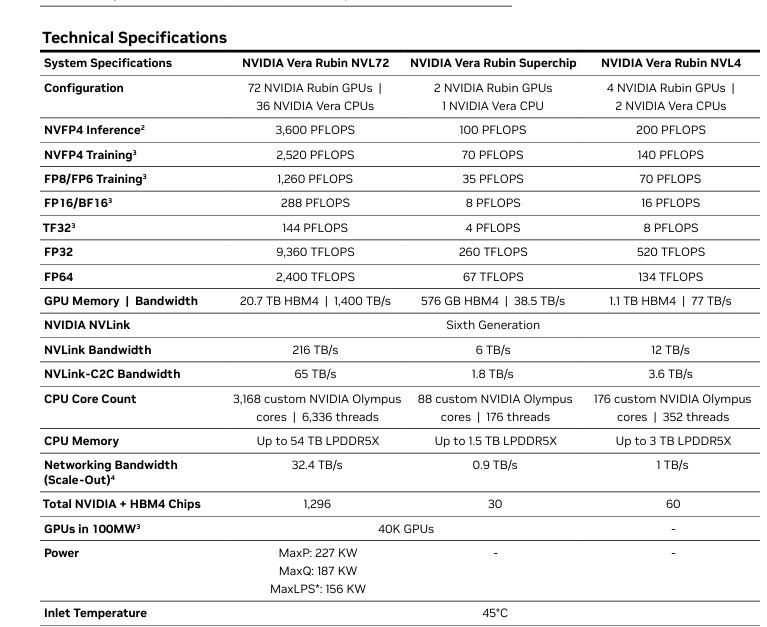
Nvidia has introduced the Vera Rubin NVL72 supercomputer, which integrates 72 Rubin GPUs and 36 Vera CPUs within a single NVLink domain. The system is designed to train a 10-trillion-parameter model on 100 trillion tokens in one month, requiring approximately 75% fewer GPUs than the previous Grace Blackwell NVL72 configuration.
Each GPU in the new architecture features 288 GB of HBM4 memory. Nvidia has implemented updated precision formats and new interconnectivity designs to improve energy efficiency. The company projects that inference costs on the Vera Rubin NVL72 will be one-tenth of the price per million tokens compared to the Blackwell racks.
Independent testing confirms performance gains. According to the MLPerf Inference v6.1 benchmarks from September 2026, the system demonstrated up to 3.7 times higher throughput on the Qwen3-VL task compared to the GB300 NVL72. Artificial Analysis data indicates a 5.7 times increase in throughput per megawatt for agentic AI workloads.
Production shipments of the new hardware began in the fall of 2026. The platform is supported by more than 80 MGX partners, including major cloud providers Google Cloud and Microsoft Azure.