

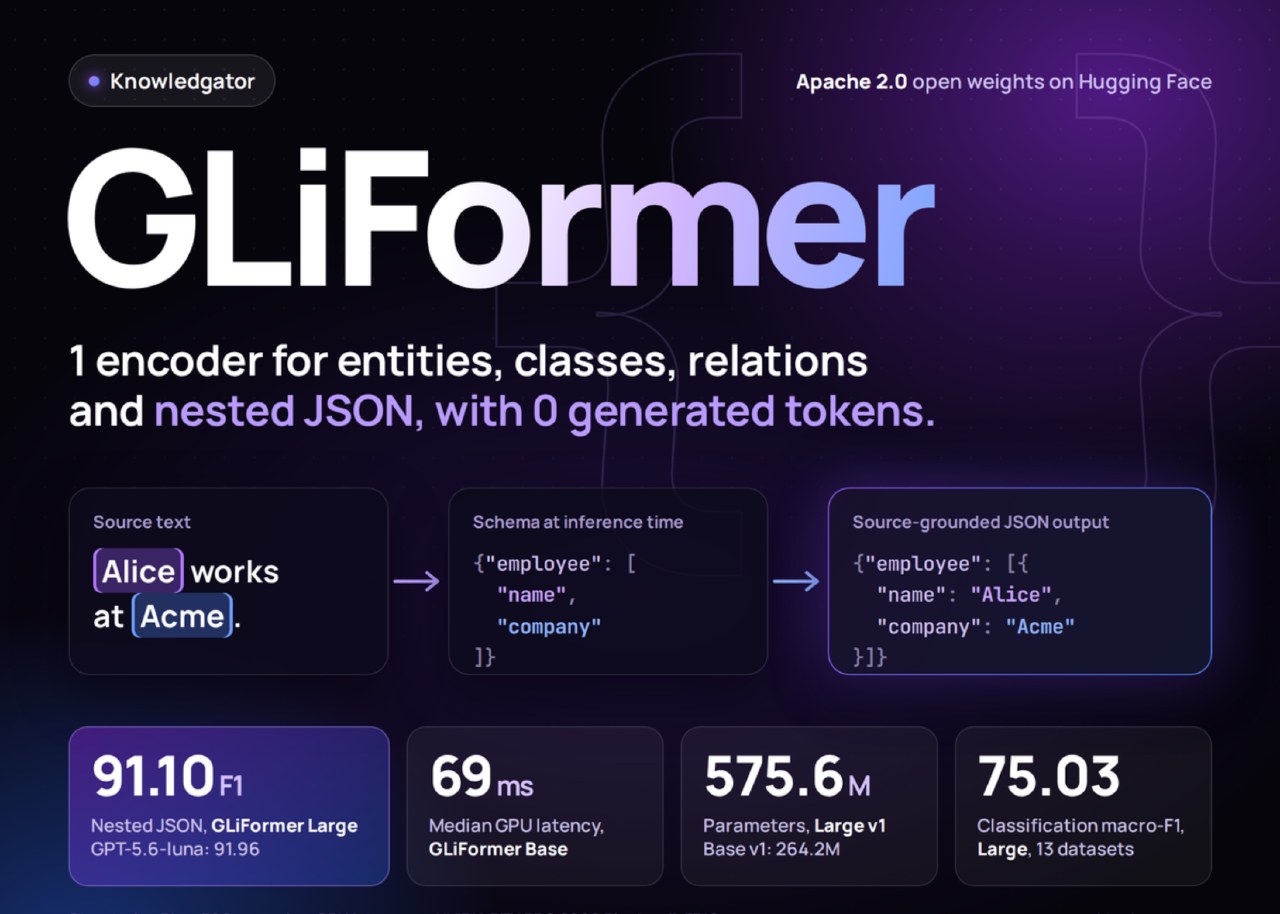
Knowledgator has released GLiFormer, an encoder model with 575 million parameters designed for nested JSON extraction. The model operates without token generation, avoiding the overhead of traditional LLM output methods. It is available under the Apache 2.0 license and can be installed via pip.
The architecture builds on GLiNER, utilizing an anchor-based approach for label matching. It processes source text once, allowing multiple schemas to run as task-local groups. The v1 checkpoints include five heads: NER, classification, joint relations, multilevel structuring, and embeddings, supporting a 12-word maximum span width.
The base model uses a DeBERTa backbone pretrained on 100 billion tokens. Training involved 1,357,671 examples for multitask learning and 372,090 for post-training. The Large version reportedly outperforms Gemma-4-E4B while using approximately 14 times fewer parameters.
Performance testing on 40 documents showed a median latency of 69 ms on an NVIDIA RTX PRO 6000 Blackwell GPU in FP16 and 547 ms on an 8-thread AMD EPYC 9B45 CPU in FP32. The company estimates speed improvements of up to 95.8 times compared to standard LLM generation processes.



