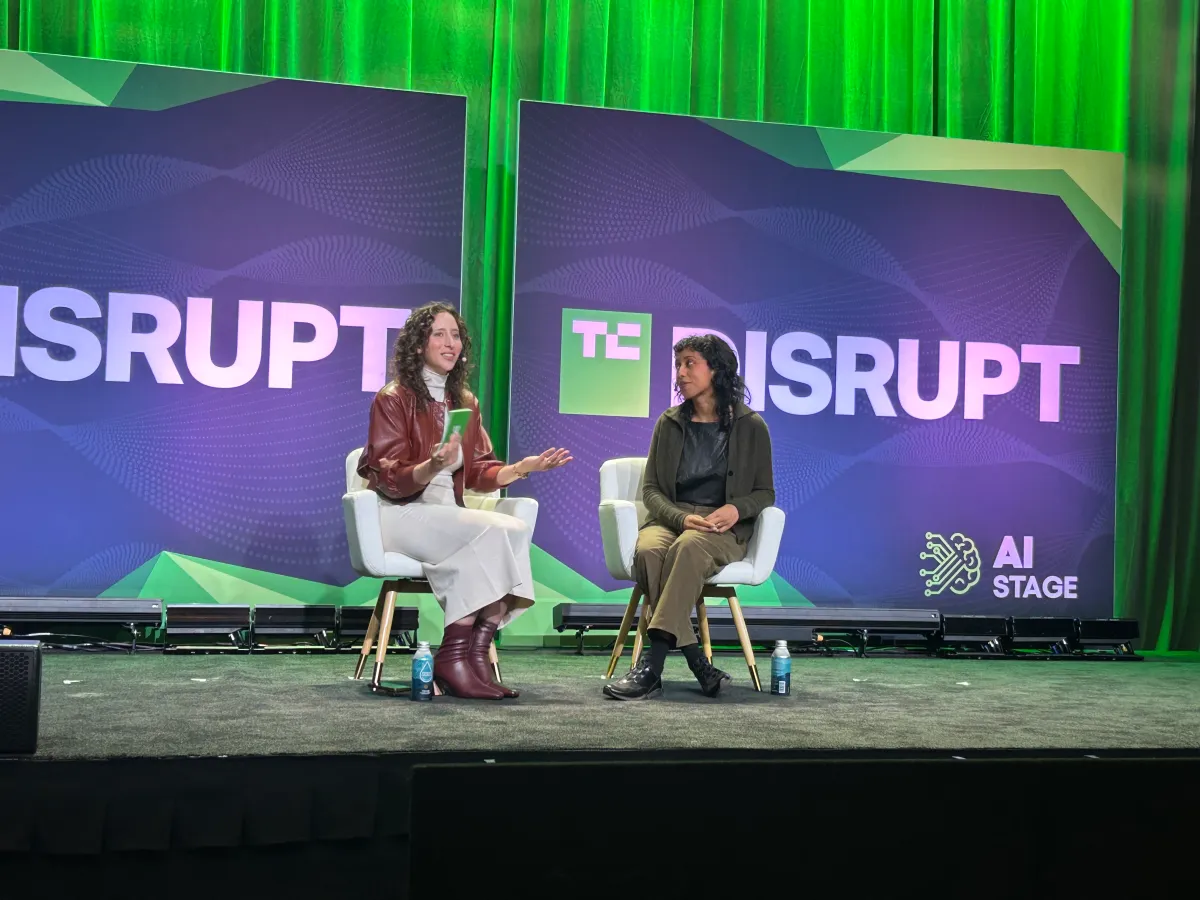
Irene Solaiman, chief policy officer at Hugging Face, stated that current AI model benchmarking lacks the consistency required for reliable industry standards. She emphasized that reproducibility remains a significant challenge, noting that open weights are essential for verifying evaluation results.
The industry is currently debating the effectiveness of embedded evaluators, which involve third-party observers monitoring AI organizations. Solaiman highlighted that there is no standardized framework to determine which evaluators are qualified for specific tasks, leading to concerns about their neutrality.
Recent industry trends show a shift from testing individual models to evaluating entire systems, including harnesses and agents. Solaiman noted that a weaker model paired with a superior harness can outperform a frontier model, making holistic agent evaluations increasingly critical.
Developing comprehensive evaluations for agents is both complex and costly. Solaiman concluded that the current evaluation landscape is fragmented, suggesting that a uniform, industry-wide approach is necessary to maintain the utility of benchmarking tools.