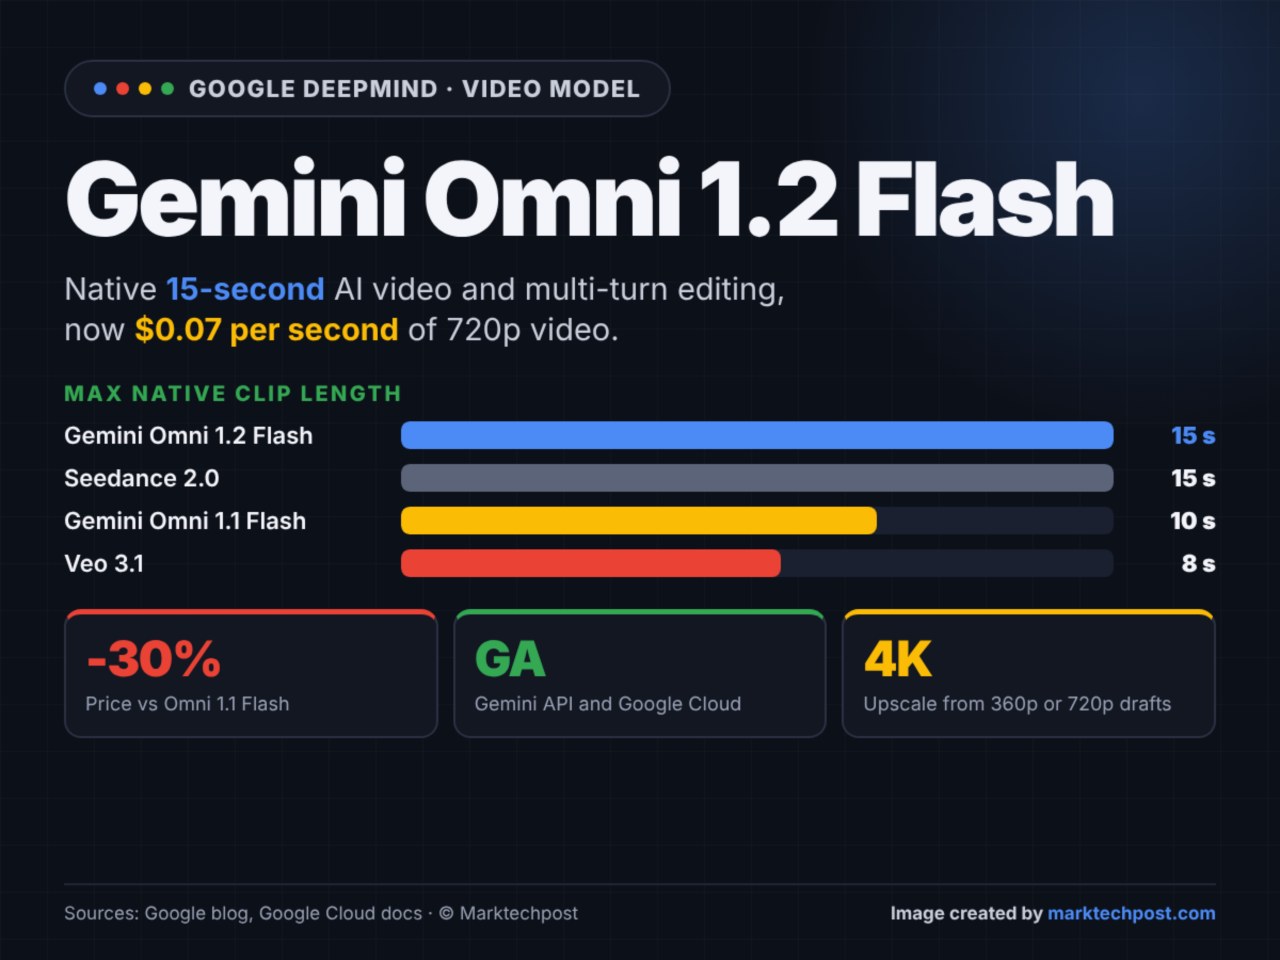
Google DeepMind has introduced Gemini Omni 1.2 Flash, a multimodal model capable of processing text, images, audio, and short video clips to generate video content with sound. The model supports multi-turn conversational editing, allowing users to modify specific elements like backgrounds, lighting, or product placement within a 15-second clip without re-uploading previous versions.
The pricing for Gemini Omni 1.2 Flash is set at $0.07 per second for 720p video, which is a reduction from the $0.10 per second charged for the previous 1.1 version. A complete 15-second 720p clip costs approximately $1.05. Users of Google Vids can generate these clips at no extra cost, and all outputs are marked with a SynthID watermark.
The development workflow for the model emphasizes cost efficiency by allowing users to draft content at lower resolutions before upscaling to 1080p or 4K. Editing is managed through the Interactions API, which uses a previous_interaction_id to maintain continuity across edits. Provisioned Throughput options are available for enterprise users.
While Google has not released official benchmark scores for version 1.2, it highlights performance improvements through side-by-side comparisons with the 1.1 model. Early feedback from partners, including invideo and QuickFrame AI, indicates that the model follows prompts accurately and is suitable for creating connected TV advertisements.