

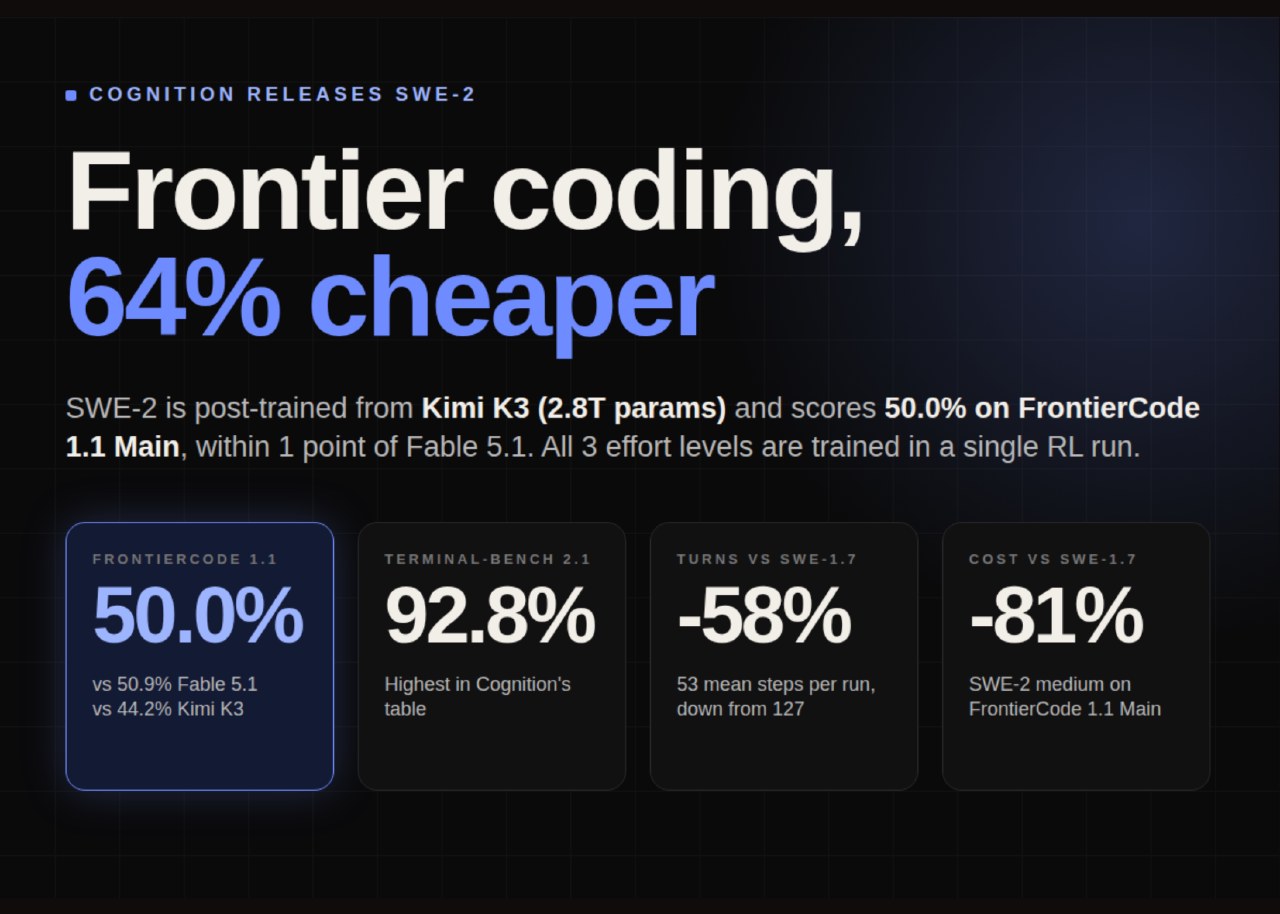
Cognition has launched SWE-2, a coding model post-trained on Kimi K3. The model is currently available exclusively within the Devin platform, including its Desktop and CLI versions, with Web and Fusion integrations planned. It does not offer open weights or a standalone API.
The model utilizes reinforcement learning scaled to a multi-trillion-parameter regime, building on the architecture of its predecessor, SWE-1.7. Cognition reports that the new RL algorithm trains across three effort levels simultaneously, allowing the cost-performance frontier to shift as a whole.
On the company's internal FrontierCode benchmark, SWE-2 matches the performance of Fable 5.1 while reducing costs by 64%. Compared to SWE-1.7, the medium effort version of SWE-2 achieves higher scores on FrontierCode 1.1 Main while requiring 58% fewer turns and costing 81% less.
Technical optimizations include a prefill delayer that boosts tokens per second by 10 to 20% and the use of DSpark speculative decoding. The company also implemented quantization-aware training with NVFP4 and FP8 kernels to manage memory usage and minimize training-inference mismatches.
Cognition expanded its RL environments threefold and developed a flywheel system to refine verifiers using earlier checkpoints. In trustworthiness evaluations, SWE-2 achieved a 98% pass rate on politically sensitive questions regarding China across English, Simplified Chinese, and Traditional Chinese.



