

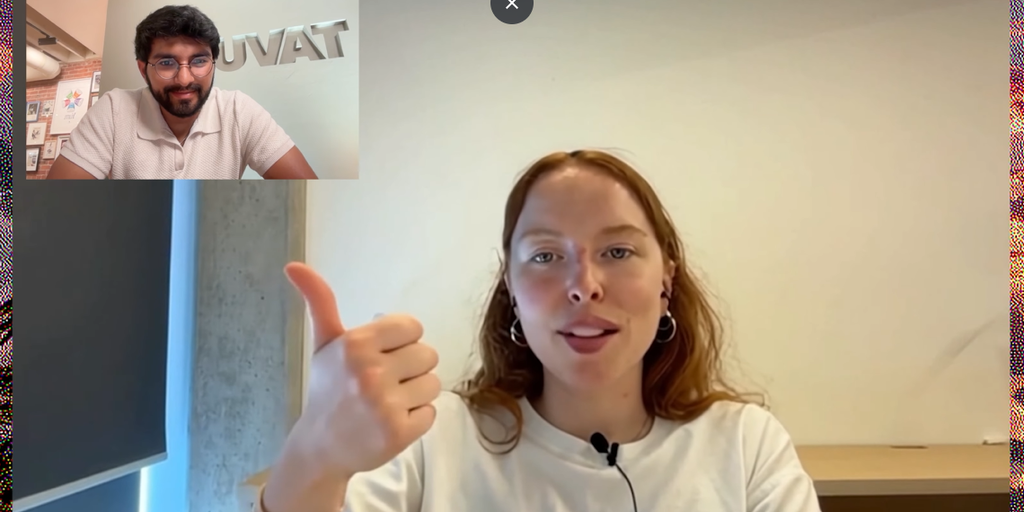
AI startup Tavus introduced its new Human Interaction Model, Griffin, on October 1. The company claims the model is designed to handle face-to-face conversations by processing expressions, pauses, and speech in real time. The system operates in full-duplex mode, allowing it to listen and speak simultaneously with an average audio-to-video delay of 0.43 seconds on NVIDIA H100 chips.
In internal tests conducted by Tavus, the Griffin-Lite version convinced 26 out of 54 participants that they were speaking to a human during one-minute video calls. This represents a 48% success rate, compared to 2.4% for the company's previous system. The company noted that participants were not informed they might be interacting with an AI, and those who grew suspicious typically did so within 20 seconds.
The model currently leads the NVIDIA VideoFDB benchmark for live audio and video interaction. On the generation track, Griffin-Lite scored 3.83, while the human reference scored 3.92. On the perception track, the model achieved 3.73 against 4.20 for the human baseline. Tavus stated that these evaluations were performed independently by NVIDIA.
Tavus is currently restricting access to Griffin-Lite to select testers via a research preview. The company stated that it is working on safety measures and disclosure features before a wider public release. In November 2025, the startup raised $40 million in a Series B funding round led by CRV.



