

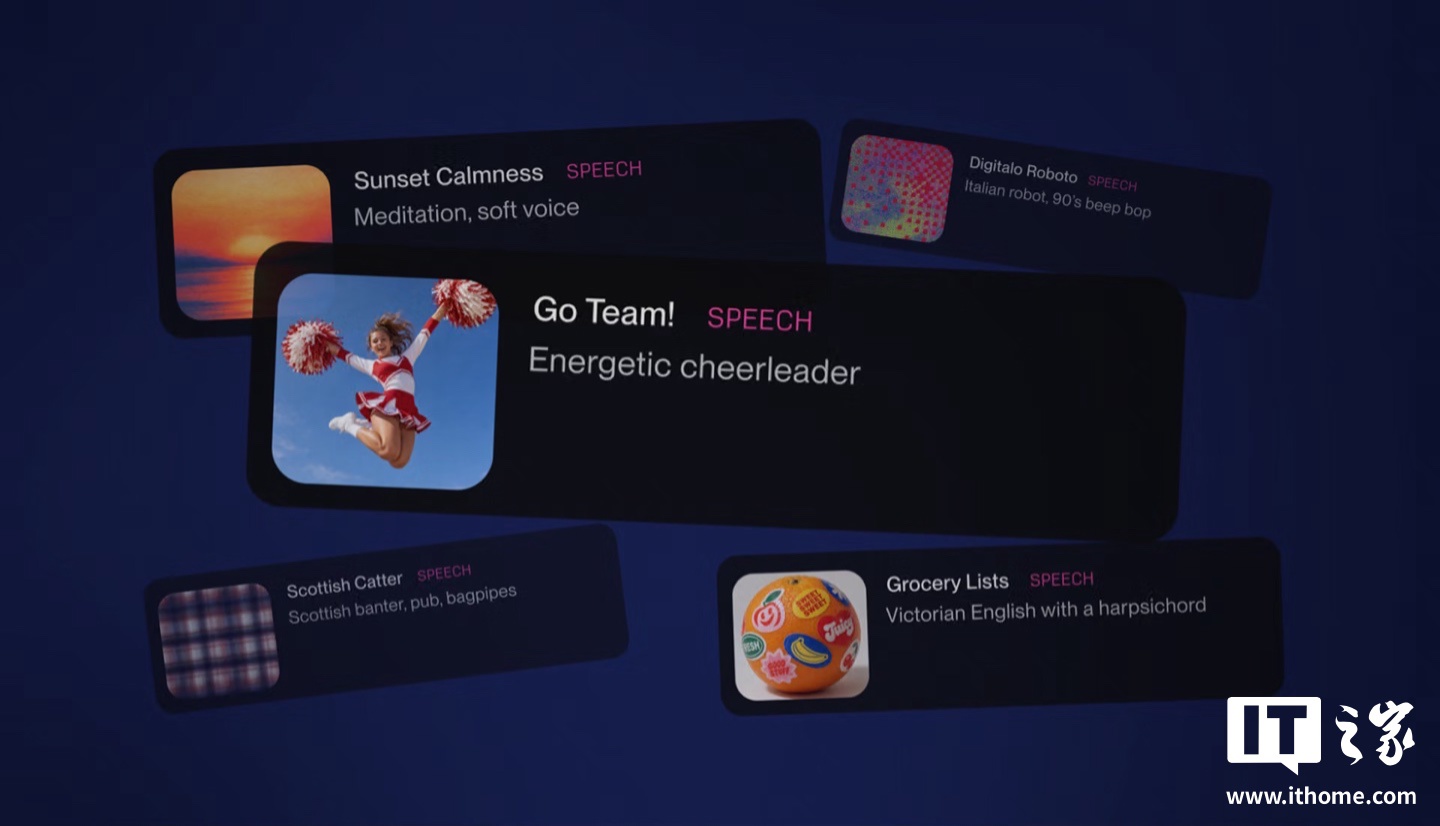
The AI music creation platform Suno has introduced a new feature called Speech. The company describes this as the first audio model capable of generating speech and music as a single, cohesive track. Unlike traditional workflows that combine text-to-speech with background music, this model uses an end-to-end generation process.
The feature allows users to create audio content by inputting text, such as a poem or a creative idea, and specifying the desired voice and musical style. Suno has moved the tool into public beta following a month of testing with a limited group of users.
The company acknowledged several limitations in the current beta version. Users may encounter occasional inconsistencies in accents, such as shifts between British and Australian pronunciations. Additionally, the model may produce overly dramatic intonations or pauses, which can lead to slower pacing in the generated audio.



