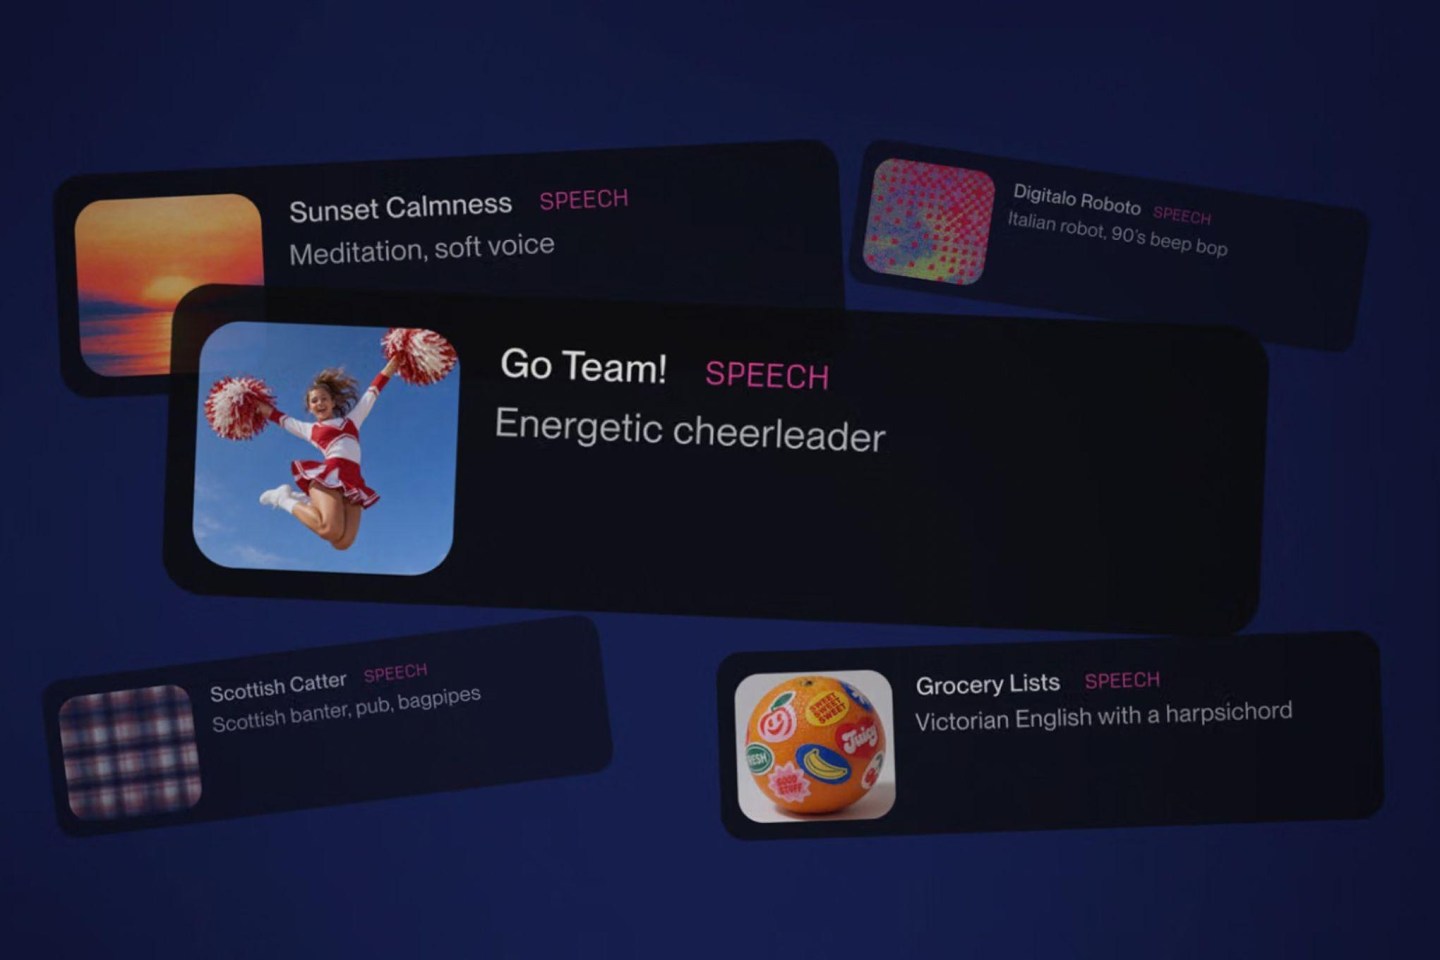
The AI music generation platform Suno has launched a beta version of its Speech feature, marking the company's expansion into spoken audio. This tool allows users to generate voice content based on text prompts, poems, or full scripts while simultaneously creating an original background music track.
The feature is available on both the web and mobile versions of Suno, including for free users. The platform offers two modes: a simple mode for text-based descriptions and an advanced mode that allows users to customize voice gender, style, and variability. Users can also opt to disable the background music to generate voice-only audio.
The maximum duration for a single generated audio clip is approximately 8 minutes. Chief Product Officer Jack Brody noted that while music remains the core of the platform, the company aims to support broader forms of human expression, such as meditation guides, storytelling, and motivational speeches.
Suno stated that the feature underwent a month of internal testing before the current public release. The company is actively collecting user feedback to refine the model, acknowledging that the beta version may currently exhibit issues with accent consistency, pacing, and emotional expression.