

Smart Engines developers are optimizing neural networks for local document processing on mobile devices. The team focuses on balancing high performance with limited computational resources, often employing quantization techniques to transition from floating-point calculations to 8-bit integers.
The company previously introduced 4.6-bit networks, which provide speed comparable to 4-bit models while maintaining higher accuracy. The new approach shifts focus from bit-width reduction to the method of accumulating multiplication results within the network.
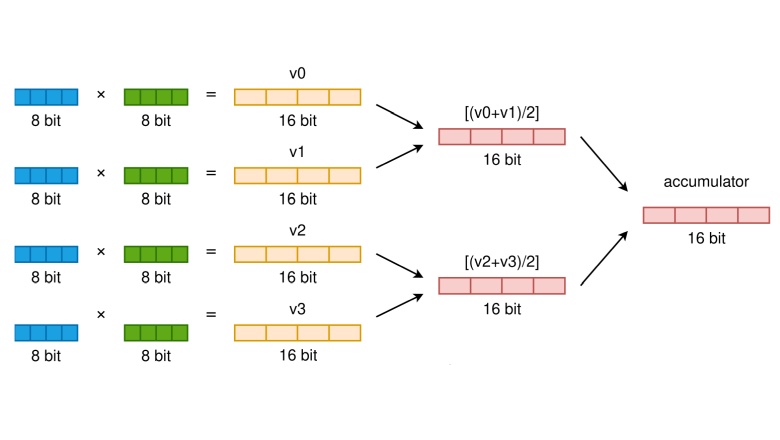
The proposed algorithm replaces standard summation with sequential tree-based averaging. This technique allows intermediate results to remain in a 16-bit format for a longer duration, enabling more efficient utilization of SIMD registers during the computation process.
Experimental tests conducted on ARM NEON architecture demonstrate that this method reduces the time required for matrix multiplication. The team is currently evaluating the resulting error rates, their impact on overall network accuracy, and the potential for recovery through fine-tuning.


