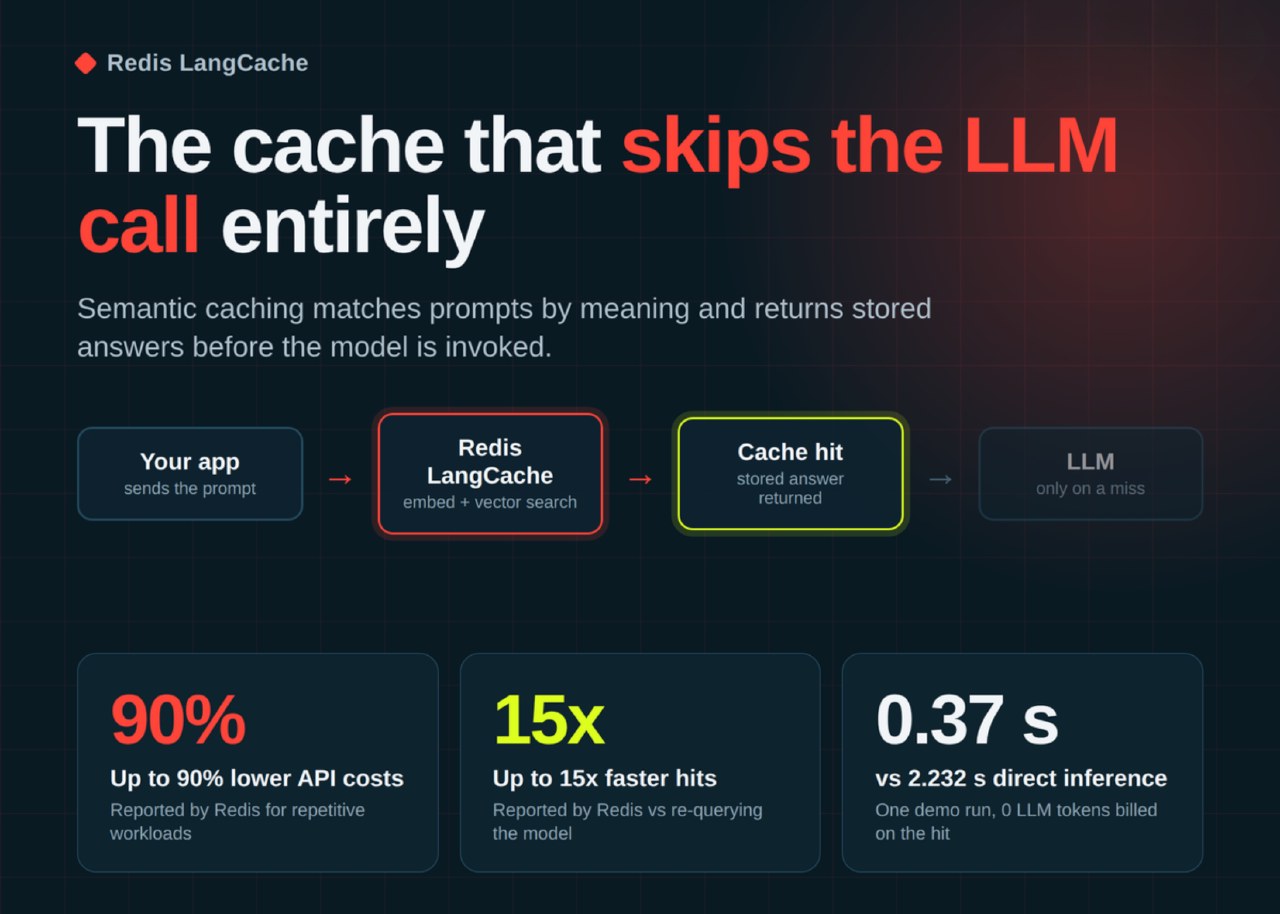
Redis has launched LangCache, a managed semantic cache now available in public preview on Redis Cloud. The service integrates with LLM providers to store generated responses, allowing systems to bypass redundant model calls. It is accessible via a REST API with dedicated SDKs for Python and JavaScript.
The architecture utilizes a vector database to identify similar queries, applying similarity thresholds and TTL policies to manage cache hits. By storing responses directly, LangCache eliminates the need to process input and output tokens for repeated questions, which can reduce LLM API costs by up to 90%.
Performance tests indicate that cache hits can be up to 15x faster than direct inference. In a demo, a cached response was returned in 0.37 seconds compared to 2.232 seconds for a standard call. The platform also includes monitoring tools for hit rates and savings within the Redis Cloud console.
Early adopters like Mangoes.ai report a 70% hit rate, leading to a 70% reduction in LLM spending and 4x faster response times. Redis emphasizes that data remains on customer servers and is not used for model training. Users can configure access scopes, custom filtering, and data isolation.